
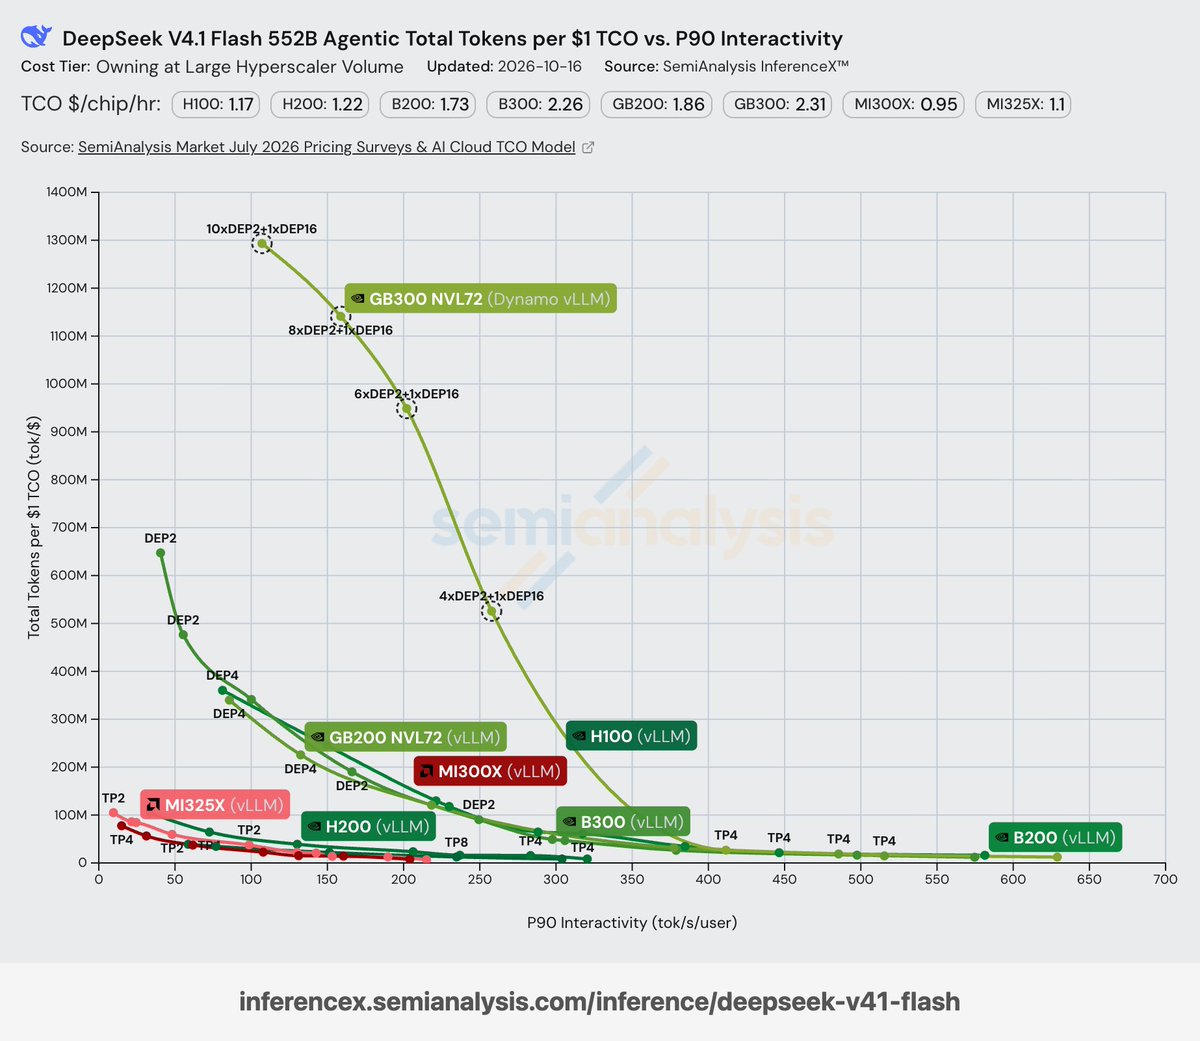
Following the release of DeepSeek-V4.1-Flash-1017, vLLM announced Day-0 serving optimization delivering 1.3B tokens per dollar TCO and 830K tok/s per GPU at 100 tok/s/user on SemiAnalysis AgentX (5x agentic throughput gain since Day 0), while OpenRouter launched live multi-provider routing starting at $0.10/M input and $0.50/M output tokens.
Key Takeaways
- ✓vLLM delivers 830K tok/s per GPU (cached + input + output) at 100 tok/s per user and 1.3B tokens/$ TCO on SemiAnalysis AgentX for DeepSeek-V4.1-Flash-1017 (5x faster since Day 0)
- ✓DeepSeek-V4.1-Flash-1017 reaches 77.0% on DeepSWE v1.1 (beating Claude Opus 5 at 74.0%), 68.2% on NL2Repo-Bench, and 72.1% on Apex Bench with shorter agentic outputs
- ✓Live on OpenRouter from $0.10/M input and $0.50/M output tokens, while DeepSeek's official API alias deepseek-flash remains at $0.15/M input and $0.60/M output
Not enough VRAM? Compare cloud API and self-hosting costs
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Core Background & Industry Pain Points
In production deployments of long-horizon coding agents and automated engineering workflows (such as DeepSeek Harness, Tencent CodeBuddy, and Claude Code), a single task routinely spans dozens to hundreds of iterative tool-call, environment-feedback, and context-append cycles. While DeepSeek-V4.1-Flash-1017 substantially shortens redundant chain-of-thought outputs and improves tool accuracy on the model side, serving engines running high-concurrency agent loops still face three critical bottlenecks: memory-bandwidth saturation from interleaving up to 1M-token shared prefixes with incremental decoding, cross-GPU communication latency in Mixture-of-Experts (MoE) routing, and minimizing Total Cost of Ownership (TCO) per million tokens while guaranteeing an interactive 100 tok/s per-user SLA.
Architectural Highlights & Core Mechanisms
Tailored for the asymmetric MoE and compressed KV-cache architecture of DeepSeek-V4.1-Flash-1017, the vLLM team delivered Day-0 kernel and scheduler co-optimizations alongside immediate multi-provider routing on OpenRouter:
- FlashMLA & Zero-Overhead Prefix Caching for Agent Loops:
vLLMtightly integrates customFlashMLAattention kernels with asynchronous block-level Automatic Prefix Caching, scheduling cached prefix tokens, new input tokens, and decoded output tokens in a unified high-throughput pipeline that eliminates redundant prefill overhead across multi-turn trajectories. - Shorter Output Trajectories & Compute-Communication Overlap: Combining
DeepSeek-V4.1-Flash-1017's more concise token generation withvLLM's dual-microbatch All-to-All communication overlapping cuts per-step agent latency, driving a 5x increase in end-to-end agentic throughput since Day 0 of the V4.1-Flash series. - Zero-Friction OpenRouter Routing & Native Search/Fetch APIs:
OpenRouterlaunched live routing underdeepseek/deepseek-v4.1-flash-1017, while DeepSeek's official API retains the drop-indeepseek-flashalias at unchanged pricing alongside newly opened in-house AI-nativeSearchandFetchAPIs indexing hundreds of billions of web pages with built-in SEO spam filtering.
Authoritative Benchmarks & Empirical Comparisons
According to vLLM's SemiAnalysis AgentX serving evaluation and official DeepSeek-V4.1-Flash-1017 benchmarks:
- SemiAnalysis AgentX Throughput & TCO Record: At a strict interactive SLA of 100 tok/s per user,
vLLMservingDeepSeek-V4.1-Flash-1017achieves 830K tok/s per GPU (combined cached + input + output tokens) and delivers 1.3 billion tokens per dollar TCO, marking a 5x agentic throughput improvement since initial launch. - Coding & Agentic Benchmark Gains:
DeepSeek-V4.1-Flash-1017scores 77.0% on DeepSWE v1.1 (surpassingClaude Opus 5at74.0%), 42.3% on Terminal-Bench 4.0, 68.2% on NL2Repo-Bench, 60.5% on Automation-Bench, 72.1% on Apex Bench, and 44.0% on text-only HLE without tools (42.6% overall). - Disruptive Token Economics: Third-party providers on
OpenRouteroffer pricing as low as $0.10/M input tokens and $0.50/M output tokens, while DeepSeek's official API remains at $0.15/M input and $0.60/M output.
Developer Practical Guide & Quickstart
Infrastructure teams self-hosting the MIT-licensed weights (deepseek-ai/DeepSeek-V4.1-Flash-1017) can deploy the latest vLLM release with --enable-prefix-caching and the FlashMLA backend enabled to maximize multi-turn agent KV reuse. API developers using DeepSeek Harness v0.2.1-rc.1+, Tencent CodeBuddy, or OpenAI-compatible SDKs can immediately connect via deepseek-flash on DeepSeek's API or deepseek/deepseek-v4.1-flash-1017 on OpenRouter with zero code changes.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.