

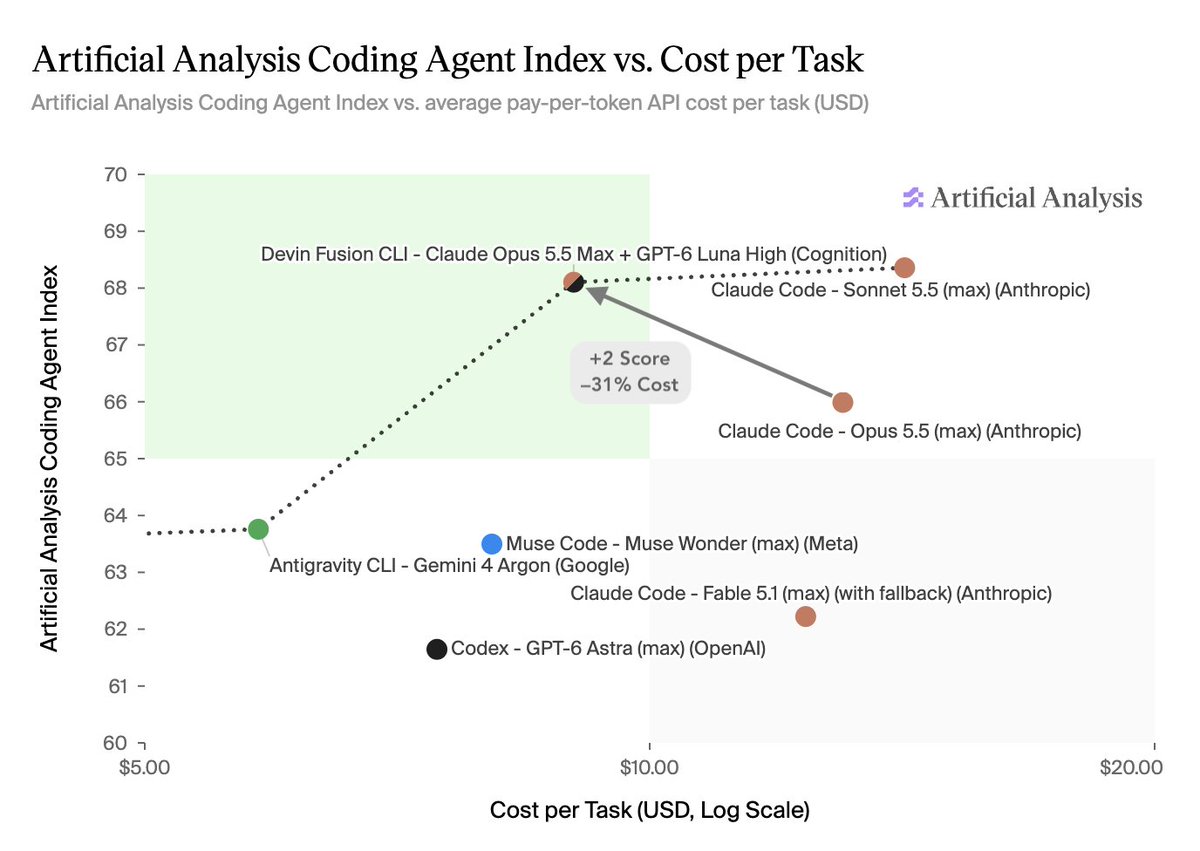
Cognition said on October 19 that Devin Fusion, pairing Claude Opus 5.5 as the lead with GPT-6 Luna as the sidekick, scored 68.1 on the Artificial Analysis Coding Agent Index v1.5. Artificial Analysis's current data puts it first, but only 0.1 ahead of Muse Code with Muse Wonder Full at 68.0, effectively a tie; Antigravity CLI with Gemini 4 Argon is third at 63.8. Cognition says the pairing costs 31% less per task than Claude Code with Opus 5.5 (vendor-reported). Fusion ships in Devin CLI and Desktop.
Key Takeaways
- ✓68.1 overall: DeepSWE v1.1 72.6, SWE-Atlas-QnA 69.6, Terminal-Bench v4 62.1, equally weighted (Artificial Analysis data).
- ✓Just 0.1 ahead of Muse Code with Muse Wonder Full (68.0); Antigravity CLI with Gemini 4 Argon 63.8, Codex with GPT-6.1 Sol (xhigh) 62.9.
- ✓Cost: Cognition says 31% lower per task than Claude Code with Opus 5.5 (vendor-reported).
- ✓Earlier, Fusion with Fable 5.1 + SWE-2 cut DeepSWE 1.1 cost per task from $14.63 to $7.88 (-46%) while scoring 63.1 vs 64.3.
- ✓Recommended pairing is Opus 5.5 + GPT-6 Luna, available by installing Devin CLI.
Key Decision Metrics at a Glance
Heavy Claude Code use: compare subscription limits and API bills
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Background
Coding-agent bills keep rising: frontier models are strong, but long tasks spend many tokens on reading code and running tests that don't need top intelligence. Simple difficulty routing fails because difficulty is often unknown until the code is read, and switching models mid-task breaks prompt caches. Cognition's Fusion, launched September 11, is a two-model harness built for this; its Artificial Analysis result was updated on October 19.
How it works
Fusion runs two agents with their own persistent context and tools. The lead, on a frontier model, owns planning, ambiguity and review; the cheaper sidekick explores, implements, runs tests and reports back from the lead's briefs. They exchange only briefs, results and feedback, so both benefit from caching. Cognition found pricier but more token-efficient models can lower total cost, and tunes brief detail and sidekick pushback per model pairing.
Benchmarks
Artificial Analysis data shows Fusion with Opus 5.5 Max + GPT-6 Luna High at 68.1: DeepSWE v1.1 72.6, SWE-Atlas-QnA 69.6, Terminal-Bench v4 62.1. Muse Code with Muse Wonder Full is second at 68.0, effectively tied; Antigravity CLI with Gemini 4 Argon scores 63.8 and Codex with GPT-6.1 Sol (xhigh) 62.9. The 31% lower cost per task vs Claude Code with Opus 5.5 is Cognition's claim.
Getting started
Install Devin CLI with curl -fsSL https://cli.devin.ai/install.sh | bash, pick Fusion, and choose a lead and sidekick; Cognition recommends Opus 5.5 + GPT-6 Luna. It suits long, multi-file repo tasks; compare cost per task on your own codebase rather than price per token.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.