AI Coding Live News

Artificial Analysis Launches the Diarization Index for Speech to Text: APIs Scored on Word Diarization Error Rate, NVIDIA Nemotron 3.5 Transcribe Leads at 3.3% Ahead of Voxtral Small Transcribe 3 at 7.5%

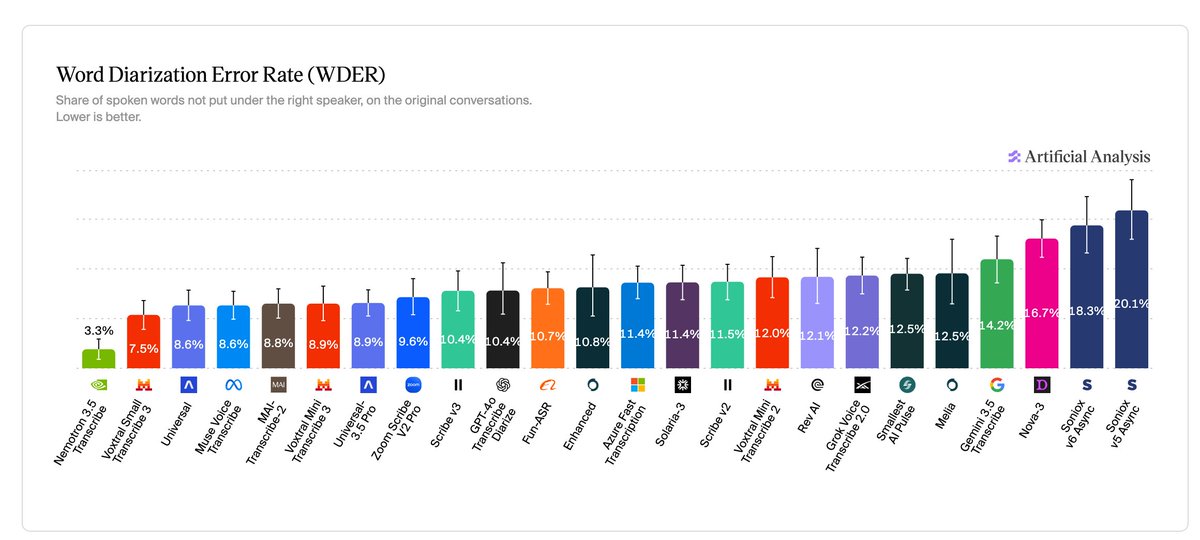
On November 13 Artificial Analysis published the Diarization Index, a benchmark for whether speech to text APIs attribute each word to the person who actually said it. It scores Word Diarization Error Rate (WDER), the share of words given to the wrong speaker or to no speaker, across 97 English conversations of two to eight people, averaging three speaker bands (2, 3-4 and 5-8) with equal weight. NVIDIA's open-weight Nemotron 3.5 Transcribe leads at 3.3%, ahead of Voxtral Small Transcribe 3 at 7.5%, the most accurate priced API; MAI-Transcribe-2 scores 8.8% and is one of the fastest.
Artificial Analysis Launches the Diarization Index for Speech to Text: APIs Scored on Word Diarization Error Rate, NVIDIA Nemotron 3.5 Transcribe Leads at 3.3% Ahead of Voxtral Small Transcribe 3 at 7.5%

Key Takeaways

  • The new metric is WDER = (wrong-speaker words + missed words) / scored reference words, lower is better; AA says it ranks on WDER instead of DER because for APIs DER mostly scores word timestamps rather than who spoke
  • The set has 97 conversations of about 2-9 minutes each, about 6.8 hours in total, mixing real and synthetic speech; most audio is proprietary and held out, plus about 126 minutes of public NOTSOFAR-1 meeting recordings
  • APIs are called directly with diarization switched on and are not told how many people are talking, with each conversation sent whole; price includes any separate diarization charge
  • Nemotron 3.5 Transcribe goes from 1.7% WDER with two speakers to 5.6% with five to eight; in the largest groups every other API gets more than 10% of words wrong
  • Voxtral Small Transcribe 3 scores 7.5% at $4.00 per 1,000 minutes; MAI-Transcribe-2 scores 8.8% at $1.67 and transcribes 93.7 seconds of audio per second of waiting; Nemotron 3.5 Transcribe is open-weight and has no listed price
Read full story
Linked Models & Agents:
⚡ Nemotron 3.5 Transcribe⚡ Voxtral Small Transcribe 3⚡ MAI-Transcribe-2🌐 Artificial Analysis🌐 NVIDIA🌐 Mistral AI🌐 Microsoft

ElevenLabs Launches Scribe v3 and Scribe v3 Live Speech-to-Text Models: 27% Fewer Word Errors Than v2 Across 102 Languages, First Realtime Speaker Diarization, and API Pricing of $0.20/$0.22 per Hour

On November 10 (02:10 on November 11 Singapore time) ElevenLabs released two speech-to-text models: Scribe v3 for recorded audio and Scribe v3 Live for realtime streams. By the vendor's numbers, Scribe v3 cuts word error rate (WER) by 27% versus Scribe v2 across 102 FLEURS languages, improving in every language, while Scribe v3 Live lowers semantic WER by 43% versus Scribe v2 Realtime and, for the first time, adds speaker diarization and context-aware turn detection to realtime transcription. Both models are live in ElevenAPI, where switching from v2 is a one-line model ID change; the API pricing page lists $0.20 per audio hour for v3 and $0.22 for v3 Live. Third-party evaluator Voice Arena tested v3 Live on 70+ hours of real phone calls and ranked it first in Romanian and Indian English.

ElevenLabs Launches Scribe v3 and Scribe v3 Live Speech-to-Text Models: 27% Fewer Word Errors Than v2 Across 102 Languages, First Realtime Speaker Diarization, and API Pricing of $0.20/$0.22 per Hour

Key Takeaways

  • Accuracy (vendor figures): Scribe v3 lowers WER by 27% versus v2 across 102 languages, with German -42%, Spanish -35%, English -23%, Thai -28%
  • Realtime: Scribe v3 Live cuts semantic WER by 43% and WER by 31% versus v2 Realtime, Greek improves 77%, and ElevenLabs cites about 150ms latency
  • Diarization: v3 makes 12% fewer errors than v2 and 17% fewer on recordings with 3+ speakers; v3 Live makes 39% fewer than the next-best realtime model, with a 3.1% English error rate
  • Pricing: $0.20 per audio hour for v3 and $0.22 for v3 Live on the API, plus $0.05/hour for keyterm prompting and $0.07/hour for transcript edits
  • Getting started: model IDs are scribe_v3 and scribe_v3_live; keyterm prompting takes up to 1,000 terms, and enterprise plans offer EU, India and Singapore data residency
Read full story
Linked Models & Agents:
⚡ Scribe v3⚡ Scribe v3 Live🤖 ElevenAgents🌐 ElevenLabs

Mistral Releases Voxtral 3 Audio Model Suite and Real-Time Voice-Agent API with Sub-500ms Latency

Mistral AI unveiled Voxtral 3, a production audio intelligence suite paired with a real-time Voice-Agent API. The lineup features the 4B-parameter Mini Transcribe, Small Transcribe 3, and a turn-key voice agent SDK built on LiveKit. Supporting transcription across 50 languages with diarization, multi-lingual TTS with emotional tags across 35+ languages, and 30-minute voice cloning, Voxtral 3 redefines voice AI economics. In Artificial Analysis independent benchmarks, Small Transcribe 3 secured rank #3 globally with a 2.1% error index (outperforming ElevenLabs Scribe v2), while Realtime Transcribe delivers sub-500ms latency at $0.04/min for full voice agent turns.

Mistral Releases Voxtral 3 Audio Model Suite and Real-Time Voice-Agent API with Sub-500ms Latency

Key Takeaways

  • Mistral AI launched the Voxtral 3 suite spanning transcription, emotional TTS, studio-grade voice cloning, and a LiveKit-powered Voice-Agent SDK
  • Artificial Analysis independently verified Small Transcribe 3 at a 2.1% error index, outperforming ElevenLabs Scribe v2 (2.2%) and Grok Voice 2.0 (2.3%)
  • Realtime Transcribe 3 achieves sub-500ms latency, delivering sub-second full conversational voice-agent turns
  • Aggressive pricing: Mini Transcribe starts at $0.0035/min, and managed voice agent sessions cost just $0.04/min paired with Mistral Small 4
Read full story

Mistral launches the Voxtral 3 speech model family and a voice agent SDK: transcription in 50+ languages, TTS at $13 per 1M characters, EU-hosted or self-deployed

On Oct 20 Mistral released Voxtral 3: the Voxtral Small/Mini Transcribe 3 speech-to-text models, Voxtral Mini Transcribe Realtime 3, the Voxtral Mini TTS 3 (Voxtral Speech 3) text-to-speech model, and a LiveKit-based voice agent SDK that streams listening, reasoning with tool calls, and speaking as one pipeline, with each turn completing in under a second per Mistral. Transcription covers 50+ languages with diarization and context biasing; TTS covers 35+ languages and 50+ dialects, plus Pro Voice cloning from 30 minutes of audio. It is live on the Mistral API (EU, US and global endpoints) and can be self-deployed.

Mistral launches the Voxtral 3 speech model family and a voice agent SDK: transcription in 50+ languages, TTS at $13 per 1M characters, EU-hosted or self-deployed

Key Takeaways

  • Multilingual transcription (vendor-reported): macro WER over 45 FLEURS languages is 4.1% (language forced) / 4.0% (inferred) for Voxtral Small Transcribe 3, tied with Microsoft AI Transcribe 2 and ahead of Scribe v2 (4.9%) and Whisper large-v3 (16.0%/14.9%)
  • Diarization (vendor-reported): cpWER of 18.4% for Small and 18.6% for Mini, vs 30.9% for the previous Voxtral Mini Transcribe 2 and 38.4% for Gemini 3.5 Transcribe
  • Pricing: Voxtral Mini Transcribe 3 is 4B parameters at $0.0035/min (docs list it as Public Preview with 32k context); Voxtral Speech 3 costs $13 per 1M characters
  • Realtime: Voxtral Mini Transcribe Realtime 3 runs below 500 ms latency; in Mistral's 35-language FLEURS chart the 480 ms setting scores 6.4% WER, still behind Gemini 3.5 Realtime Transcribe at 4.2%
  • The voice agent SDK is built on LiveKit with SIP telephony and WebRTC; each stage (LLM, voice, language) is swappable, and Pro Voice clones a voice from 30 minutes of audio
Read full story
Linked Models & Agents:
⚡ Voxtral Small Transcribe 3⚡ Voxtral Mini Transcribe 3⚡ Voxtral Mini Transcribe Realtime 3⚡ Voxtral Mini TTS 3🤖 Voxtral voice agent SDK🌐 Mistral AI🌐 LiveKit
ADSponsored

Hugging Face Transformers 5.18.0: Nemotron 3 streaming diarization; NemotronH Omni; HyperCLOVAX Vision V2; GTE

Hugging Face shipped transformers v5.18.0 on 2026-09-30 (PyPI 5.18.0): NVIDIA Nemotron 3 Diarization (streaming/offline, up to 8 speakers, 80 ms–30.4 s buffers), NemotronH Omni (joint text/image/video/audio), NAVER HyperCLOVAX Vision V2 (built-in <think> CoT), and GTE bidirectional encoders (RoPE + gated MLP; gte / snowflake-arctic-embed family). Official model_doc pages are live.

Hugging Face Transformers 5.18.0: Nemotron 3 streaming diarization; NemotronH Omni; HyperCLOVAX Vision V2; GTE

Key Takeaways

  • Release v5.18.0 at 2026-09-30T16:46:27Z; PyPI ~2026-09-30T16:45:57Z
  • Nemotron 3 Diarization: streaming+offline, ≤8 speakers, 80 ms–30.4 s buffers, 10 ms frame multiples (#49056)
  • NemotronH Omni: NemotronH + RADIO + optional Parakeet for joint text/image/video/audio (#46509)
  • HyperCLOVAX Vision V2 (NAVER) + GTE encoders (RoPE/gated MLP; gte / snowflake-arctic-embed family)
  • pip install -U transformers==5.18.0; docs for diarization/omni/gte linked above
Read full story
Linked Models & Agents:
⚡ Nemotron 3 Diarization⚡ Nemotron H Omni⚡ Hyperclovax Vision V2⚡ gte🌐 Huggingface🌐 Nvidia (NIM)🌐 Naver

xAI ships Grok Voice Transcribe 2.0: ~2× accuracy, $0.10/hr batch, AA streaming #1

SpaceXAI (xAI) launched Grok Voice Transcribe 2.0, claiming roughly 2× the accuracy of Transcribe 1.0 on customer-support calls, spoken credentials, and short voice commands at the same price. It ranks #1 for accuracy among 32 streaming transcription models on Artificial Analysis; short-phrase WER fell from about 20.6% to 6.8%. Features include streaming and batch modes, automatic language detection with mid-recording language switches, word-level timestamps and confidence, free speaker diarization, batch at about $0.10/hour and realtime streaming at about $0.20/hour, with existing Speech-to-Text API clients upgraded without code changes.

Key Takeaways

  • Claims ~2× accuracy vs Transcribe 1.0 on support calls, spoken credentials, and short commands at the same price.
  • #1 accuracy among 32 AA streaming transcription models; short-phrase WER ~20.6%→6.8%.
  • Batch ~$0.10/hr and streaming ~$0.20/hr, with diarization, language switching, word timestamps; existing API clients upgrade in place.
Read full story
Linked Models & Agents:
⚡ Grok Voice Transcribe 2🌐 xAI

Alibaba Qwen launches Qwen3.8-LiveTranslate for 60-language real-time interpretation

Qwen announced Qwen3.8-LiveTranslate, its next-generation real-time simultaneous interpretation model. An Interleave architecture improves faithfulness, fluency, and conciseness while cutting average lagging (LAAL) from 2.8s to 2.3s across 60 languages. New capabilities include real-time speaker diarization with more stable voice cloning, synchronized bilingual display, and long-context disambiguation for names and terminology.

Key Takeaways

  • Interleave architecture cuts average lagging (LAAL) from about 2.8s to 2.3s across 60 languages.
  • Real-time speaker diarization keeps each speaker's voice more stable in multi-party speech.
  • Adds synchronized bilingual display and long-context term disambiguation; try it on QwenCloud.
Read full story
Linked Models & Agents:
⚡ Qwen3 8 Livetranslate🌐 Alibaba🌐 Qwen

Meta ships Muse Voice Transcribe: real-time multilingual ASR with 20+ speaker diarization

Meta Superintelligence Labs launched Muse Voice Transcribe on September 1, its first real-time audio perception model: streaming ASR, diarization for 20+ speakers, and endpointing, with native code-switching, 70+ training languages (25 validated at launch), and hour-plus sessions. Meta says it ranks first on Artificial Analysis streaming speech-to-text as of September 1. It already powers Meta AI for Mac (hold Fn to dictate anywhere) and Muse Code, and is on the Meta Model API at $3 per 1,000 audio-minutes (~$0.18/hour).

Key Takeaways

  • Streaming ASR, diarization, and endpointing ship as one model without a post-process chain
  • Already live for system-wide Mac dictation and Muse Code; developers use the Meta Model API
  • API pricing is about $0.18/hour; adaptive delay trades latency for harder words
Read full story
Linked Models & Agents:
⚡ Muse Voice Transcribe⚡ Muse Spark🤖 muse-code🌐 Meta AI