AI Coding Live News

X Discussion: Jason Calacanis Says Under $40K a Year in AI Subscriptions Delivers $2M+ in Value and Has Automated at Least Seven Full-Time Jobs

Angel investor and This Week in Startups host Jason Calacanis posted on X on November 2 that he spends under $40K a year on tokens and subscriptions from Anthropic, Lovable, Grok Bot, ElevenLabs and other AI products, yet gets more than $2M in value at LAUNCH and This Week in Startups. He said they have automated at least seven full-time jobs and become 100% faster at the average task, and that the last 90 days changed more than the previous two years. Within about 9 hours the post drew about 2,200 likes and 230K views, with debate centered on AI ROI and job replacement. All figures are his own claims and have not been independently verified.

Key Takeaways

  • This is Calacanis's personal post, not official data or an announcement from any AI company; the $40K, $2M, seven jobs and 100% faster figures are self-reported with no public breakdown.
  • The original post (2026-11-02 05:27 UTC) had about 2,201 likes, 106 reposts, 244 replies, 42 quotes, 230K views and 715 bookmarks at fetch time.
  • Tools he named include Anthropic, Lovable, Grok Bot and ElevenLabs plus a long tail of other products; he also said anyone who has not used the last 90 days of products for at least 30 hours a week has no idea how profound this software is.
  • Supporters: entrepreneur Steven Cohn (@spcohn) quoted it saying his team has seen the same level of ROI; Farzad (@farzyness), with about 400K followers, quoted it saying "The ROI for AI is mind-boggling," drawing about 157 likes.
  • Skeptics: one user mocked posting "we automated seven full-time jobs" with a siren emoji like a product launch, noting that 30 hours a week of usage is itself like a new full-time job.
Read full story

ElevenLabs releases SFX v3 sound effects model: multi-part prompts, better music and vocals, now in ElevenAPI (limited access)

ElevenLabs' official account announced SFX v3 at 18:03 UTC on Oct 29, saying it creates richer, more precise sound effects from a single text prompt, with improved music and vocals, now available in ElevenCreative and ElevenAPI. Official docs list the model ID eleven_text_to_sound_v3 on the existing Sound Effects API, but v2 remains the default and v3 is in limited access and may not be available in every region.

ElevenLabs releases SFX v3 sound effects model: multi-part prompts, better music and vocals, now in ElevenAPI (limited access)

Key Takeaways

  • Model ID: eleven_text_to_sound_v3, on the same Sound Effects API as v2; switch by changing model_id, while eleven_text_to_sound_v2 stays the default
  • Docs list 4 improvements: several instructions in one prompt, music and vocal prompts, more natural output, and less clipping on high-frequency sounds like gongs, chimes and whistles
  • Limited access: accounts without access get an Unknown model error, and it may not be available in every region
  • Duration 0.1 to 30 seconds, billed at 40 credits per second when a duration is specified (Sound Effects endpoint rule), with loop for seamless looping
  • Benchmarks: no quantitative scores published; docs advise comparing v2 and v3 on your own prompts
Read full story
Linked Models & Agents:
⚡ SFX v3⚡ eleven_text_to_sound_v3🌐 ElevenLabs

Mistral Releases Voxtral 3 Audio Model Suite and Real-Time Voice-Agent API with Sub-500ms Latency

Mistral AI unveiled Voxtral 3, a production audio intelligence suite paired with a real-time Voice-Agent API. The lineup features the 4B-parameter Mini Transcribe, Small Transcribe 3, and a turn-key voice agent SDK built on LiveKit. Supporting transcription across 50 languages with diarization, multi-lingual TTS with emotional tags across 35+ languages, and 30-minute voice cloning, Voxtral 3 redefines voice AI economics. In Artificial Analysis independent benchmarks, Small Transcribe 3 secured rank #3 globally with a 2.1% error index (outperforming ElevenLabs Scribe v2), while Realtime Transcribe delivers sub-500ms latency at $0.04/min for full voice agent turns.

Mistral Releases Voxtral 3 Audio Model Suite and Real-Time Voice-Agent API with Sub-500ms Latency

Key Takeaways

  • Mistral AI launched the Voxtral 3 suite spanning transcription, emotional TTS, studio-grade voice cloning, and a LiveKit-powered Voice-Agent SDK
  • Artificial Analysis independently verified Small Transcribe 3 at a 2.1% error index, outperforming ElevenLabs Scribe v2 (2.2%) and Grok Voice 2.0 (2.3%)
  • Realtime Transcribe 3 achieves sub-500ms latency, delivering sub-second full conversational voice-agent turns
  • Aggressive pricing: Mini Transcribe starts at $0.0035/min, and managed voice agent sessions cost just $0.04/min paired with Mistral Small 4
Read full story

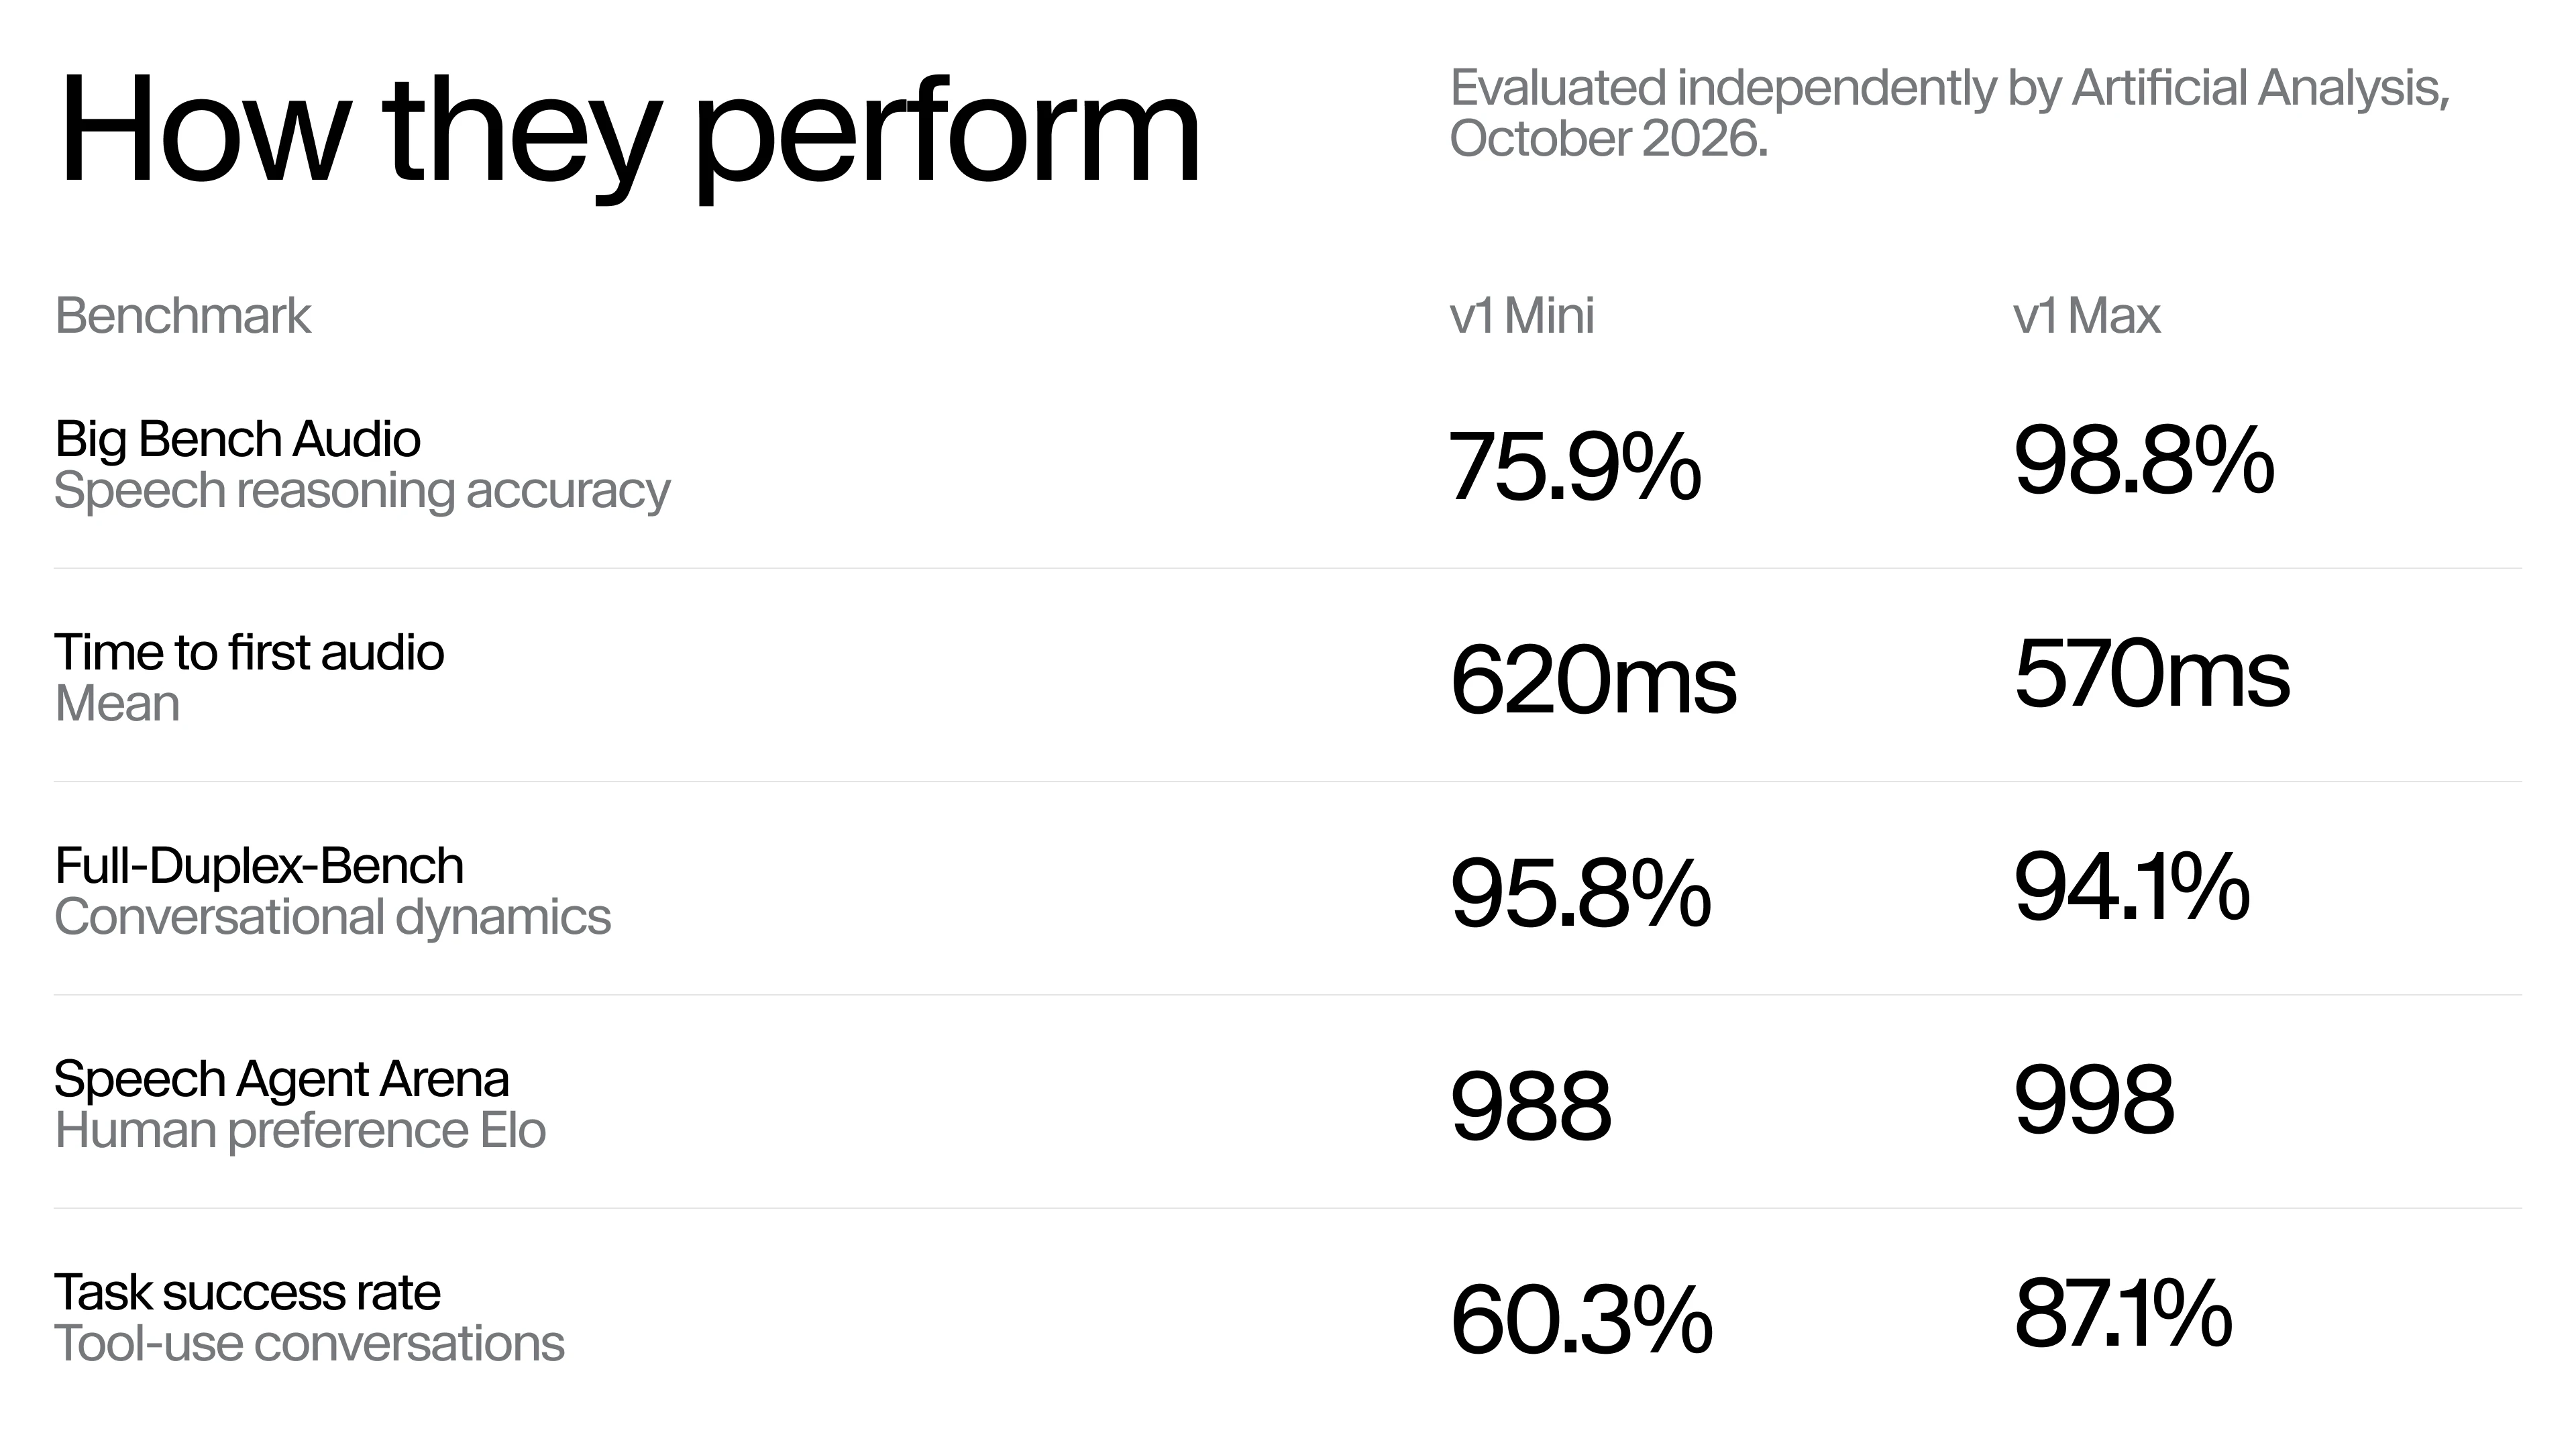
ElevenLabs launches Eleven Realtime v1 Mini and Max speech-to-speech models: Max scores 98.8% on Big Bench Audio, speaks in 0.57s on average, and is OpenAI Realtime API compatible

On Oct 20 ElevenLabs released Eleven Realtime, end-to-end speech-to-speech models where each model is a complete voice agent, removing the need to wire up speech recognition, an LLM and text-to-speech yourself. v1 Mini targets low-cost natural conversation and v1 Max targets support and multi-step tool use. Both cover 90+ languages and 17,000+ voices. Citing independent Artificial Analysis evals, Max answers 98.8% of Big Bench Audio correctly and starts speaking in 0.57s on average. The API is OpenAI Realtime compatible, so migrating means changing the endpoint and model name.

ElevenLabs launches Eleven Realtime v1 Mini and Max speech-to-speech models: Max scores 98.8% on Big Bench Audio, speaks in 0.57s on average, and is OpenAI Realtime API compatible

Key Takeaways

  • Speech reasoning (independent Artificial Analysis eval cited by ElevenLabs): on 1,000 Big Bench Audio questions, v1 Max scores 98.8% and v1 Mini 75.9%
  • Speed (vendor-stated): Max starts speaking in 0.57s on average and Mini in 0.62s; the launch post says "half a second", slightly faster than the blog figures
  • Conversation dynamics and preference: Full-Duplex-Bench Mini 95.8%, Max 94.1%; Speech Agent Arena blind tests Max 998, Mini 988
  • Tool-use task completion: Max 87.1% vs Mini 60.3%, which is why ElevenLabs recommends Max for heavy tool calling
  • 90+ languages and 17,000+ voices; the Realtime API is WebSocket-only at wss://api.elevenlabs.io/v1/convai/realtime and works with the OpenAI SDK; pricing was not in the launch post
Read full story
Linked Models & Agents:
⚡ Eleven Realtime v1 Mini⚡ Eleven Realtime v1 Max🤖 ElevenAgents🌐 ElevenLabs🌐 Artificial Analysis
ADSponsored

Ant Group Open-Sources Ming-3.0-tts: 93.2% Pronunciation Accuracy Leading Global Open Speech Models

In the latest independent Text-to-Speech (TTS) evaluations published by Artificial Analysis, Ant Group's open-source Ming-3.0-tts achieved a 93.2% pronunciation accuracy score, ranking #1 among all 31 evaluated models (outperforming commercial leader ElevenLabs v4 at 91.7%). Offering both a dense 0.5B parameter variant and a 7.9B mixture-of-experts (MoE) model, it delivers voice cloning and preset voices with a Controlled Voice Elo score of 1,069 (#1 among open-weight models), fully released under the permissive MIT license.

Ant Group Open-Sources Ming-3.0-tts: 93.2% Pronunciation Accuracy Leading Global Open Speech Models

Key Takeaways

  • Ant Group open-sourced Ming-3.0-tts, achieving a chart-topping 93.2% pronunciation accuracy on Artificial Analysis speech benchmarks
  • Surpasses commercial leader ElevenLabs v4 (91.7%) and ranks #1 among open-weight models on the Controlled Voice leaderboard (1,069 Elo)
  • Provides both a lightweight 0.5B dense model for edge inference and a 7.9B MoE flagship with zero-shot voice cloning
  • Released under the permissive MIT license for unrestricted commercial deployment, hosted on Hugging Face
Read full story
Linked Models & Agents:

LiveKit Agents 1.8.3: Gemini 3.8 Live NON_BLOCKING default, GPTLive Azure, AssemblyAI Universal, safer tool handoffs

LiveKit published Python [email protected] on GitHub (2026-09-26; PyPI livekit-agents 1.8.3): Gemini 3.8 Live defaults tool_behavior=NON_BLOCKING and sends FunctionTool schemas as parameters_json_schema on the text API; OpenAI gains GPTLiveModel.with_azure and moves the Realtime inference client into agents core; STT adds AssemblyAI universal-3-6-pro plus language_confidence, and configurable ElevenLabs realtime chunk duration; voice fixes prevent parallel tools from canceling handoffs, pair tool outputs by call_id, forward frames as-is in fallback/stream adapters, and fix LiveAvatar interruption/plugin registration. Same-day JS @livekit/[email protected] deepens agent_turn telemetry and adaptive interruption.

LiveKit Agents 1.8.3: Gemini 3.8 Live NON_BLOCKING default, GPTLive Azure, AssemblyAI Universal, safer tool handoffs

Key Takeaways

  • Shipped: [email protected] / PyPI 1.8.3; JS @livekit/[email protected] same day
  • Gemini 3.8 Live: default NON_BLOCKING tool_behavior; FunctionTool via parameters_json_schema on text API
  • OpenAI: GPTLiveModel.with_azure; Realtime inference client moved into agents core
  • STT: AssemblyAI universal-3-6-pro + language_confidence; configurable ElevenLabs realtime chunk duration
  • Voice correctness: parallel tools no longer cancel handoffs; pair tool outputs by call_id; adapters forward frames as-is
Read full story

Pipecat 1.12.0: cross-vendor IPA pronunciation transforms, MOQTransport client reconnect, Classifier/LLMClassifier eval surface

Pipecat v1.12.0 (2026-09-26) adds TTSService.pronunciation_transform_ipa() for reusable word→IPA maps across Cartesia/ElevenLabs/Inworld/Deepgram, client-mode MOQTransport reconnect with session-ending markers, Pipecat Classifiers + LLMClassifier, frame-level interruptible, and response_schema on LLM run_inference. PyPI pipecat-ai 1.12.0 is live.

Pipecat 1.12.0: cross-vendor IPA pronunciation transforms, MOQTransport client reconnect, Classifier/LLMClassifier eval surface

Key Takeaways

  • Shipped: GitHub v1.12.0 = PyPI pipecat-ai 1.12.0; docs docs.pipecat.ai
  • Pronunciation: pronunciation_transform_ipa maps words to IPA once; vendors emit phoneme/SSML/slash IPA—register last in text_transforms
  • Transport: MOQTransport client reconnect within connection_timeout (default 60s); session-ending distinguishes hangup vs outage; relay_url full URL
  • Eval: Classifiers (YesNo/Choice/Score) + LLMClassifier batch questions; allow_continue=false for final-answer judges
  • Inference: run_inference response_schema enforced by OpenAI/Anthropic/Google; frames interruptible by default; UninterruptibleFrame deprecated
Read full story
Linked Models & Agents:

ElevenLabs MCP adds voice, music, image, and video generation across ChatGPT, Claude, Cursor, Grok Bot

ElevenLabs launched a multimodal MCP for voice, transcripts, dubs, music, sound effects, images, and video from assistants you already use. It is live in ChatGPT, Claude, Cursor, Grok Bot, and Hermes from a single install.

Key Takeaways

  • ElevenLabs MCP now generates voice, music, images, and video.
  • Works inside ChatGPT, Claude, Cursor, Grok Bot, and Hermes.
  • Single install covers speech, transcripts, dubs, SFX, and media.
Read full story