AI Coding Live News

Fireworks Forge Launches: Ultra-fast Inference Preview Hits 1,500 Tokens/s, Half-Price Background Mode, Nexus Desktop for Codex and Claude Desktop, Sovereign Private Preview

At its first Forge conference on November 3, open-model inference platform Fireworks launched a batch of products. Ultra-fast, powered by NVIDIA Blackwell, is in public preview at up to 1,500 tokens per second on DeepSeek V4.1 Flash, cutting a 30-turn agent task from 1 minute to 8 seconds. Background Mode runs deferrable work at half price, alongside multi-day prompt caching and higher rate limits. Nexus Desktop brings open-model routing into the Codex app, Claude Desktop and OpenCode, with Pro plans from $8 per month. Fireworks also announced No Eval, serverless LoRA inference, the Fireworks Sovereign private preview and a 60+ partner Frontier Ecosystem.

Fireworks Forge Launches: Ultra-fast Inference Preview Hits 1,500 Tokens/s, Half-Price Background Mode, Nexus Desktop for Codex and Claude Desktop, Sovereign Private Preview

Key Takeaways

  • Ultra-fast public preview: on NVIDIA Blackwell, up to 1,500 tokens per second on DeepSeek V4.1 Flash; in Fireworks' benchmark a 30-turn agent task fell from 1 minute to 8 seconds (Fireworks blog)
  • Cost options: Background Mode runs deferrable work at half price; multi-day prompt caching cuts the cost of resuming long context; higher serverless rate limits and Elastic Burst are generally available
  • Nexus Desktop launches: personalized routing across open and closed models inside the Codex app, Claude Desktop and OpenCode; Pro from $8 per month, Teams from $10 per seat per month
  • Training: No Eval (private preview) turns production traces into task evals; serverless LoRA inference (public preview) starts with GLM 5.3 Flash at per-token pricing with no idle charge; free training on Muse Glimmer 30B through November 30
  • Enterprise: Fireworks Sovereign (private preview) runs the inference engine in a customer's own cloud or data center; Fireworks says it already manages over 25,000 GPUs in customer environments; plus a 60+ partner Frontier Ecosystem
Read full story

OpenAI API adds 12-hour prompt caching: GPT-5.6+ models can keep shared context cached for half a day, with writes at 2.5x input and reads still at 0.1x

On Oct 20 OpenAI added 12-hour prompt caching to the Responses API: GPT-5.6 and later models can set prompt_cache_options.ttl to "12h" so instructions, tool definitions and reference material stay billed at the cached rate even when requests are hours apart. 12-hour writes cost 2.5x the ordinary input price versus 1.25x for the default 30 minutes; read rates are unchanged at 0.1x on most models and 0.05x on GPT-6.1 Sol. One request can mix 12-hour and 30-minute breakpoints.

Key Takeaways

  • New option: prompt_cache_options.ttl in the Responses API accepts "30m" (default) or "12h", and prompt_cache_breakpoint.ttl overrides it per breakpoint, for GPT-5.6 and later models
  • Rates (vendor-stated): 30-minute writes at 1.25x and 12-hour writes at 2.5x ordinary input; reads at 0.1x on most models and 0.05x on GPT-6.1 Sol, same for both lifetimes
  • Our estimate from the documented rates: reusing one prefix 6 times an hour apart costs about 6x1.25=7.5x input with 30-minute caching (rewritten each time) versus about 2.5+5x0.1=3.0x with 12-hour caching
  • Up to 4 cache writes per request and a 1,024 visible-token minimum prefix; usage now splits writes into ttl_30m_tokens and ttl_12h_tokens
  • "12h" is a minimum lifetime, not a deletion deadline, and does not guarantee a hit or lower latency; GPT-5.5 and earlier keep using prompt_cache_retention
Read full story
Linked Models & Agents:

OpenAI improves GPT-6 prompt caching: higher default hit rates, up to 90% off cached input

OpenAI Developers (@OpenAIDevs) announced prompt-caching improvements for the GPT-6 API: higher default cache-hit rates so more input tokens get cached-input discounts of up to 90%, helping agents run faster and cheaper. OpenAI docs also point developers to the Prompt Caching Dashboard and miss Diagnostics.

OpenAI improves GPT-6 prompt caching: higher default hit rates, up to 90% off cached input

Key Takeaways

  • GPT-6 API prompt caching now hits more often by default for agent workloads.
  • Cached input tokens discounted up to about 90%.
  • Dashboard monitors hit rates; Diagnostics help fix cache misses.
Read full story

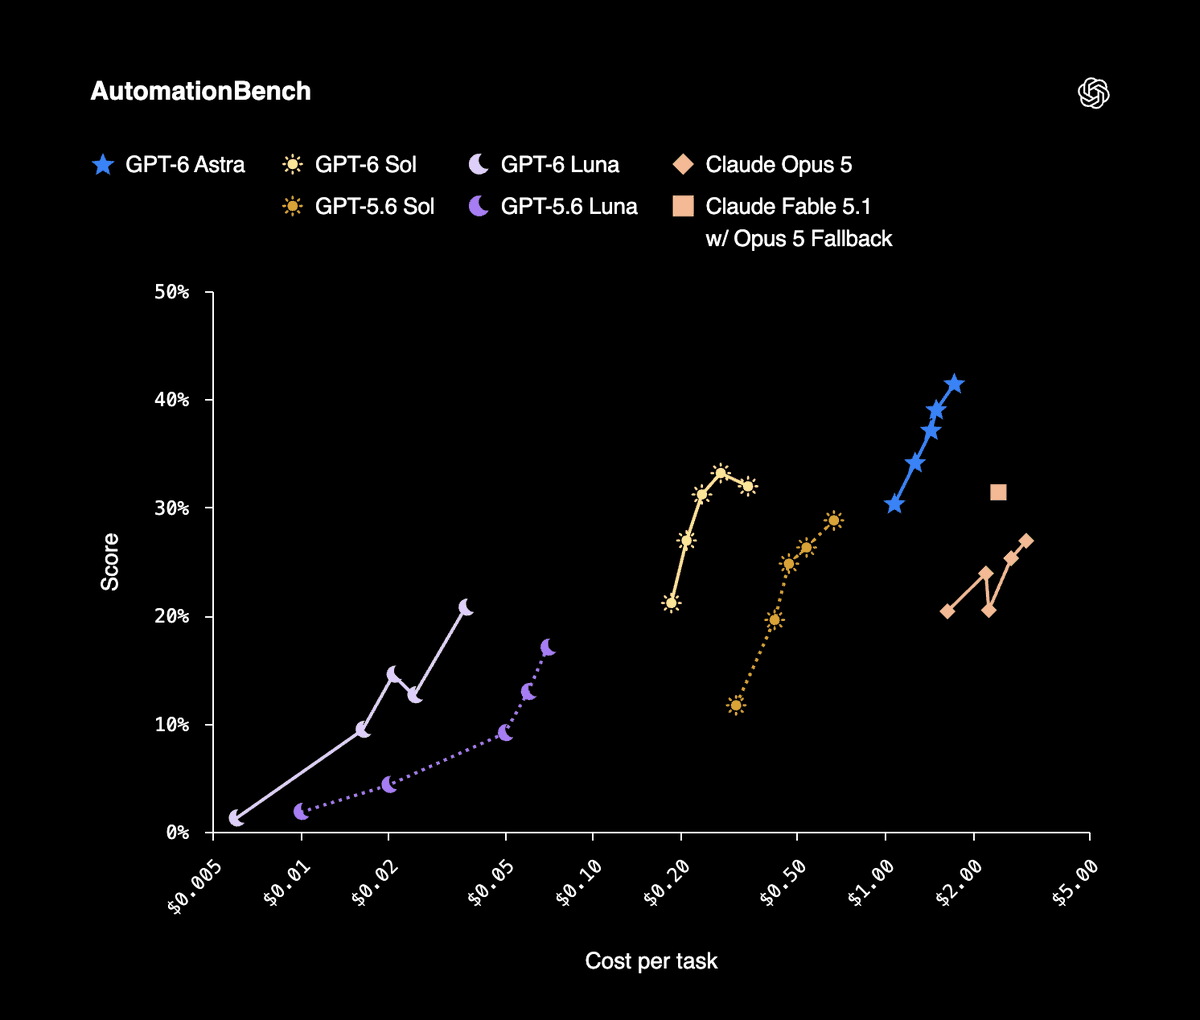
OpenAI launches GPT-6 Sol & Luna: dual enterprise workhorses cut API pricing by 50% down to $0.10/M

OpenAI introduced GPT-6 Sol and GPT-6 Luna, faster and more affordable models that carry forward much of GPT-6 Astra’s strength for work at scale. Caching and inference efficiency cuts yield 50% lower API prices versus GPT-5.6 promotional pricing: Sol is priced at $2/$10 per million tokens for deep reasoning, while high-volume Luna costs just $0.10/$0.50 per million tokens with a 90% prompt caching discount.

OpenAI launches GPT-6 Sol & Luna: dual enterprise workhorses cut API pricing by 50% down to $0.10/M

Key Takeaways

  • Tiered dual-model architecture: Sol for deep reasoning and complex coding agents, Luna for ultra-high-throughput workflows.
  • 50% price slash: Sol at $2/$10 per million tokens; Luna down to $0.10/$0.50 with 90% prompt caching discount.
  • Available immediately in OpenAI API (gpt-6-sol, gpt-6-luna), ChatGPT Work, and Codex.
Read full story
Linked Models & Agents:
ADSponsored

Moonshot: Kimi K3 now on Amazon Bedrock with coding/agent workflows and explicit prompt caching

@Kimi_Moonshot announced Kimi K3 is now on Amazon Bedrock for coding, document analysis, and extended agent workflows, with Bedrock access, encryption, and auditing controls, plus explicit prompt caching. AWS published a Bedrock model card so teams can call K3 inside the AWS stack.

Moonshot: Kimi K3 now on Amazon Bedrock with coding/agent workflows and explicit prompt caching

Key Takeaways

  • Kimi K3 is live on Amazon Bedrock.
  • Targets coding, document analysis, and extended agent workflows with Bedrock access/encryption/auditing.
  • Explicit prompt caching supported; start via the AWS Bedrock model card.
Read full story

Mid-task Jev in Codex raises/lowers GPT-6 Astra reasoning effort; author reports ~50% Astra cost cut without breaking prompt cache

@miu21590 demoed using Jev inside a running Codex session to raise/lower GPT-6 Astra reasoning effort—more thinking when stuck, less on routine steps—reporting ~50% lower Astra costs and faster runs without breaking prompt caching. Versus the usual pre-task Jev model pick, this wires the decision model mid-run for cost control.

Mid-task Jev in Codex raises/lowers GPT-6 Astra reasoning effort; author reports ~50% Astra cost cut without breaking prompt cache

Key Takeaways

  • Call Jev mid-Codex-run to raise/lower GPT-6 Astra reasoning effort.
  • Author tests: ~50% lower Astra cost, faster, prompt cache intact.
  • Moves Jev from pre-task model pick to in-task cost control.
Read full story
Linked Models & Agents:

Google AI Studio Unveils Managed Agents Architecture with Antigravity Preview Model

Google AI Studio introduced its Managed Agents architecture powered by the antigravity-preview-09-2026 model. The update features optimized prompt caching for software repositories and high-throughput File APIs for frictionless multi-turn agent interaction.

Key Takeaways

  • Deploys Managed Agents architecture with specialized antigravity-preview model
  • Repo-level prompt caching slashes repetitive codebase context costs by 80%
  • High-throughput File API allows seamless mounting of large multi-file projects
Read full story
Linked Models & Agents:
⚡ Antigravity Preview 09.2026🤖 Managed Agents🌐 Google

Bench v2.1.0: constitution + three-stage edit review for Claude Code, installer/CLI, 1036 tests

Dana (@MatureIntellect) shipped Bench v2.1.0: Claude Code runs under a written constitution with three-stage edit review and a tamper-evident ledger. v2.1 adds prompt caching, per-stage model control, installer/CLI, concurrency locks, weekly cost/latency reports, and 1,036 passing tests.

Key Takeaways

  • Release: Bench v2.1.0 (benchgov.com).
  • Governance: constitution + three-stage edit review + tamper-evident ledger.
  • Eng: installer/CLI, prompt caching, concurrency locks, 1036 tests, cost/latency reports.
Read full story
Linked Models & Agents:

DeepSeek unveils API Prompt Caching rates dropping cached input pricing to ¥0.1 per 1M tokens

DeepSeek introduced automatic API Prompt Caching across its developer platform. When re-sending system prompts, large repository contexts, or multi-turn chat history, cached input tokens are billed at just ¥0.1 per million tokens (~$0.014/M), reducing operating expenses for autonomous coding agents by up to 85%.

Key Takeaways

  • Cached input tokens cost only ¥0.1 (~$0.014) per million tokens with automated 64k prefix reuse.
  • Zero manual cache key configuration: gateway automatically handles prefix hash caching.
  • Dramatically lowers API costs for terminal agents (Aider, Cline, OpenHands) loading full repos.
Read full story

Anthropic upgrades Prompt Caching TTL auto-extension, reducing compute cost for multi-turn agent sessions by 40%

Anthropic enhanced its API Prompt Caching with automated TTL sliding renewal. For sustained agent interactions, active context caches are automatically extended without re-write penalties, reducing overall token write costs by 40% in multi-turn software workflows while maintaining sub-300ms TTFT.

Key Takeaways

  • Active context caches automatically slide TTL window, avoiding recurring cache write surcharges.
  • Reduces multi-turn developer session token expenses by an average of 40%.
  • Maintains sub-300ms time-to-first-token (TTFT) during dense MCP tool calls.
Read full story
ADSponsored