AI Coding Live News

Boson AI Unveils Higgs Realtime Duplex: A 45B MoE Full-Duplex Omni Model That Listens, Watches, Talks, and Calls Tools in the Background; API Waitlist Open

On 2026-11-05 Boson AI (the team of Mu Li and Alex Smola) released a research preview of Higgs Realtime Duplex: a 45B MoE front model that slices voice, video, and tool results into 160 ms chunks so it can listen, watch, speak, and render its own face at once, while thinking, calling tools, or delegating hard questions to a larger backend model without pausing. Vendor-reported scores include Big Bench Audio 98.9, tau-Voice 69.8, and Full-Duplex-Bench v1.5 75.5. The API is waitlist-only for now; the earlier Higgs Realtime is available today.
Boson AI Unveils Higgs Realtime Duplex: A 45B MoE Full-Duplex Omni Model That Listens, Watches, Talks, and Calls Tools in the Background; API Waitlist Open

Key Takeaways

  • Shape: a 45B MoE front model, further trained on about 2T tokens of text, audio, and video; every stream is cut into 160 ms chunks, silence included
  • Background work: it thinks and calls tools asynchronously while talking, and delegates hard tasks with full context to a larger backend model (a frontier model is recommended)
  • Vendor-reported scores: Big Bench Audio 98.9 (top of the table), IFEval 94.1, tau-Voice 69.8 (GPT-Live-1 about 74.5), Full-Duplex-Bench v1.5 75.5 (GPT-Live-1 80.1, TML 77.8)
  • Cost design: audio and video use about 2.6K tokens per minute, about 2.6K-5K with thinking and tools; the target is an hour of talk costing at most one-tenth of an hour of human time
  • Availability: the Duplex API is waitlist-only; voice and face swap zero-shot from a reference clip or a single image
Read full story
Linked Models & Agents:
⚡ Higgs Realtime Duplex⚡ Higgs Realtime⚡ GPT-Live-1⚡ TML Interaction Small🌐 Boson AI

Cursor Ships Voice Chat: Realtime Two-Way Calls with Agents on Agents Window, IDE, Web, and iOS via Grok Voice

On 2026-11-06, Cursor's changelog shipped Voice Chat with Agents: realtime two-way voice calls with coding agents in the Agents Window, IDE, web, and iOS. Dictation remains a separate feature. Grok Voice handles listening and speaking (voices include Ara, Eve, Leo, Rex, Sal); the coding agent still uses the model you picked. With Privacy Mode on, voice chat runs with zero data retention. A signed-in Cursor account is required (API-key-only sessions cannot start a call).

Cursor Ships Voice Chat: Realtime Two-Way Calls with Agents on Agents Window, IDE, Web, and iOS via Grok Voice

Key Takeaways

  • Source: Cursor changelog Voice Chat with Agents (2026-11-06) + docs at cursor.com/docs/agent/voice-chat
  • UX: start when the agent is idle and the chat input is empty via the waveform button; during a call hand off coding, read-only check diffs/runs/history, switch Project workers
  • Split: Grok Voice listens and speaks; the coding agent keeps your chosen model and speaks short progress/done notes
  • Privacy/limits: Privacy Mode = zero data retention for voice; signed-in account required; API-key-only sessions cannot call; ~10 min silence hangup by default plus a daily call limit
  • Not dictation: Cmd+Shift+Space still toggles dictation (formerly Voice Mode); Voice Chat is two-way speech with no dedicated shortcut
Read full story
Linked Models & Agents:

Meta Rolls Out Muse Realtime Avatar in the US Muse App: Speech-Driven Expression and Gesture at ~870ms First-Byte Latency

On November 5 Meta AI (@AIatMeta) said Muse Realtime Avatar, previewed at Connect, is rolling out in the US Muse app, turning Muse Realtime Voice into interactive live avatars. The research blog describes an audio-driven Diffusion Transformer that shares the speech-token stream with voice for lip-sync and expression; a single GB200 session streams 448×768 at 25 fps with about 870 ms from end of user turn to first synchronized audio-video byte, with Meta Video Seal invisible watermarking. Muse is for users 18+; no global schedule or developer API was announced.

Meta Rolls Out Muse Realtime Avatar in the US Muse App: Speech-Driven Expression and Gesture at ~870ms First-Byte Latency

Key Takeaways

  • US Muse app rollout of Realtime Avatar after the Connect preview (@AIatMeta)
  • Shared speech VQ tokens drive audio decode and avatar video; causal chunks with self-forcing distillation cut ~120 teacher NFEs to 2 student NFEs (~60x)
  • Vendor perf: 448×768@25fps, ~870ms first-byte latency; ~8x serving capacity vs BF16 baseline, up to 12 concurrent sessions on one GB200
  • Vendor preference study favored Muse over Runway Characters and HeyGen LiveAvatar on overall and most axes
  • Safety: Video Seal invisible watermark; blog demos are not the full in-app avatar set; no public developer API stated
Read full story
Linked Models & Agents:
⚡ Muse Spark⚡ Muse Presence🤖 Muse🌐 Meta

OpenAI Realtime Lead: GPT-Live Outbound Telephony API Hits GA via Any SIP Trunk, with HD Voice and DTMF

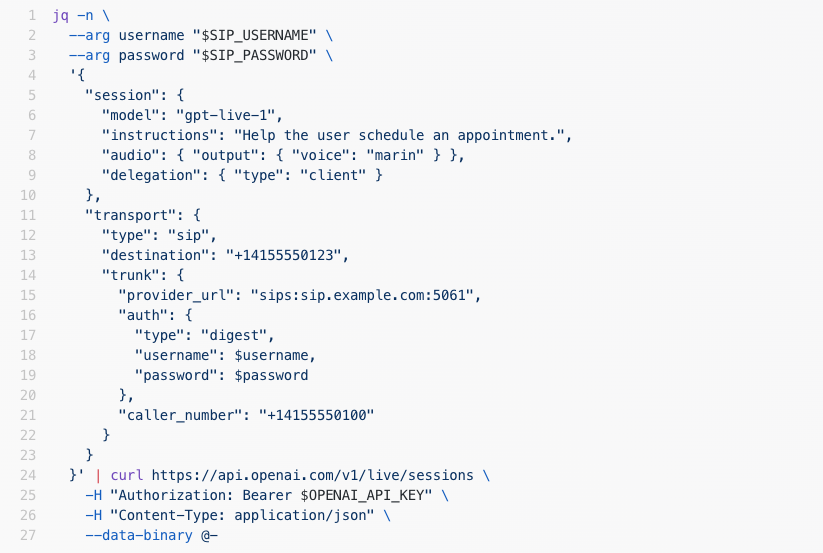
On November 4, Justin Uberti, Head of Realtime AI at OpenAI, said the GPT-Live outbound telephony API is generally available: Live voice agents can dial through any SIP trunk such as Telnyx or Twilio, with HD Voice and bidirectional DTMF. Official docs describe Live API + SIP transport; Greg Brockman amplified the note.

OpenAI Realtime Lead: GPT-Live Outbound Telephony API Hits GA via Any SIP Trunk, with HD Voice and DTMF

Key Takeaways

  • Justin Uberti (Head of Realtime AI, OpenAI): GPT-Live outbound telephony API is GA via any SIP trunk
  • Official docs: Live API POST /v1/live/sessions with transport.type=sip; HD Voice and bidirectional DTMF
  • Trunks need TLS (sips:) signaling and SDES-SRTP; examples cite Telnyx and Twilio
  • Documented limits: ~3 minutes ringing and ~2 hours connected call duration
  • Amplified by Greg Brockman; frame as a first-hand employee note, not an @OpenAI press post
Read full story
Linked Models & Agents:
⚡ OpenAI GPT Live 1🌐 OpenAI
ADSponsored

Mistral Releases Voxtral 3 Audio Model Suite and Real-Time Voice-Agent API with Sub-500ms Latency

Mistral AI unveiled Voxtral 3, a production audio intelligence suite paired with a real-time Voice-Agent API. The lineup features the 4B-parameter Mini Transcribe, Small Transcribe 3, and a turn-key voice agent SDK built on LiveKit. Supporting transcription across 50 languages with diarization, multi-lingual TTS with emotional tags across 35+ languages, and 30-minute voice cloning, Voxtral 3 redefines voice AI economics. In Artificial Analysis independent benchmarks, Small Transcribe 3 secured rank #3 globally with a 2.1% error index (outperforming ElevenLabs Scribe v2), while Realtime Transcribe delivers sub-500ms latency at $0.04/min for full voice agent turns.

Mistral Releases Voxtral 3 Audio Model Suite and Real-Time Voice-Agent API with Sub-500ms Latency

Key Takeaways

  • Mistral AI launched the Voxtral 3 suite spanning transcription, emotional TTS, studio-grade voice cloning, and a LiveKit-powered Voice-Agent SDK
  • Artificial Analysis independently verified Small Transcribe 3 at a 2.1% error index, outperforming ElevenLabs Scribe v2 (2.2%) and Grok Voice 2.0 (2.3%)
  • Realtime Transcribe 3 achieves sub-500ms latency, delivering sub-second full conversational voice-agent turns
  • Aggressive pricing: Mini Transcribe starts at $0.0035/min, and managed voice agent sessions cost just $0.04/min paired with Mistral Small 4
Read full story

ElevenLabs launches Eleven Realtime v1 Mini and Max speech-to-speech models: Max scores 98.8% on Big Bench Audio, speaks in 0.57s on average, and is OpenAI Realtime API compatible

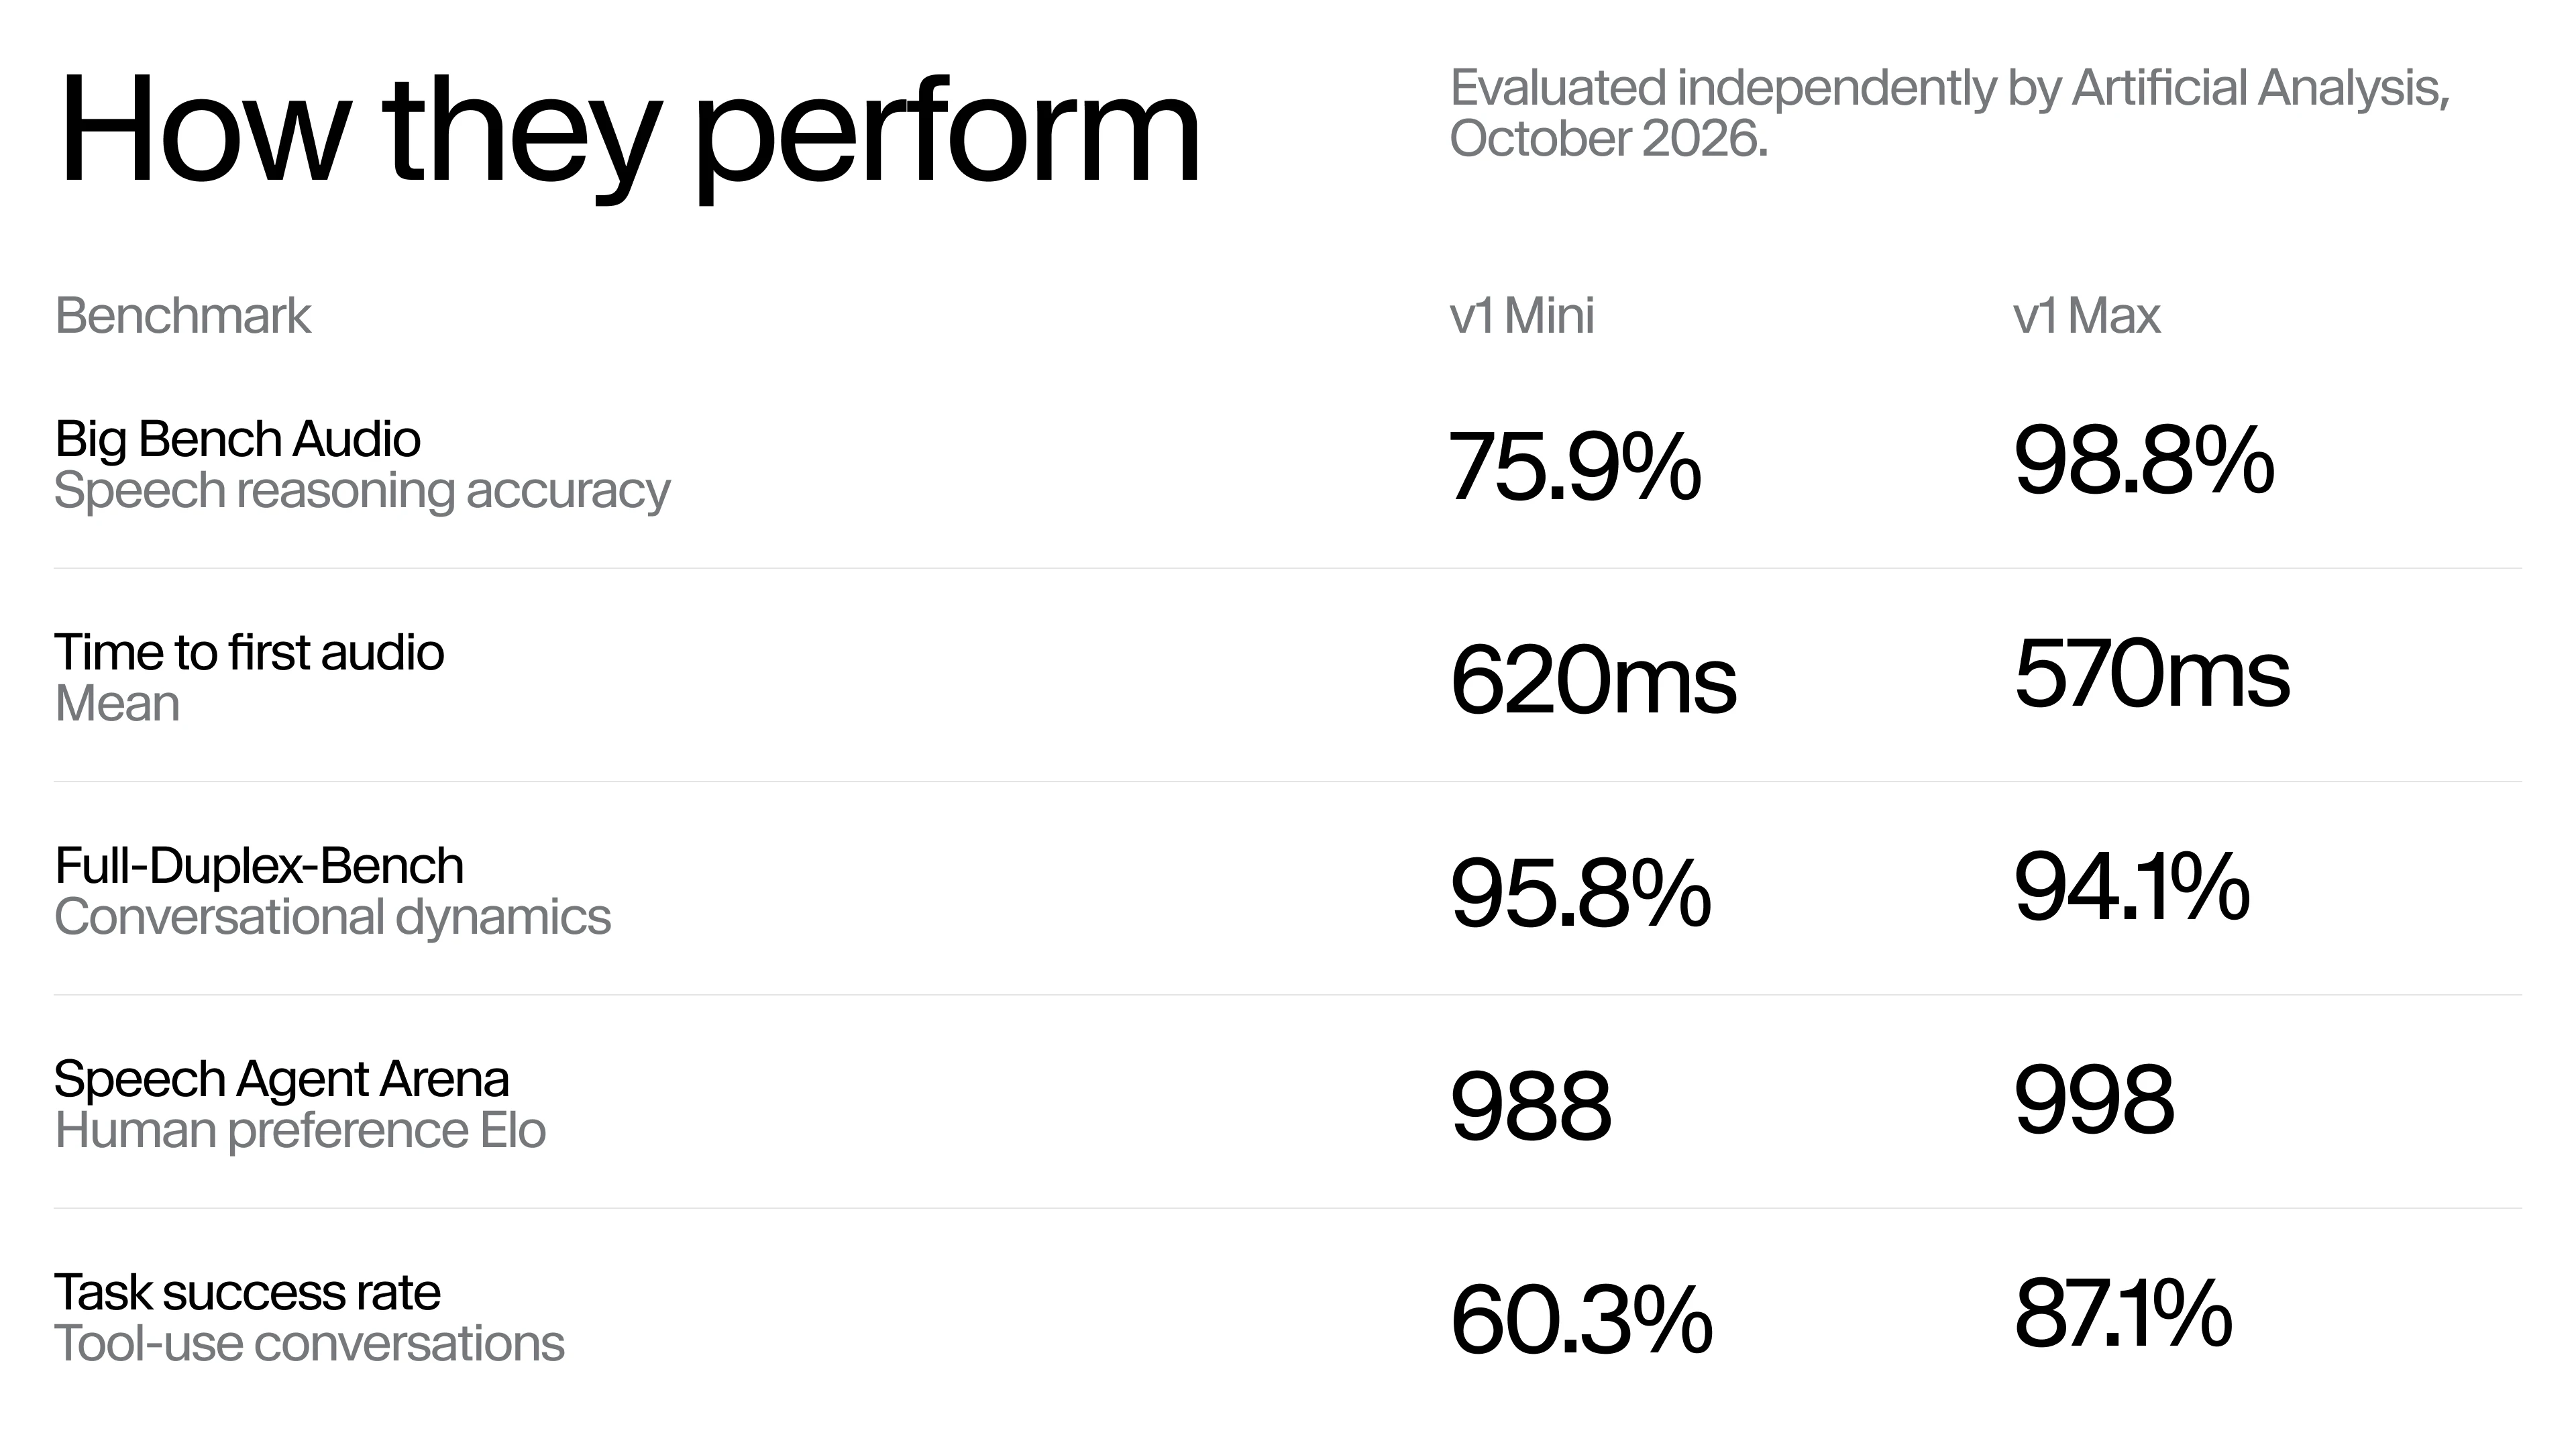
On Oct 20 ElevenLabs released Eleven Realtime, end-to-end speech-to-speech models where each model is a complete voice agent, removing the need to wire up speech recognition, an LLM and text-to-speech yourself. v1 Mini targets low-cost natural conversation and v1 Max targets support and multi-step tool use. Both cover 90+ languages and 17,000+ voices. Citing independent Artificial Analysis evals, Max answers 98.8% of Big Bench Audio correctly and starts speaking in 0.57s on average. The API is OpenAI Realtime compatible, so migrating means changing the endpoint and model name.

ElevenLabs launches Eleven Realtime v1 Mini and Max speech-to-speech models: Max scores 98.8% on Big Bench Audio, speaks in 0.57s on average, and is OpenAI Realtime API compatible

Key Takeaways

  • Speech reasoning (independent Artificial Analysis eval cited by ElevenLabs): on 1,000 Big Bench Audio questions, v1 Max scores 98.8% and v1 Mini 75.9%
  • Speed (vendor-stated): Max starts speaking in 0.57s on average and Mini in 0.62s; the launch post says "half a second", slightly faster than the blog figures
  • Conversation dynamics and preference: Full-Duplex-Bench Mini 95.8%, Max 94.1%; Speech Agent Arena blind tests Max 998, Mini 988
  • Tool-use task completion: Max 87.1% vs Mini 60.3%, which is why ElevenLabs recommends Max for heavy tool calling
  • 90+ languages and 17,000+ voices; the Realtime API is WebSocket-only at wss://api.elevenlabs.io/v1/convai/realtime and works with the OpenAI SDK; pricing was not in the launch post
Read full story
Linked Models & Agents:
⚡ Eleven Realtime v1 Mini⚡ Eleven Realtime v1 Max🤖 ElevenAgents🌐 ElevenLabs🌐 Artificial Analysis

Mistral launches the Voxtral 3 speech model family and a voice agent SDK: transcription in 50+ languages, TTS at $13 per 1M characters, EU-hosted or self-deployed

On Oct 20 Mistral released Voxtral 3: the Voxtral Small/Mini Transcribe 3 speech-to-text models, Voxtral Mini Transcribe Realtime 3, the Voxtral Mini TTS 3 (Voxtral Speech 3) text-to-speech model, and a LiveKit-based voice agent SDK that streams listening, reasoning with tool calls, and speaking as one pipeline, with each turn completing in under a second per Mistral. Transcription covers 50+ languages with diarization and context biasing; TTS covers 35+ languages and 50+ dialects, plus Pro Voice cloning from 30 minutes of audio. It is live on the Mistral API (EU, US and global endpoints) and can be self-deployed.

Mistral launches the Voxtral 3 speech model family and a voice agent SDK: transcription in 50+ languages, TTS at $13 per 1M characters, EU-hosted or self-deployed

Key Takeaways

  • Multilingual transcription (vendor-reported): macro WER over 45 FLEURS languages is 4.1% (language forced) / 4.0% (inferred) for Voxtral Small Transcribe 3, tied with Microsoft AI Transcribe 2 and ahead of Scribe v2 (4.9%) and Whisper large-v3 (16.0%/14.9%)
  • Diarization (vendor-reported): cpWER of 18.4% for Small and 18.6% for Mini, vs 30.9% for the previous Voxtral Mini Transcribe 2 and 38.4% for Gemini 3.5 Transcribe
  • Pricing: Voxtral Mini Transcribe 3 is 4B parameters at $0.0035/min (docs list it as Public Preview with 32k context); Voxtral Speech 3 costs $13 per 1M characters
  • Realtime: Voxtral Mini Transcribe Realtime 3 runs below 500 ms latency; in Mistral's 35-language FLEURS chart the 480 ms setting scores 6.4% WER, still behind Gemini 3.5 Realtime Transcribe at 4.2%
  • The voice agent SDK is built on LiveKit with SIP telephony and WebRTC; each stage (LLM, voice, language) is swappable, and Pro Voice clones a voice from 30 minutes of audio
Read full story
Linked Models & Agents:
⚡ Voxtral Small Transcribe 3⚡ Voxtral Mini Transcribe 3⚡ Voxtral Mini Transcribe Realtime 3⚡ Voxtral Mini TTS 3🤖 Voxtral voice agent SDK🌐 Mistral AI🌐 LiveKit

OpenAI Node 7.25.0: Computer Use on beta.agents; 7.24 adds GPT-6.1 Sol + Agents credential/session options

Official TypeScript SDK [email protected] (v7.25.0, 2026-09-29) adds Computer Use to beta.agents (#2837), mirroring Python 3.22.0. Prior v7.24.0 shipped Agents credential/session options (#2812), the gpt-6.1-sol model id (#2836), Responses Cyber access, Realtime Translation client secrets, and a dedicated Node translation WebSocket. 35 commits ahead of v7.23.0.

OpenAI Node 7.25.0: Computer Use on beta.agents; 7.24 adds GPT-6.1 Sol + Agents credential/session options

Key Takeaways

  • Releases v7.24.0 → v7.25.0; npm [email protected]; 35 commits ahead of v7.23.0
  • Computer Use on beta.agents via #2837
  • gpt-6.1-sol id (#2836); Agents credential/session options (#2812)
  • Realtime Translation client secret (#2819) + Node translation WebSocket (#2818)
  • Upgrade: npm i [email protected]; docs: platform.openai.com agents + API reference
Read full story

OpenAI Python SDK 3.20.0: Agents credential/session options, Cyber access programs on Responses, opt-in WebSocket text/tool snapshots

OpenAI shipped Python SDK v3.20.0 on 2026-09-28: Agents credentials gain metadata and update-without-replace auth, sessions add ultrafast tier plus misalignment_policy_violation; Responses can select Cyber access programs (standard/daybreak_blue/daybreak_red); and an opt-in ResponsesWebSocketAccumulator yields immutable incremental text/tool snapshots. Live/Realtime WebSocket query/queue/TLS retry fixes land in the same cut.

OpenAI Python SDK 3.20.0: Agents credential/session options, Cyber access programs on Responses, opt-in WebSocket text/tool snapshots

Key Takeaways

  • Shipped v3.20.0 — Agents credential metadata/session ultrafast + Cyber access programs
  • Opt-in ResponsesWebSocketAccumulator for incremental text/tool snapshots (190+ WS tests)
  • Live/Realtime WebSocket query/queue/TLS retry hardening
  • Upgrade: pip install -U openai
Read full story

LiveKit Agents 1.8.3: Gemini 3.8 Live NON_BLOCKING default, GPTLive Azure, AssemblyAI Universal, safer tool handoffs

LiveKit published Python [email protected] on GitHub (2026-09-26; PyPI livekit-agents 1.8.3): Gemini 3.8 Live defaults tool_behavior=NON_BLOCKING and sends FunctionTool schemas as parameters_json_schema on the text API; OpenAI gains GPTLiveModel.with_azure and moves the Realtime inference client into agents core; STT adds AssemblyAI universal-3-6-pro plus language_confidence, and configurable ElevenLabs realtime chunk duration; voice fixes prevent parallel tools from canceling handoffs, pair tool outputs by call_id, forward frames as-is in fallback/stream adapters, and fix LiveAvatar interruption/plugin registration. Same-day JS @livekit/[email protected] deepens agent_turn telemetry and adaptive interruption.

LiveKit Agents 1.8.3: Gemini 3.8 Live NON_BLOCKING default, GPTLive Azure, AssemblyAI Universal, safer tool handoffs

Key Takeaways

  • Shipped: [email protected] / PyPI 1.8.3; JS @livekit/[email protected] same day
  • Gemini 3.8 Live: default NON_BLOCKING tool_behavior; FunctionTool via parameters_json_schema on text API
  • OpenAI: GPTLiveModel.with_azure; Realtime inference client moved into agents core
  • STT: AssemblyAI universal-3-6-pro + language_confidence; configurable ElevenLabs realtime chunk duration
  • Voice correctness: parallel tools no longer cancel handoffs; pair tool outputs by call_id; adapters forward frames as-is
Read full story
ADSponsored

CopilotKit 1.74.0: consume learned skills across SDK containers; Web Inspector targeted What's New + HUD telemetry

CopilotKit shipped v1.74.0 on 2026-09-25 (npm @copilotkit/react-core 1.74.0): SDKs can consume learned skills from multiple containers, expanding skill assets beyond a single runtime; Web Inspector gains targeted What's New notifications and launcher HUD impression/action tracking. Fixes: threads drawer no longer locks on unresolved entitlements, stop refreshing realtime credentials for sockets that never open, stop per-message state cloning / virtual-scroll tug-of-war in React, and a Memory policy that grants nothing no longer fails the run.

CopilotKit 1.74.0: consume learned skills across SDK containers; Web Inspector targeted What's New + HUD telemetry

Key Takeaways

  • Shipped: v1.74.0 / @copilotkit/[email protected]
  • Skills: consume learned skills from multiple containers across SDKs (#7384)
  • Inspector: targeted What's New (#6956) + launcher HUD impression/action tracking (#7376)
  • Stability: no realtime credential refresh for never-open sockets; empty-grant Memory policy no longer fails runs
  • React: stop per-message state cloning and virtual-scroll tug-of-war on long threads
Read full story
Linked Models & Agents:

Pydantic AI 2.51.0: OpenAILiveModel for GPT-Live, context_window_used on realtime, tighter Gemini Live connect checks

Pydantic AI v2.51.0 (2026-09-25) adds OpenAILiveModel for OpenAI GPT-Live, exposes context_window_used on realtime sessions, tightens Gemini Live id/affective-dialog checks, and raises UserError for forced realtime tool_choice on OpenAI/Azure/xAI. PyPI pydantic-ai 2.51.0 is live.

Pydantic AI 2.51.0: OpenAILiveModel for GPT-Live, context_window_used on realtime, tighter Gemini Live connect checks

Key Takeaways

  • Shipped: GitHub v2.51.0 = PyPI pydantic-ai 2.51.0; docs pydantic.dev/docs/ai
  • Realtime: OpenAILiveModel for GPT-Live; context_window_used on sessions from GPT-Live ratio or response usage
  • Compat: match dated gemini-3.8-live ids; reject google_affective_dialog at connect; RealtimeError on Gemini Live close codes
  • Safety: UserError for forced realtime tool_choice on OpenAI/Azure OpenAI/xAI
  • Perf: cache agent graph across Agent.run(); skip task group for single-child fan-out
Read full story
Linked Models & Agents:

Pydantic AI 2.50.0: DecisionModel protocol, named route selection, Gemini 3.8 Live realtime

Pydantic AI 2.50.0 (2026-09-25) adds DecisionModel (TypeSafeModel implements it), named route questions with optional decision_route_threshold, Gemini 3.8 Live realtime, durable-context hooks, and audio_seconds usage pricing.

Pydantic AI 2.50.0: DecisionModel protocol, named route selection, Gemini 3.8 Live realtime

Key Takeaways

  • DecisionModel base + TypeSafeModel implementer; ask routes by name (#8696, #8733)
  • Opt-in decision_route_threshold replaces tool-call lean; ModelSelectionContext.prompt (#8737/#8739)
  • Gemini 3.8 Live realtime + RequestUsage.audio_seconds (#8393/#8427)
  • decide spans + RunContext.in_durable_context (#8698/#8723)
  • Upgrade: pip install -U 'pydantic-ai==2.50.0'
Read full story
Linked Models & Agents:

Pydantic AI 2.49.0: GitHub Copilot OAuth device flow, BoolCriteria, GPT-6 on Bedrock

Pydantic AI shipped v2.49.0 on 2026-09-24 (PyPI aligned). Highlights: GitHubCopilotOAuthFlow device auth, BoolCriteria for typed yes/no fields, RealtimeSession.wait_for_reply(), plus Bedrock Converse fixes for gpt-6-sol/gpt-6-luna/gpt-6-astra and dropping unsupported temperature/top_p on GPT-5.6/GPT-6.

Pydantic AI 2.49.0: GitHub Copilot OAuth device flow, BoolCriteria, GPT-6 on Bedrock

Key Takeaways

  • Upgrade: pip install -U 'pydantic-ai==2.49.0' (PyPI)
  • GitHubCopilotOAuthFlow device authorization (#8618)
  • BoolCriteria clarifies bool/Enum yes-no semantics (#8586)
  • RealtimeSession.wait_for_reply() (#8514)
  • Bedrock: allow gpt-6-sol/luna/astra; strip temperature/top_p for GPT-5.6/GPT-6 (#8656/#8668)
Read full story

xAI ships Grok Voice Transcribe 2.0: ~2× accuracy, $0.10/hr batch, AA streaming #1

SpaceXAI (xAI) launched Grok Voice Transcribe 2.0, claiming roughly 2× the accuracy of Transcribe 1.0 on customer-support calls, spoken credentials, and short voice commands at the same price. It ranks #1 for accuracy among 32 streaming transcription models on Artificial Analysis; short-phrase WER fell from about 20.6% to 6.8%. Features include streaming and batch modes, automatic language detection with mid-recording language switches, word-level timestamps and confidence, free speaker diarization, batch at about $0.10/hour and realtime streaming at about $0.20/hour, with existing Speech-to-Text API clients upgraded without code changes.

Key Takeaways

  • Claims ~2× accuracy vs Transcribe 1.0 on support calls, spoken credentials, and short commands at the same price.
  • #1 accuracy among 32 AA streaming transcription models; short-phrase WER ~20.6%→6.8%.
  • Batch ~$0.10/hr and streaming ~$0.20/hr, with diarization, language switching, word timestamps; existing API clients upgrade in place.
Read full story
Linked Models & Agents:
⚡ Grok Voice Transcribe 2🌐 xAI