AI Coding Live News

x
xAIdocs.x.ai·
👀53
🔥82

xAI will add an invisible watermark to Grok API text by default from Nov 7, covering grok-4.7 and six other models, with per-model admin opt-out

On Oct 31, xAI (signed as SpaceXSI in its docs) added an "Output Watermarking" page to its API docs: starting November 7, 2026, text generated by grok-4.7, grok-4.6, grok-4.5, grok-4.3, and the reasoning, non-reasoning, and multi-agent versions of grok-4.20 will carry an invisible watermark by default, to comply with the EU AI Act. It covers ordinary text, structured outputs, and tool call arguments on both the Responses and Chat Completions APIs, and works by slightly shaping token choice without adding any characters. Developers can read the x-watermark response header to check; team admins can opt out per model in the Console, but must confirm a legal exception applies, and some models may be locked on.

Key Takeaways

  • Timing: on by default from November 7, 2026, with no code change and no request parameter (xAI docs)
  • Scope: 7 model IDs (grok-4.7, 4.6, 4.5, 4.3, and grok-4.20 reasoning, non-reasoning, and multi-agent) on the global and regional endpoints, across both Responses and Chat Completions
  • Coverage: ordinary text, structured outputs, and tool call arguments; the response header x-watermark: true marks a watermarked output
  • Opt-out: team admins switch it off per model, effective for new requests within 5 minutes and logged in the audit log; admins must confirm a legal exception applies, and some models are locked on
  • xAI's position: no effect on quality or speed; detection is statistical with three outcomes (watermarked, not watermarked, uncertain), and the detection API is by application
Read full story

DeepSeek open-sources DeepInfer, the inference framework behind its V4.1-Flash production service, with speculative decoding, batch-invariant inference and structured outputs, plus the deepseek-recipe API encoding library

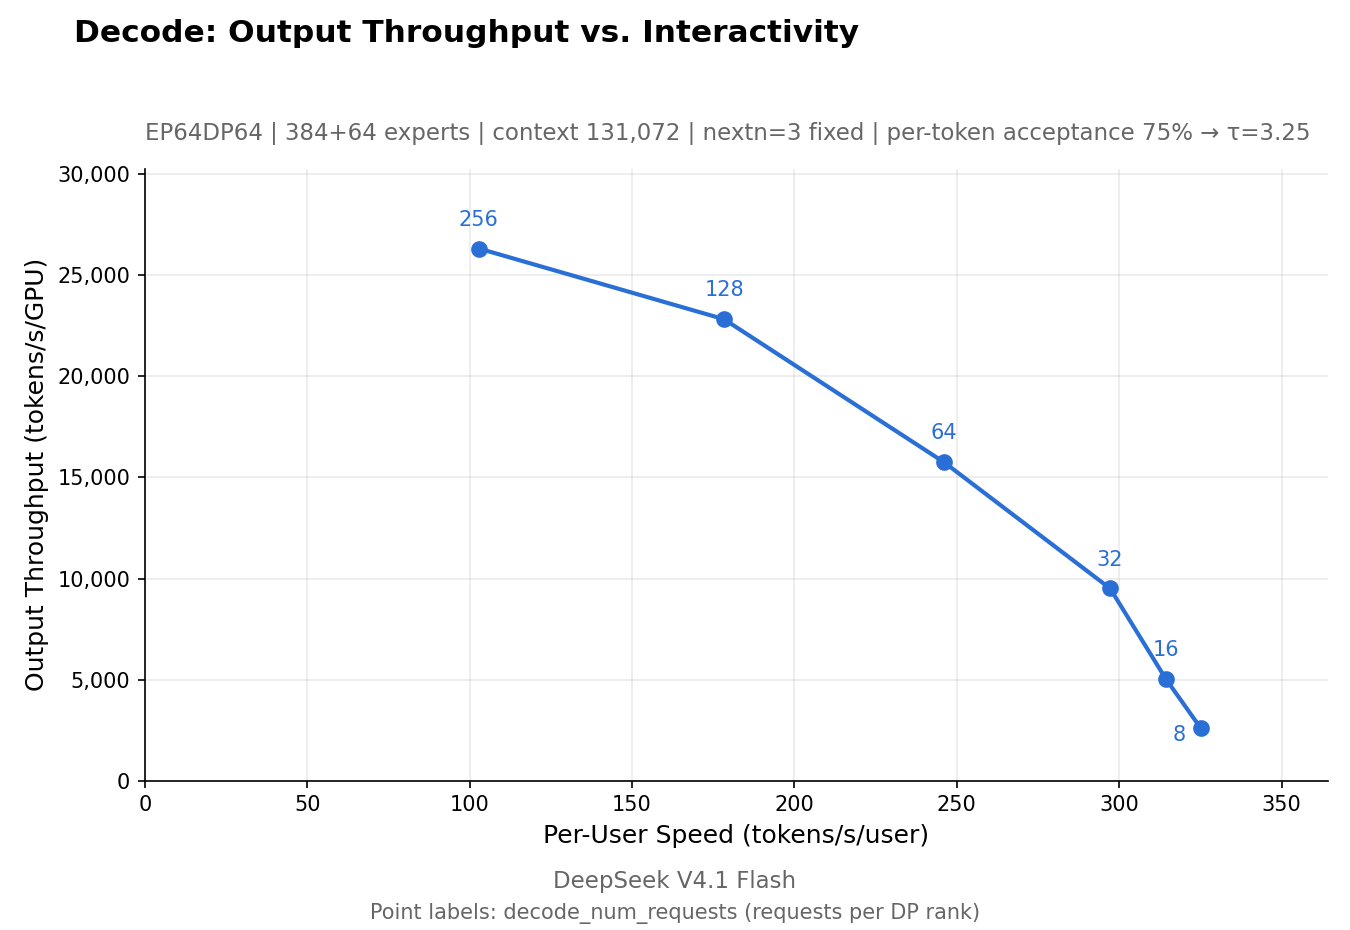
On Oct 20 (UTC) DeepSeek open-sourced DeepInfer (Apache 2.0), the in-house inference stack that serves DeepSeek-V4.1-Flash at scale. The release covers offline inference with Attention DP/CP and MoE EP+EPLB parallelism, DSpark speculative decoding, SWA bounded replay, batch-invariant inference, deterministic sampling and structured outputs on NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. The KV cache system, prefill/decode disaggregation and load balancing are not included. DeepSeek also released deepseek-recipe (MIT), which converts Chat Completions, Messages and Responses requests and encodes them the same way the official API does.

DeepSeek open-sources DeepInfer, the inference framework behind its V4.1-Flash production service, with speculative decoding, batch-invariant inference and structured outputs, plus the deepseek-recipe API encoding library

Key Takeaways

  • DeepInfer is Apache 2.0 and, per DeepSeek, is the framework serving DeepSeek-V4.1-Flash in production; it currently supports only that model
  • Hardware is limited to NVIDIA SM100 (Blackwell) GPUs and Huawei Ascend 950 NPUs; the official Pareto curves were measured on 4 GPUs for prefill and 64 for decode
  • The open release omits the KV cache system, VE/prefill/decode disaggregation and cross-replica load balancing, so it is not a full serving stack yet
  • DeepSeek's reference V4.1 scores (Pass@1, vendor-reported): AIME 2026 99.9%, GPQA Diamond 93.4%, HLE-Full 42.6%, meant as a deployment sanity check
  • deepseek-recipe (MIT, Rust with Python bindings) handles Chat Completions/Messages/Responses conversion and token encoding/decoding
Read full story
Linked Models & Agents:
⚡ DeepSeek-V4.1-Flash-1017🌐 DeepSeek🌐 NVIDIA🌐 Huawei

Unsloth v0.1.900-beta: local Laya Decision models + Skills editor; ~4.5× LTX-2.3 clips and up to 6.3× faster VAE decode

Unsloth shipped v0.1.900-beta on 2026-09-28 (PyPI unsloth 2026.9.12): Desktop runs Laya Decision models locally via a Jev-compatible /v1/systemone endpoint, adds a Skills CRUD editor and Library viewers for PDF/Office, and improves Apple Silicon with batched serving, structured outputs, and TurboQuant KV. Media pipelines claim ~4.5× LTX-2.3 clips, 1.7–6.3× VAE decode, and up to ~1 minute faster MiniMax-H3 first render with 25–29 GiB lower peak VRAM.

Unsloth v0.1.900-beta: local Laya Decision models + Skills editor; ~4.5× LTX-2.3 clips and up to 6.3× faster VAE decode

Key Takeaways

  • Shipped v0.1.900-beta — local Laya Decision API + Skills editor + Library viewers
  • LTX-2.3 ~4.5×; VAE decode 1.7–6.3×; MiniMax-H3 first render up to ~1 min faster, −25–29 GiB peak VRAM
  • Apple Silicon: batched serving, structured outputs, TurboQuant KV; ModelScope downloads
  • Docs: docs.unsloth.ai
Read full story
Linked Models & Agents:
⚡ Laya⚡ LTX-2.3⚡ MiniMax-H3⚡ Gemma-4🤖 Unsloth-Studio🌐 Unsloth

OpenAI enables Structured Outputs for o3-mini API with 120 tokens/s high-speed reasoning throughput

OpenAI rolled out strict JSON Schema Structured Outputs and function calling for the o3-mini API. Supported by new reasoning kernel optimizations, generation speed reaches 120 tokens/s, allowing coding agents to produce type-safe interfaces and AST payloads with zero JSON syntax drift at low latency.

Key Takeaways

  • Guarantees 100% JSON Schema adherence, eliminating syntax parsing failures during tool use.
  • Achieves up to 120 tokens/s decoding throughput, an 80% speedup over previous reasoning models.
  • Offers low, medium, and high reasoning effort toggles for varied latency and depth needs.
Read full story
ADSponsored