
AI Coding Live News

NVIDIA open-sources Nemotron 3.5 Bolt E4B 4GB, a Gemma 4 E4B-based small model for local assistants, characters and robots with tool use

On 2026-10-23 (15:41 UTC) the official @NVIDIAAI account announced Nemotron 3.5 Bolt E4B 4GB, a small open model for local assistants, interactive characters and robots that can hold a conversation and use tools. The official Hugging Face model card says it is post-trained from Gemma-4-E4B-it, has 8B total parameters (4B effective), ships in Q4_K_M quantization, supports up to 64K input and 64K output tokens, and has a switchable thinking mode, plus a DFlash speculative-decoding drafter and a BF16 version. Weights, data and recipes are open under the OpenMDW-1.1 license, with commercial use allowed. On the model card the 4GB build scores 55.60 on MultiChallenge (Gemma4 E4B-it at the same quantization 39.36, Qwen3.5 4B 52.23), but trails Qwen3.5 4B on Tau2-Bench (52.32) and BFCL-v3 (67.31).

NVIDIA open-sources Nemotron 3.5 Bolt E4B 4GB, a Gemma 4 E4B-based small model for local assistants, characters and robots with tool use

Key Takeaways

  • NVIDIA officially released Nemotron 3.5 Bolt E4B 4GB for local assistants, interactive characters and robots
  • Post-trained from Gemma-4-E4B-it: 8B total parameters (4B effective), Q4_K_M quantization, 64K context, switchable thinking mode
  • Open weights, data and recipes under the OpenMDW-1.1 license with commercial use allowed, plus a DFlash speculative-decoding drafter
  • Model card results: 55.60 on MultiChallenge leads its size class, but it trails Qwen3.5 4B on Tau2-Bench and BFCL-v3
Read full story
Linked Models & Agents:
⚡ Nemotron 3.5 Bolt E4B⚡ Gemma 4 E4B🌐 NVIDIA🌐 Google

ElevenLabs launches Eleven Realtime v1 Mini and Max speech-to-speech models: Max scores 98.8% on Big Bench Audio, speaks in 0.57s on average, and is OpenAI Realtime API compatible

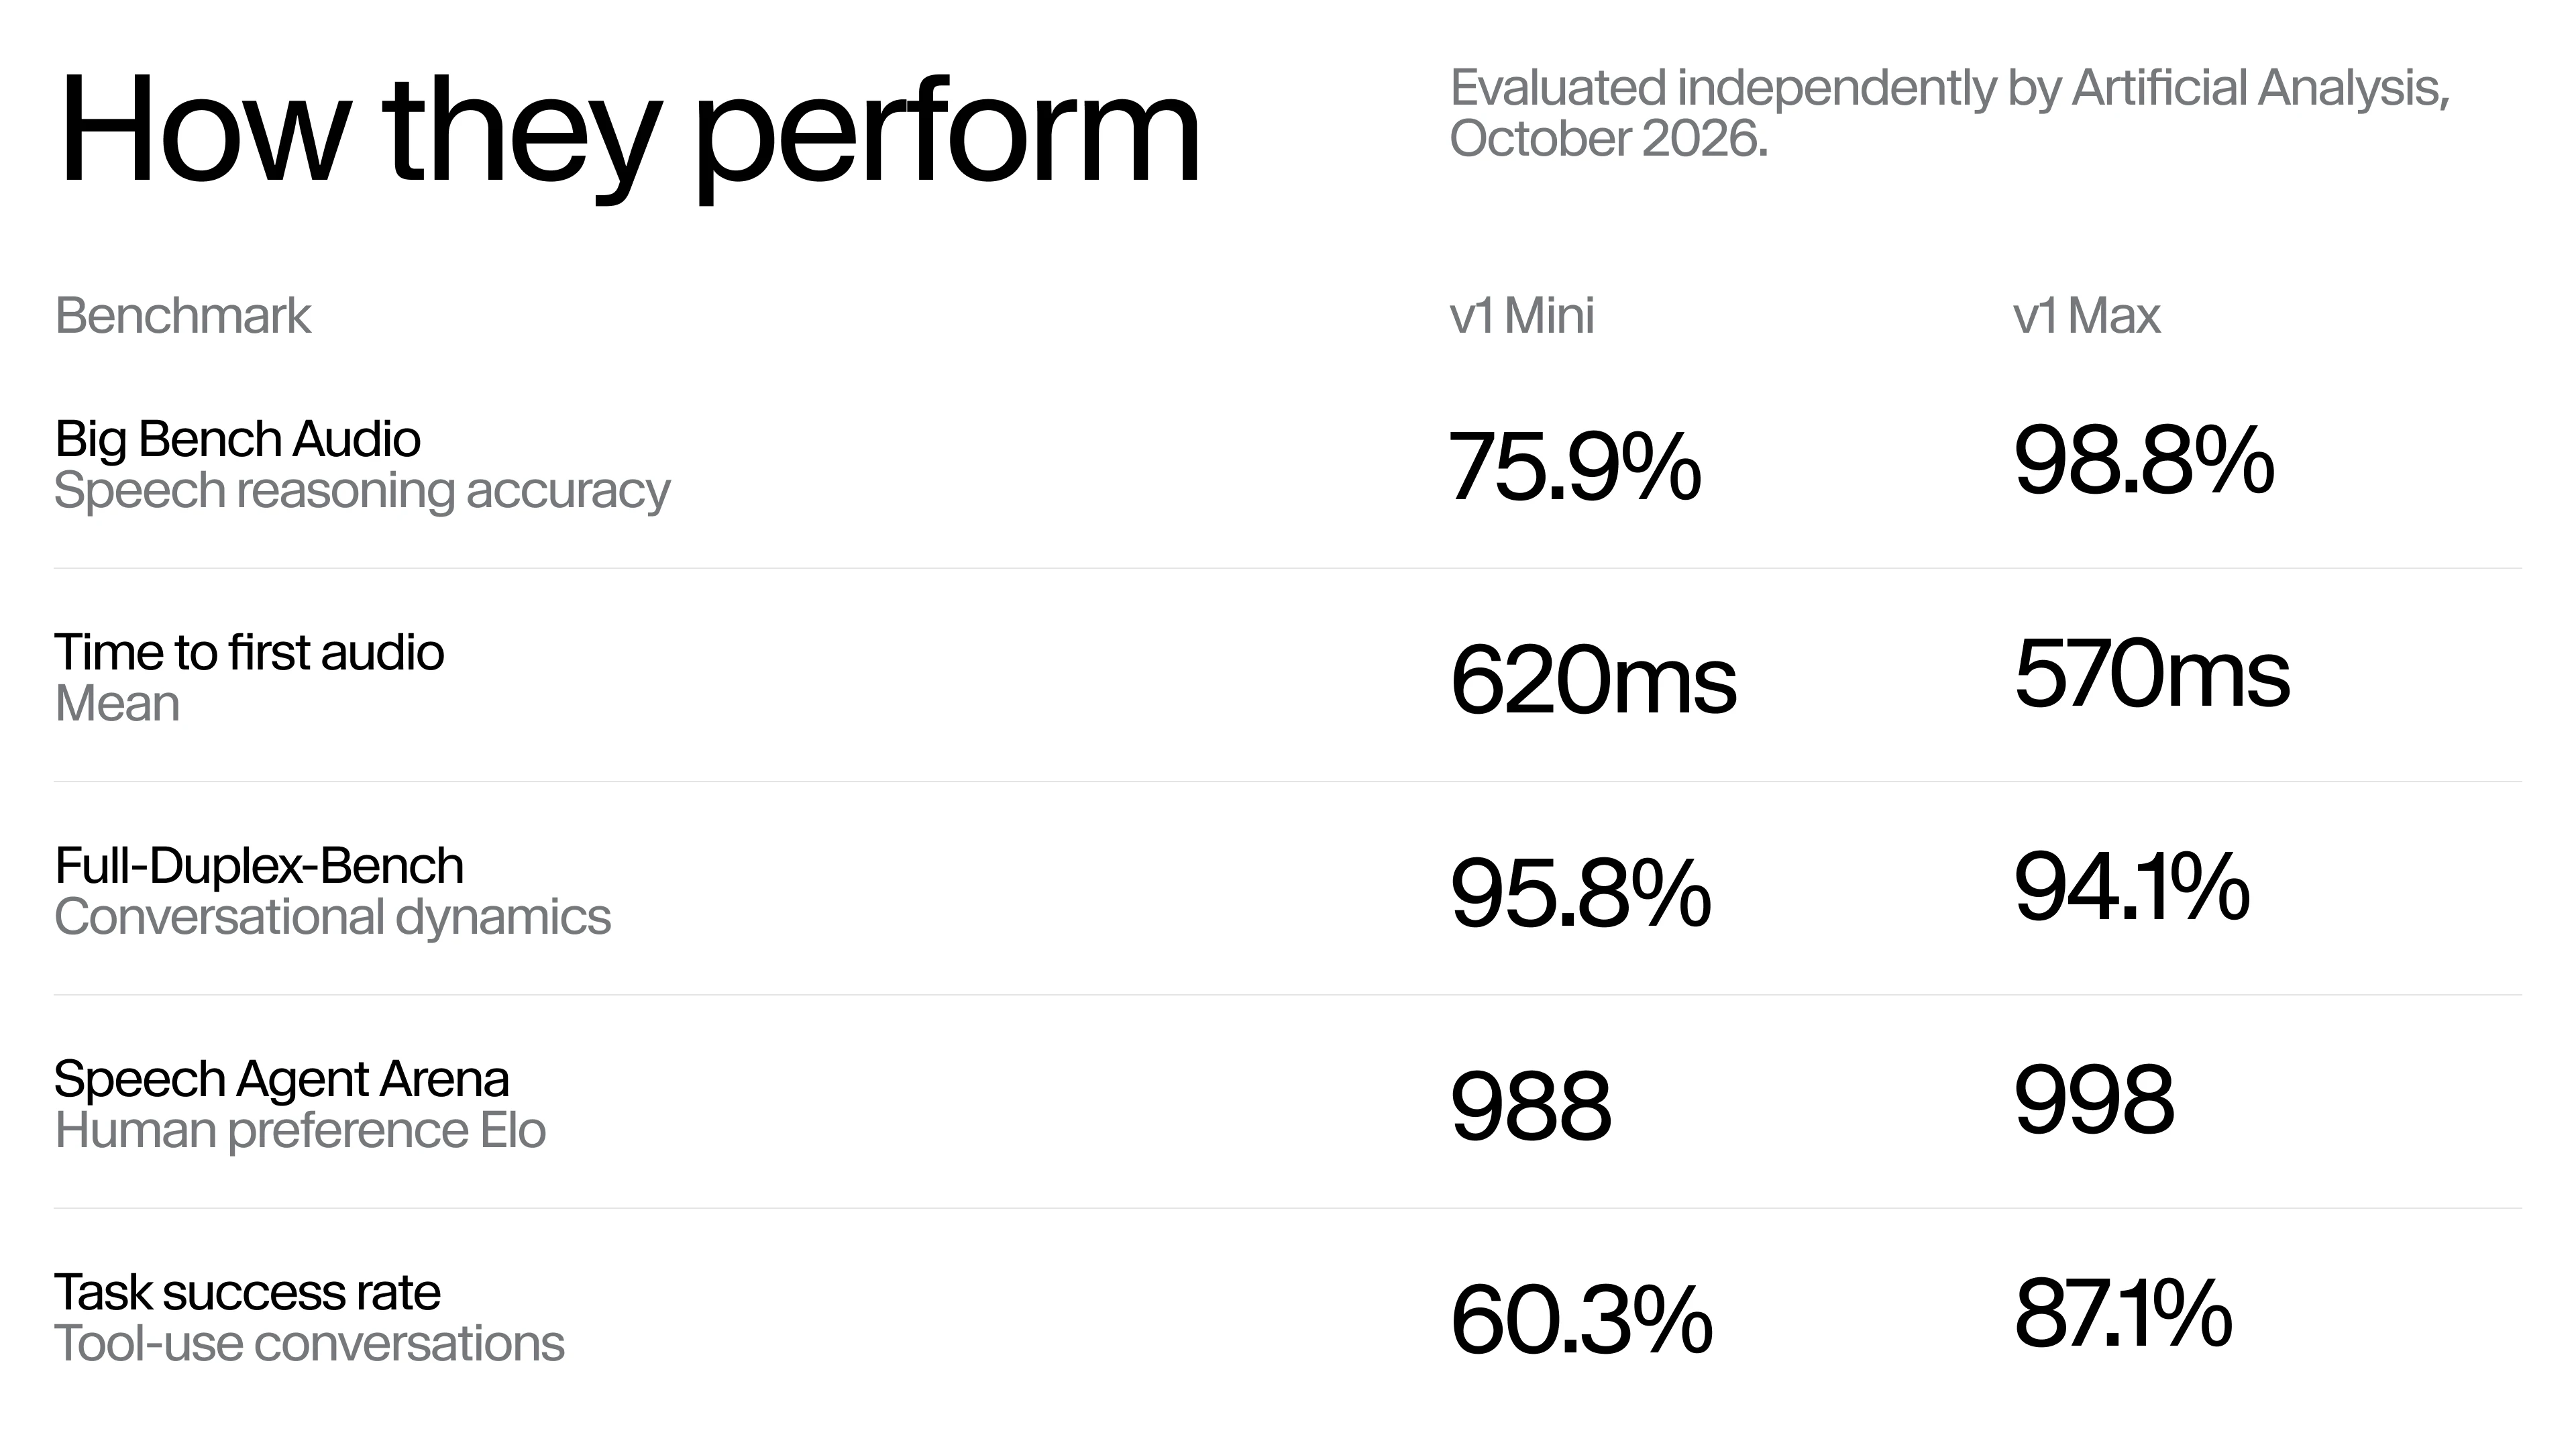
On Oct 20 ElevenLabs released Eleven Realtime, end-to-end speech-to-speech models where each model is a complete voice agent, removing the need to wire up speech recognition, an LLM and text-to-speech yourself. v1 Mini targets low-cost natural conversation and v1 Max targets support and multi-step tool use. Both cover 90+ languages and 17,000+ voices. Citing independent Artificial Analysis evals, Max answers 98.8% of Big Bench Audio correctly and starts speaking in 0.57s on average. The API is OpenAI Realtime compatible, so migrating means changing the endpoint and model name.

ElevenLabs launches Eleven Realtime v1 Mini and Max speech-to-speech models: Max scores 98.8% on Big Bench Audio, speaks in 0.57s on average, and is OpenAI Realtime API compatible

Key Takeaways

  • Speech reasoning (independent Artificial Analysis eval cited by ElevenLabs): on 1,000 Big Bench Audio questions, v1 Max scores 98.8% and v1 Mini 75.9%
  • Speed (vendor-stated): Max starts speaking in 0.57s on average and Mini in 0.62s; the launch post says "half a second", slightly faster than the blog figures
  • Conversation dynamics and preference: Full-Duplex-Bench Mini 95.8%, Max 94.1%; Speech Agent Arena blind tests Max 998, Mini 988
  • Tool-use task completion: Max 87.1% vs Mini 60.3%, which is why ElevenLabs recommends Max for heavy tool calling
  • 90+ languages and 17,000+ voices; the Realtime API is WebSocket-only at wss://api.elevenlabs.io/v1/convai/realtime and works with the OpenAI SDK; pricing was not in the launch post
Read full story
Linked Models & Agents:
⚡ Eleven Realtime v1 Mini⚡ Eleven Realtime v1 Max🤖 ElevenAgents🌐 ElevenLabs🌐 Artificial Analysis

Liquid AI open-sources LFM2.5-24B-A2B: a 24B-total, ~2B-active reasoning MoE built for on-device agents and tool use

On Oct 13 Liquid AI released LFM2.5-24B-A2B, the largest and final LFM2.5 model: 24B total parameters, ~2.45B active per token, 131K context, and always-on reasoning. By Liquid's own numbers it leads or matches Qwen3.6-35B-A3B on 5 of 8 tool-use/agent benchmarks (AutomationBench 27.69 vs 8.72) while trailing on SWE-Bench Verified, GPQA and other knowledge/coding tests. Open weights are on Hugging Face with GGUF, MLX, FP8 and ONNX builds; API pricing is $0.10 / $1.00 per million tokens and it is also on OpenRouter.

Liquid AI open-sources LFM2.5-24B-A2B: a 24B-total, ~2B-active reasoning MoE built for on-device agents and tool use

Key Takeaways

  • Specs (model card): 24.0B total / 2.45B active, 40 layers (30 gated short-conv + 10 GQA), 64 experts top-4, 131,072 context, 128K vocab
  • Agent benchmarks (vendor-reported, vs Qwen3.6-35B-A3B): AutomationBench 27.69 vs 8.72, LiveClaw 48.09 vs 38.19, ToolSandbox 80.71 vs 75.02, BFCLv4 65.01 vs 65.00
  • Disclosed weaknesses: SWE-Bench Verified (OpenCode) 51.00 vs 66.20, GPQA Diamond 74.42 vs 83.69, WebArena Verified 26.75 vs 37.62
  • Speed: 184 tok/s decode on Apple M5 Max, 114 tok/s on Ryzen AI Max+ 395, 21K+ output tok/s on one B300 with SGLang
  • Training: pretraining scaled 17T to 33T tokens; agentic RL inside OpenClaw, Hermes Agent, Pi and OpenCode; API $0.10 in / $1.00 out per M tokens
Read full story
Linked Models & Agents:
⚡ LFM2.5-24B-A2B⚡ LFM2.5-24B-A2B-Base⚡ LFM2-24B-A2B⚡ Qwen3.6-35B-A3B⚡ Gemma-4-26B-A4B-it🤖 Hermes Agent🤖 OpenClaw🤖 OpenCode🤖 Pi🌐 Liquid AI🌐 Hugging Face🌐 OpenRouter

IQuest-Q1 open-weights 320B MoE coding agent: 15B active / 524K context; DeepSWE 64.6, Terminal-Bench 2.1 83.2

IQuest Research’s IQuest-Q1 (~320B total / 15B active, 524K context) targets repo-level coding, terminal work, and long-horizon tool use. Weights and serving images are on Hugging Face / GitHub. Self-reported same-pipeline scores: DeepSWE v1.1 64.6, NL2Repo 63.0, CyberGym 84.5, Terminal-Bench 2.1 83.2. Ships with SGLang/vLLM images and Claude Code / Codex integration notes.

IQuest-Q1 open-weights 320B MoE coding agent: 15B active / 524K context; DeepSWE 64.6, Terminal-Bench 2.1 83.2

Key Takeaways

  • Spec: ~320B MoE / ~15B active, 88 layers, 256 experts / 8 active, 524,288 context; hybrid 3×SWA+1×FA (HF card)
  • Agentic coding (self-reported): DeepSWE v1.1 64.6 (DeepSeek-V4.1-Flash 74.2 / Opus 5 73.7); NL2Repo 63.0 (Opus 5 75.3)
  • Terminal / cyber: Terminal-Bench 2.1 83.2; CyberGym 84.5 (tied with GLM-5.3; Flash 88.1)
  • Post-train: SFT+RL plus Multi-Teacher On-Policy Distillation (MOPD); vendor flags early-stage, text-only limits
  • Ship: hf download IQuestLab/IQuest-Q1 + sglang-iquest-q1 / vllm-iquest-q1 images (tp=8); Claude Code 2.1.140 / Codex 0.142 notes
Read full story
ADSponsored

KaliBench Sets Deterministic Benchmark for Cybersecurity CLI Tool Use: 8B Model Rivals 685B MoE via Verifiable Rewards

Large language models are rapidly deployed across cybersecurity workflows to translate analysts' intent into command-line interface (CLI) executions. However, existing benchmarks emphasize either high-level knowledge QA or unconstrained agent rollouts, failing to measure precise parameter binding across real-world security tooling where minor syntax glitches invalidate execution. Researchers from MBZUAI introduce KaliBench, a fine-grained natural-language-to-CLI benchmark on Kali Linux spanning 8,504 query-command pairs across 1,642 tools, 23 capability dimensions, and 5 security phases. Auditing reveals no open-weight model surpasses 42% exact accuracy without tool hints. Furthermore, reinforcement learning with KaliBench's runtime-free verifiable rewards elevates an 8B model to rival a 685B MoE frontier model.

KaliBench Sets Deterministic Benchmark for Cybersecurity CLI Tool Use: 8B Model Rivals 685B MoE via Verifiable Rewards

Key Takeaways

  • First fine-grained cybersecurity CLI benchmark spanning 1,642 Kali Linux tools and 8,504 verified query-command pairs
  • Reveals open-weight models fail to exceed 42% exact CLI accuracy in unconstrained real-world settings
  • Introduces runtime-free verifiable rewards, empowering an 8B model to match a 685B parameter MoE architecture
Read full story
Linked Models & Agents:

KRAFTON Unveils PUBG Ally: Real-Time Conversational Embodied AI Teammate Validated Across 39K Live Sessions

KRAFTON and PUBG Studios have released 'PUBG Ally: A Conversational Embodied Agent as an AI Teammate' (arXiv: 2609.29837), unveiling the first voice-enabled, real-time conversational embodied agent deployed in AAA competitive gaming. Addressing the challenge of synchronizing spoken dialogue with high-frequency tactical gameplay under strict latency constraints, Ally couples an LLM meta-agent for tactical reasoning, speech interpretation, and contextual tool use with a decoupled high-speed control layer for movement, combat, and healing. Iteratively trained on nearly 39,000 live sessions with human teammates across 141 countries, Ally boosted player recommendation rates by 25.1 percentage points.

KRAFTON Unveils PUBG Ally: Real-Time Conversational Embodied AI Teammate Validated Across 39K Live Sessions

Key Takeaways

  • Fuses real-time duplex conversational audio with millisecond-level competitive game control in high-stakes AAA battle royale.
  • Implements hierarchical embodied control: high-level LLM handles tactical reasoning and dialogue; low-level policy executes movement and combat.
  • Trained on an unprecedented dataset spanning nearly 39,000 live sessions with human squadmates across 141 countries.
  • Player survey shows positive recommendation scores outperforming negative responses by 25.1 percentage points.
  • Preprint, latency-reduction context compaction algorithms, and real-time safety guardrails published openly on arXiv and Hugging Face.
Read full story

Alibaba Launches Qwen3.8-Omni-Flash: 1M Context Omni-Modal Model with 60% Lower Cost

Alibaba Cloud unveiled Qwen3.8-Omni-Flash, a 1-million-token omni-modal model optimized for real-time audio-video perception, low-latency voice, and agentic tool use with a 60% inference cost reduction. Concurrently, Alibaba announced an in-cabin AI partnership with BYD.

Key Takeaways

  • Supports 1M token context for low-latency full-duplex omni-modal conversational streaming
  • Slashes multimodal and audio inference expenses by more than 60%
  • Powers BYD next-generation smart cockpit with autonomous in-cabin task orchestration
Read full story
Linked Models & Agents:

Qwen ships Qwen3.8-Omni-Flash: first agentic native omni-modal model, ~89% cheaper video input

Alibaba Qwen officially launched Qwen3.8-Omni-Flash: native audio-video understanding, reasoning, and tool use in one model for agentic workflows such as auto-editing vlogs, translating short videos, and movie recaps. It approaches Gemini 3.8 Flash on audio-video, gains about +19.5 points average agent score on WildClawBench-MM and UniClawBench, offers 1M context, open-sources Qwen-MM-Plugins, and cuts video input cost by about 89% versus Qwen3.5-Omni-Plus.

Key Takeaways

  • Official @Alibaba_Qwen release of Qwen3.8-Omni-Flash: native omni-modal + tool orchestration for long-horizon A/V agent workflows.
  • Approaches Gemini 3.8 Flash on A/V; about +19.5 avg agent points on WildClawBench-MM / UniClawBench; 1M context with ~51.8% fewer tokens on OmniVideoBench.
  • ~89% lower video input cost vs Qwen3.5-Omni-Plus; open-sources Qwen-MM-Plugins; Qwen-Live Harness coming; API/Studio/blog live.
Read full story
Linked Models & Agents:
⚡ Qwen Qwen3 8 Omni Flash🌐 Qwen (通义千问)

PrismML releases Ternary Bonsai 2 27B: 5.9 GB with 98.2% benchmark retention for agentic coding

PrismML released Ternary Bonsai 2 27B, a ternary-weight model based on Qwen3.8 27B. It is about 5.9 GB—roughly 9x smaller than the full-precision counterpart—while retaining 98.2% of aggregate benchmark performance. PrismML says the release improves agentic coding, multimodal reasoning, and long-horizon tool use, and ships under Apache 2.0.

Key Takeaways

  • The ternary-weight model is about 5.9 GB and 9x smaller than its full-precision counterpart.
  • PrismML reports 98.2% aggregate benchmark retention with gains in agentic coding, multimodal reasoning, and long-horizon tool use.
  • It is available under Apache 2.0 with Hugging Face weights, a paper, a WebGPU demo, and a supporting llama.cpp fork.
Read full story

Salesforce launches Koa, its first CRM reasoning model on NVIDIA Nemotron, now in Agentforce pilot

At Dreamforce, Salesforce and NVIDIA announced Koa—Salesforce’s first CRM reasoning model for Agentforce—built by post-training NVIDIA Nemotron 3 Super on a proprietary synthetic corpus modeled on nearly three decades of CRM deployments. Salesforce says Koa matches or exceeds leading models on its CRM benchmark with about 3× fewer CRM-action errors, targets complex multi-step workflows and tool use, and was trained with no customer data. The partners are also bringing Nemotron-based models and accelerated computing into Missionforce for private-cloud and air-gapped government use. Koa is in pilot now.

Key Takeaways

  • Koa is Salesforce’s first CRM reasoning model for Agentforce, post-trained on Nemotron 3 Super
  • CRM benchmark: matches/exceeds leading models with ~3× fewer CRM-action errors; no customer data used
  • Nemotron + accelerated compute also headed to Missionforce; Koa is in pilot
Read full story
Linked Models & Agents:
ADSponsored

Artificial Analysis: GPT-Live-1 (Astra) tops Speech to Speech Index at 81.5

Artificial Analysis (@ArtificialAnlys) published its Speech to Speech Index: OpenAI GPT-Live-1 with Astra (medium) as the delegated backend debuts at #1 with 81.5, while Sol (low) scores 80.1 at #3, with Grok Voice Think Fast 2.0 High between them at 81.3. GPT-Live-1 is a full-duplex speech model that can delegate reasoning and tool use to a backend text model mid-conversation. The same drop covers Speech Agent Arena, Tau Voice, Big Bench Audio, plus cost and time-to-first-audio.

Key Takeaways

  • GPT-Live-1 (Astra medium) leads Speech to Speech Index at 81.5; Sol low is #3 at 80.1.
  • On Tau Voice, Astra medium (67.9%) and Sol low (59.3%) take the top two agentic spots.
  • Cost is about $5.83/$4.47 per hour of input audio incl. backend; TTFA about 1.34s/1.24s vs Grok Voice 0.70s.
Read full story
Linked Models & Agents:

Shanghai AI Lab open-sources Atria Dawn Preview: long-horizon agentic model on 744B MoE GLM-5.2, MIT

Shanghai AI Lab released Atria Dawn Preview, an agentic foundation model for long-horizon research/engineering tasks built on the 744B-parameter MoE GLM-5.2, with tool use and executable verification loops. Weights are on Hugging Face (internlm) and ModelScope, plus an FP8 build, 256K context, GitHub, website, and API try links.

Key Takeaways

  • Atria Dawn Preview is built on 744B MoE GLM-5.2 for long-horizon research and engineering agents.
  • Open weights on Hugging Face/ModelScope with FP8 and 256K context under MIT.
  • Covers Discovery/Creation/Delivery/Cybersecurity end-to-end scenarios with API try access.
Read full story
Linked Models & Agents:

Shanghai AI Lab Intern-S2-397B ships BF16/FP8: 84.0 SWE-bench Multilingual, Apache-2.0

ModelScope announced Shanghai AI Laboratory Intern-S2-397B weights in BF16 and FP8 under Apache-2.0. Reported scores include 87.0 on FrontierScience-Olympiad and 84.0 on SWE-bench Multilingual, with long-horizon agent RL, tool use, and thinking/non-thinking modes. Training ingests raw scientific pages (text, visuals, symbols) across 20+ domains. Collection on ModelScope.

Key Takeaways

  • BF16 and FP8 weights are public under Apache-2.0 on ModelScope.
  • Reported 84.0 SWE-bench Multilingual and 87.0 FrontierScience-Olympiad as comparison leaders.
  • Long-horizon agent RL targets tool use and sustained execution, with thinking and non-thinking modes.
Read full story
Linked Models & Agents:

AWS open-sources Pizza Bot: email-style inbox for background AI agents, Apache-2.0 self-hosted

AWS open-sourced Pizza Bot (Apache-2.0), rebuilt from an internal Amazon tool used by 2,000+ people. The self-hosted app presents background agent results and pending decisions in an email-style inbox, supports Bedrock/Anthropic/Gemini/OpenAI/OpenRouter/Ollama, plus MCP servers, SKILL.md workers, and interrupt/approval policies across desktop/browser/terminal.

Key Takeaways

  • Born as an internal Amazon tool; now Apache-2.0 and self-hostable.
  • Email-style inbox for completed agent work and pending approvals.
  • Multi-provider models plus MCP, SKILL.md workers, and interrupt/approval policies.
Read full story
Linked Models & Agents:

OpenAI launches Agents API: managed cloud agents on Codex harness with tools and sandboxes

OpenAI launched the Agents API—a managed cloud agent service powered by the Codex harness for orchestration, long-running sessions, and tool use. Bring connectors, attach any sandbox, and run agents with Astra.

Key Takeaways

  • Managed Agents API ships on the Codex harness.
  • Supports tools/connectors, arbitrary sandboxes, and long-running orchestration.
  • Aimed at builders running cloud agents with Astra; official blog live.
Read full story
