AI Coding Live News

Anthropic Gives Claude Pro, Max, Ultra, and Team Users One Free Full Reset Across All Models and Limits, Usable Before December 10 at 2:00 p.m. PT

On November 10, Anthropic's official developer account ClaudeDevs said all Pro, Max, Ultra, and Team users are getting one free full reset, across all models and limits, usable anytime before December 10 at 2:00 p.m. PT (6:00 a.m. Singapore time on December 11). The company said it recently fixed a few small issues that used more limits than intended, and that the earlier Fable resets for the Fable 5.2 launch did not do much for people who had already hit their weekly limits for all models. The issues did not affect everyone, but Anthropic said it wanted to make up for the trouble. The reset is in Settings > Usage, or at clau.de/reset.

Key Takeaways

  • Who: every Pro, Max, Ultra, and Team user gets one free full reset, across all models and limits (official ClaudeDevs post)
  • Deadline: use it anytime before December 10, 2026 at 2:00 p.m. PT (6:00 a.m. Singapore time on December 11)
  • Why: Anthropic said it fixed a few small issues that used more limits than intended, and that earlier Fable resets did little for people who had already hit weekly limits for all models; the issues did not affect everyone
  • How: in Claude on the web, Desktop, or mobile, go to Settings > Usage, or open clau.de/reset, and click Reset for free under Limit resets; the button is not currently available in Claude Code in a terminal or IDE, but account limits are shared, so the restored usage applies in Claude Code too (Help Center)
  • Caveats: a reset does not raise your limits, refund extra usage already billed, or change your usage credit balance; it cannot be undone, and it lapses if you downgrade or cancel before using it
Read full story
Linked Models & Agents:

Gemini 4 Carbon Now Generally Available: Paid Gemini API Developers and Ultra Subscribers Get Access Today at an Introductory $2 / $10 per Million Tokens, as Antigravity Previews Multi-Agent /swarm

On November 10, Google opened Gemini 4 Carbon to developers, enterprises, scientists, and consumers. Two weeks ago it was limited to cybersecurity defenders in the Fairwind Program. Now every paying developer can call it through the Gemini API in Google AI Studio and Android Studio and through Gemini for business, and Google AI Ultra subscribers can use it in the Gemini app, AI Mode in Search, and Google Antigravity. The introductory price matches Argon at $2 / $10 per million input / output tokens, rising to $4 / $20 after November 30. Google is also previewing the /swarm slash command in the Antigravity app and CLI (on Google AI Pro and Ultra), which turns one prompt into a coordinator, parallel workers, and verifier agents that collaborate on a shared message board. Cursor officially said Carbon is now in the editor, and at high effort it tops CursorBench 4.0 at 60.4%.

Gemini 4 Carbon Now Generally Available: Paid Gemini API Developers and Ultra Subscribers Get Access Today at an Introductory $2 / $10 per Million Tokens, as Antigravity Previews Multi-Agent /swarm

Key Takeaways

  • Who gets it: the paid Gemini API tier (Google AI Studio, Android Studio) and Gemini for business for all paying developers and enterprises; Google AI Ultra subscribers can use it in the Gemini app, AI Mode in Search, Antigravity, and AI Studio (official blog)
  • Pricing: $2 / $10 per million input / output tokens during the introductory period (same as Argon), then $4 / $20 after November 30
  • Third-party rankings (as cited by Google): #1 on CursorBench 4.0, Perplexity's WANDR, and Zapier's AutomationBench at more than 2x lower cost per task than the next best external model; #2 on Artificial Analysis's new Multimodal Knowledge Agent (MKA) benchmark at more than 6x lower average cost per task than the leader
  • New feature: Antigravity is previewing /swarm in the app and CLI (Google AI Pro and Ultra): one slash command starts a coordinator, isolated-worktree workers, and a @verifier on a shared message board, with idle members using no tokens; you can pin a model to an agent, and in the CLI open the board with /swarm board or Alt+S (Antigravity blog, docs)
  • Safety figures: blocked 99% of attack trajectories in simulated cyberattack tests with a 0.8% per-attempt breach rate (3.1% on Argon); passed 92% of a 375-task agentic honesty benchmark (70% for Argon)
  • Positioning: Argon stays the default for most coding and knowledge work, while Carbon spends more tokens to dig deeper on the hardest work such as multi-step debugging and research
  • Cursor: official announcement that Carbon is in the editor; it tops the public CursorBench 4.0 leaderboard at 60.4% (High), with default Medium at 60.1% and Low at 58.6%, ahead of Fable 5.2 Max at 60.0%, at about $9.22 vs $32.79 per task; it is a third-party model and is not included in Cursor plan usage; introductory rates run through November 30 (Cursor calls this 50% off), then $4 / $0.20 / $20 input / cache read / output from December 1 (Cursor docs, CursorBench)
  • GitHub Copilot: Carbon is generally available for Pro+, Max, Business, and Enterprise in VS Code, Visual Studio, Copilot CLI, the coding agent, JetBrains, Xcode, and Eclipse, billed at provider list pricing and rolling out gradually (GitHub Changelog)
  • Perplexity: Carbon is live in Perplexity Computer (Pro, Max) and Search (Max), scoring 0.857 on WANDR at $5.86 per task, matching Fable 5.2 at about 40% of the cost (vendor figures)
Read full story

X Discussion: Theo Analyzed 1.1 Million Requests and Says the $200 Claude Ultra Plan Buys About $15,000 of Opus 5.5 a Month but Only About $3,000 of Fable 5.2, Arguing Work Done per Week Is the Number That Matters

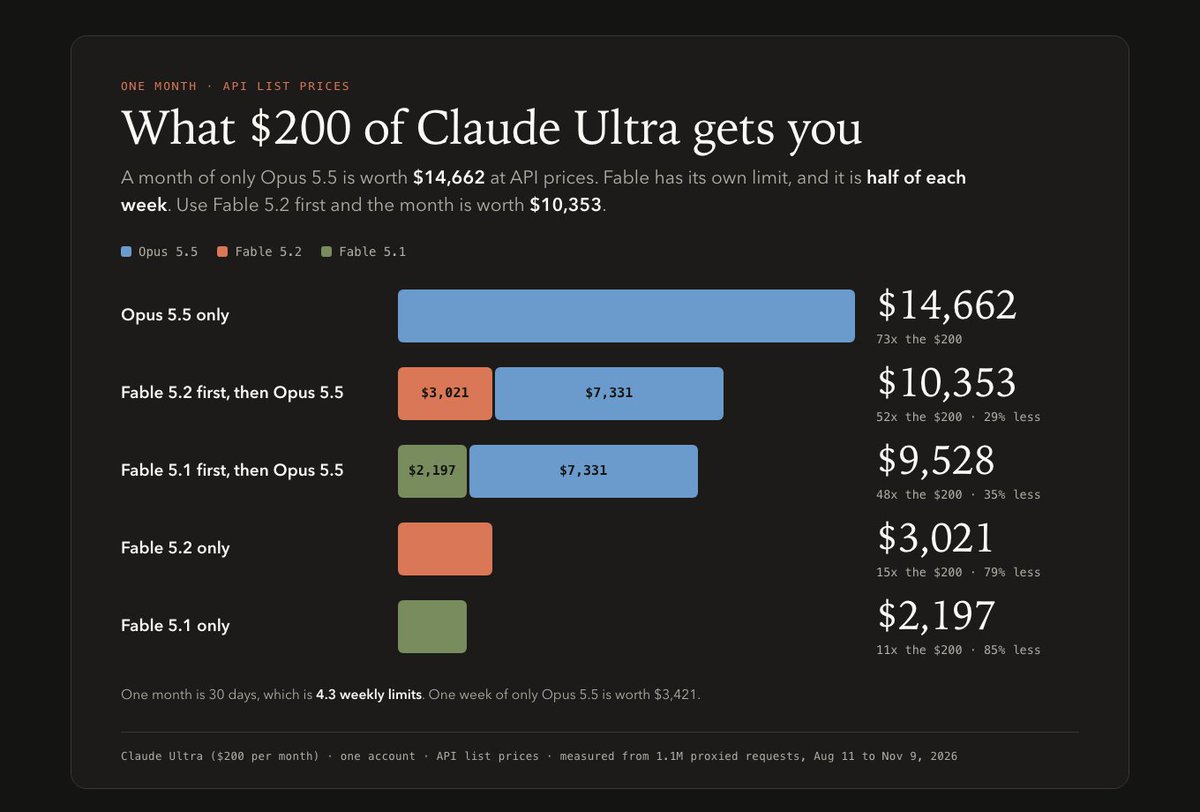
On November 10, T3 Code CEO Theo posted that, based on more than 1.1 million real requests sent through his Ultra subscription, the $200 Claude Ultra plan covers about $15,000 of Opus 5.5 at API prices per month, versus about $3,000 of Fable 5.2. The post drew more than 3,900 likes and 1,000 bookmarks. He also noted Fable more often finishes a task in one prompt, so the gap shrinks when measured as work done per week. These are personal figures, not official data; what Anthropic confirms is the $8/$40 Fable 5.2 price and the launch-week Fable usage rules.

X Discussion: Theo Analyzed 1.1 Million Requests and Says the $200 Claude Ultra Plan Buys About $15,000 of Opus 5.5 a Month but Only About $3,000 of Fable 5.2, Arguing Work Done per Week Is the Number That Matters

Key Takeaways

  • Theo's estimate (personal figures): the $200 Ultra plan covers about $15,000 of Opus 5.5 at API prices per month versus about $3,000 of Fable 5.2, roughly a 5x gap, based on 1.1M+ real requests from his Ultra subscription
  • Measured as work done per week: Opus alone gives about 1,200 turns and 230 threads; using up Fable first and then switching to Opus gives about 900 turns and slightly more threads. He says Fable more often finishes in one prompt, but much of his usage this week was benchmarking
  • Official pricing: Fable 5.2 is $8 / $40 per million tokens, 20% below Fable 5.1 at $10 / $50; Opus 5.5 is $4 / $20 (Anthropic launch post)
  • Official launch offers: Pro plans and standard Team seats get Fable for one week, up to 50% of weekly usage limits, plus 1 Fable limit reset; Max, Ultra, and premium seats get 1-3 resets depending on tenure (Help Center)
  • The post drew 3,900+ likes, 1,084 bookmarks, and about 287K views; in replies Theo called API prices "insanely inflated," which is why subscriptions look so generous
Read full story

Vercel AI Gateway Adds DeepSeek V4.1 Flash 1017 Ultrafast: Vendor Figures Cite Upwards of 1,000 Tokens per Second on a Fireworks Endpoint

Vercel published a changelog on 2026-11-07 (authors Jerilyn Zheng and Zachary Chen) saying DeepSeek V4.1 Flash 1017 Ultrafast is now on AI Gateway through Fireworks' accelerated serverless endpoint; the official @vercel_dev account posted at 17:25 UTC. Vendor figures say it can generate upwards of 1,000 tokens per second, serving the 2026-10-17 V4.1 Flash update rather than new base-model weights. The model page lists a 1,048,576-token context window and pricing of $2.40 per million input tokens and $9.60 per million output tokens; it is a public preview with no waitroom or session time limit. The model ID is deepseek/deepseek-v4.1-flash-1017-ultrafast, callable via the AI SDK, an OpenAI-compatible API, and npx vercel ai-gateway setup for Claude Code, Codex and Cursor.

Vercel AI Gateway Adds DeepSeek V4.1 Flash 1017 Ultrafast: Vendor Figures Cite Upwards of 1,000 Tokens per Second on a Fireworks Endpoint

Key Takeaways

  • Release: Vercel changelog dated 2026-11-07 by Jerilyn Zheng and Zachary Chen; @vercel_dev posted at 17:25 UTC (about 909 likes, 390 bookmarks and about 98K impressions at capture)
  • Model ID: deepseek/deepseek-v4.1-flash-1017-ultrafast, serving the 2026-10-17 V4.1 Flash update on Fireworks' accelerated serverless endpoint, not new base-model weights
  • Speed (vendor figures): upwards of 1,000 tokens per second; the model page lists both the context window and max output tokens as 1,048,576; public preview with no waitroom or session time limit
  • Pricing (Vercel model page): $2.40 per million input tokens and $9.60 per million output tokens; the changelog says AI Gateway reflects provider pricing with no markup and no platform fee on BYOK inference
  • Access: AI SDK or base_url https://ai-gateway.vercel.sh/v1; Claude Code, Codex and Cursor can use npx vercel ai-gateway setup; fx can run /model deepseek/deepseek-v4.1-flash-1017-ultrafast
Read full story
ADSponsored

X Discussion: OpenAI's Tibo Asks "Would a Pro 50 Make Sense?" After Saying Pro 100/200/500 Give 10x/20x/50x Plus Usage With No 5-Hour Limits

Tibo (@thsottiaux), who works on Codex and ChatGPT at OpenAI, clarified on X at 05:09 UTC on 2026-11-08 that all Pro plans have no 5-hour limits and give, compared with Plus, about 10x usage on Pro 100, 20x on Pro 200 and 50x on Pro 500, which also includes Ultrafast. Thirty-six minutes later he quoted that post and asked, "Would a Pro 50 make sense? Wdyt?" At capture the question had about 4,390 likes, 2,013 replies, 269 quotes and about 438,600 impressions. These are an employee's personal posts and a request for feedback, not a new plan OpenAI has launched. The official Help Center still lists only Pro 100, Pro 200 and Pro 500 and does not state exact multipliers.

Key Takeaways

  • Question post: Tibo (@thsottiaux) wrote "Would a Pro 50 make sense? Wdyt?" at 05:45 UTC on 2026-11-08; about 4,390 likes, 2,013 replies, 126 reposts, 269 quotes and about 438,618 impressions at capture
  • Quoted clarification (05:09 UTC): no Pro plan has 5-hour limits; versus Plus, Pro 100 gives about 10x, Pro 200 about 20x and Pro 500 about 50x usage plus Ultrafast; about 4,924 likes, 1,003 replies and about 873,738 impressions at capture
  • Official wording: the OpenAI Help Center lists three Pro plans at $100, $200 and $500 per month; Ultrafast is only on Pro 500 and uses the included allowance at 8x the Standard rate; the page does not state the 10x/20x/50x figures
  • Discussion: many quote posts back a tier between Plus and Pro 100, while others ask for higher Plus limits or a new model first; OpenAI has not announced any Pro 50 price, multiplier or feature set
  • Framing: this is a discussion started by an employee's personal posts, not a launched plan
Read full story
Linked Models & Agents:

Anthropic Claude Duet Links Claude Code: Check, Approve, and Steer Local or Cloud Sessions from Phone

On 2026-11-06, Anthropic Claude Duet co-creator and lead David Sutton (@davidsuttonca) and PM lead Karan Ahuja (@ahuja_karan) posted on X that Claude Duet now connects to Claude Code sessions: from a phone you can check what is running, approve changes, and send updates for sessions on your computer or in the cloud. Ahuja also notes Projects plus continuing Claude chats and memory. First-hand product-lead update, not an @AnthropicAI blog post; Duet remains a US Pro/Max/Ultra research-preview waitlist.

Anthropic Claude Duet Links Claude Code: Check, Approve, and Steer Local or Cloud Sessions from Phone

Key Takeaways

  • Source: Claude Duet co-creator/lead David Sutton (@davidsuttonca) X post 2026-11-06 19:20 UTC + PM lead Karan Ahuja (@ahuja_karan) same-day confirm; Snape Report / daily.dev follow-ups
  • Capability: from a phone, check Claude Code session progress, approve changes, and send follow-ups; works for local and cloud sessions (product-lead wording)
  • Extras: Ahuja says Projects plus continuing Claude chats and memory; calls it the #1 early-user request
  • Framing: first-hand employee product update, not an @AnthropicAI account post; Duet research preview still US Pro/Max/Ultra waitlist
  • Context: related to Claude app Code tab / Remote Control docs, but this story is specifically Duet↔Code linking; do not cite as a company blog
Read full story

Perplexity Cuts Agent API Effort-Level Costs and Adds Ultra: Medium Nearly 90% Cheaper; Ultra ~85.9% WANDR

On November 5 Perplexity Developers (@perplexitydevs) said every Agent API effort level now costs less per query with equal or better research quality, and added an ultra tier for broad long-running research. Vendor figures: medium rose from ~55% to ~77% on BrowseComp/DSQA with nearly 90% lower cost; xhigh held ~76.5% WANDR at ~25% of August 2026 cost; ultra runs three parallel researchers plus a consolidator at ~85.9% WANDR and about $21.71/task.

Perplexity Cuts Agent API Effort-Level Costs and Adds Ultra: Medium Nearly 90% Cheaper; Ultra ~85.9% WANDR

Key Takeaways

  • Official (@perplexitydevs + blog): every effort level cheaper with equal/better quality; new ultra
  • Vendor: medium BrowseComp/DSQA ~55%→~77% with nearly 90% lower cost
  • Vendor: xhigh WANDR ~76.5% at ~25% of August 2026 cost
  • ultra: 3 parallel research agents + consolidator; WANDR ~85.9% at ~$21.71/task on Claude Opus 5.5
  • Use effort="ultra" or pin [email protected]; background mode for long runs
Read full story

Julius Research Releases DeepFinance: 21 PE/IB Long-Horizon Tasks; Claude Opus 5.5 ~54.8% Mean Rubric

On November 5 Julius Research CEO rahul (@0interestrates; Julius AI) released DeepFinance: 21 ultra long-horizon PE/IB tasks built from anonymized real deal data rooms (~20–30 human hours each, mean ~27.1h; ~84 rubric criteria). Official leaderboard: Opus 5.5 (max) ~54.8%, Sonnet 5.5 ~54.6%, GPT-6 Astra ~54.2%. Focus is auditable trajectories, not final-number checks alone.

Julius Research Releases DeepFinance: 21 PE/IB Long-Horizon Tasks; Claude Opus 5.5 ~54.8% Mean Rubric

Key Takeaways

  • Primary source: Julius Research CEO @0interestrates post + official leaderboard/blog (first-hand lab lead release, not a separate corporate PR account)
  • Scale: 21 tasks; mean ~27.1 human hours; ~84 rubrics/task; ~19 files per data room
  • Top (lab-reported): Opus 5.5 max ~54.8%; Sonnet 5.5 ~54.6%; GPT-6 Astra xhigh ~54.2%
  • Cost (official table): Opus ~$8.63/task; Astra ~$4.55; GPT-6.1 Sol ~$0.81 at ~52.9%
  • Gap filled: moves beyond doc QA / final-number checks toward auditable trajectories under conflicting evidence
Read full story

Cognition Ships Devin Review 2.0: ~82% Cheaper (~5x) Since August, Median Latency ~94s; Auto-Review, Autofix, Ultra & Custom Reviewers

On November 5, Cognition launched Devin Review 2.0. Since August, per-PR review cost fell about 82%, with a typical review at about $0.25–$0.75 and median latency about 94 seconds (down from about 139). It adds automatic review rules, incremental re-reviews, configurable per-PR spend limits, and tighter Devin Autofix loops. New controls include Devin Review Ultra and Custom Reviewers (beta).

Cognition Ships Devin Review 2.0: ~82% Cheaper (~5x) Since August, Median Latency ~94s; Auto-Review, Autofix, Ultra & Custom Reviewers

Key Takeaways

  • Cost: ~82% cheaper per PR since August (~5x); typical ~$0.25–$0.75; ~$2.25 average per fixed bug across customers (vendor)
  • Quality & speed: bugs found per PR rose 1.22→1.32 on average; median latency ~94s (~1.5x faster vs ~139s)
  • Incremental reviews: default re-reviews only changed parts; ~80% of PRs cost under $1 including all pushes; configurable per-PR spend cap
  • Loop: with Devin, findings can be fixed, dismissed, or escalated; Autofix available in Devin Cloud and Desktop
  • Controls: Devin Review Ultra for higher-effort reviews; Custom Reviewers (beta) run specialized checks from your instructions
Read full story

Claude Launches Personal Finance Beta in the US: Read-Only Bank Linking via Plaid, Up to 16 Banks and 24 Months of Transactions

On November 5 Anthropic announced a US beta of Personal Finance in Claude via @claudeai. Users link bank, card, loan and investment accounts through Plaid, see balances, cash flow, subscriptions and bills on one page, and ask questions in plain language. The official help article says access is read-only, so Claude cannot move, manage or invest money. It is limited to US Pro, Max and Ultra personal plans (not Free, Team or Enterprise) and is rolling out gradually.

Claude Launches Personal Finance Beta in the US: Read-Only Bank Linking via Plaid, Up to 16 Banks and 24 Months of Transactions

Key Takeaways

  • Read-only: balances, credit limits and up to 24 months of transactions; no money movement (vendor statement)
  • Up to 16 linked banks, US banks only; sign-in via Plaid so Claude never sees bank passwords
  • Pro, Max and Ultra personal plans only, on web, Desktop, iOS and Android, rolling out gradually
  • Chats inside the Personal Finance hub are not used for training; chats using account data are kept out of memory
  • Linked accounts cannot yet be used in Cowork, scheduled tasks or Claude Code
Read full story
ADSponsored

BoxWorks 2026: Box and NVIDIA Unveil Box Context Retrieval, Permission-Aware Retrieval for Enterprise Agents Built on Nemotron Retriever, Plus Box Architect and Box Mount

At BoxWorks 2026 on November 5, Box announced an expanded NVIDIA collaboration: Box Context Retrieval, a new engine built on NVIDIA Nemotron Retriever embedding models, combines keyword and semantic search to return the most relevant passages to AI agents while honoring existing file permissions, with general availability for Enterprise Advanced customers planned for early next year. Box's press release claims 20% better search accuracy (Recall@5), 90% fewer tokens and 4x faster answers. Open-weight Nemotron models, starting with Nemotron 3 Ultra, are available in Box AI now. Box also unveiled Box Architect, which designs workflows from a stated goal; Box Mount, which mounts Box folders inside agent sandboxes and works with NVIDIA OpenShell; and agent security controls including MCP Guardrails.

BoxWorks 2026: Box and NVIDIA Unveil Box Context Retrieval, Permission-Aware Retrieval for Enterprise Agents Built on Nemotron Retriever, Plus Box Architect and Box Mount

Key Takeaways

  • Box Context Retrieval uses NVIDIA Nemotron Retriever with hybrid keyword and semantic search, honoring existing file permissions
  • Vendor claims: +20% Recall@5 accuracy, 90% fewer tokens, 4x faster answers; GA for Enterprise Advanced early next year
  • Open-weight Nemotron models, starting with Nemotron 3 Ultra, are available in Box AI now
  • Box Mount puts Box folders inside agent sandboxes and works with the NVIDIA OpenShell secure runtime
  • New agent security controls include MCP Guardrails, classification-based access policies and audit trails
Read full story
Linked Models & Agents:
⚡ Nemotron 3 Ultra⚡ Nemotron Retriever🌐 Box🌐 Nvidia (NIM)

Claude Code Background Subagent Status Lines Now Written by Haiku 5.5: About 99% Cheaper per Update, About 6% More Prompts per Limit

On November 4 ClaudeDevs, Anthropic's official developer account, said the status line that a background subagent in Claude Code refreshes every 30 seconds used to re-read its whole conversation each time, and is now written by Haiku 5.5 from short notes, so each update costs about 99% less. Anthropic says sessions with background subagents used about 5% less of the limit, giving about 6% more prompts on the same limit. It is live for most Pro, Max and Ultra users and everyone on Team and Enterprise, on v2.1.316 or later.

Key Takeaways

  • A background subagent refreshes its status line every 30 seconds, and each refresh used to re-read the subagent's whole conversation
  • Haiku 5.5 now writes the status line from short notes, which Anthropic says makes each update about 99% cheaper
  • The subagent itself keeps its own model; only the status line is written by Haiku 5.5
  • Anthropic says sessions with background subagents used about 5% less of the limit, so the same limit gives about 6% more prompts
  • It is live for most Pro, Max and Ultra users and everyone on Team and Enterprise; update to v2.1.316 or later
Read full story

Google Antigravity v2.29 Brings Remote Agents and a Gemini Live Voice Mode: Agent Sessions Run in a Google-Managed Cloud and Keep Working After You Close Your Laptop, Rolling Out to AI Pro and Ultra

Ivan Leo, who works on developer experience at Google DeepMind, shared the official docs for Antigravity's new Remote Agents feature on X on November 4. Per the docs, Remote Agents run agent sessions and tools in an isolated, Google-managed remote environment, so tasks keep going when you close your laptop or browser or switch between desktop and mobile. Sessions start from the Antigravity App, the Antigravity CLI (1.4.12+, agy --remote-agent) or the web at antigravity.google.com, and remote projects can attach GitHub repositories, Google Drive files and uploads. It is rolling out gradually to Google AI Pro and Ultra subscribers on personal accounts; it is not available on the free plan, AI Plus or business accounts. The official changelog shows this ships in Antigravity v2.29.0 (November 3), which also starts rolling out a voice mode powered by Gemini Live for handing requests to the agent by voice, redesigns the Automations page into Scheduled, Always on and Paused lists, and adds a native Jupyter notebook viewer.

Key Takeaways

  • Remote Agents run in an isolated Google-managed environment with no local machine required; Remote Control instead connects to your own computer or server, and the web sidebar switches between them.
  • Three entry points: a New Remote Project in the Antigravity App, agy --remote-agent in CLI 1.4.12+, or antigravity.google.com in any browser, including mobile.
  • Remote projects can attach GitHub repositories (cloned automatically), Google Drive files and uploads (8 MiB per file, 100 MiB per project, 2 GiB per account).
  • CLI remote sessions default to the always-proceed (turbo) permission preset, so commands run without approval; locally installed MCP servers, plugins and skills are not available remotely yet.
  • Also in v2.29.0 (November 3): a Gemini Live voice mode rolling out gradually, a redesigned Automations page, and native rendering of .ipynb notebooks.
Read full story

Fireworks Forge Launches: Ultra-fast Inference Preview Hits 1,500 Tokens/s, Half-Price Background Mode, Nexus Desktop for Codex and Claude Desktop, Sovereign Private Preview

At its first Forge conference on November 3, open-model inference platform Fireworks launched a batch of products. Ultra-fast, powered by NVIDIA Blackwell, is in public preview at up to 1,500 tokens per second on DeepSeek V4.1 Flash, cutting a 30-turn agent task from 1 minute to 8 seconds. Background Mode runs deferrable work at half price, alongside multi-day prompt caching and higher rate limits. Nexus Desktop brings open-model routing into the Codex app, Claude Desktop and OpenCode, with Pro plans from $8 per month. Fireworks also announced No Eval, serverless LoRA inference, the Fireworks Sovereign private preview and a 60+ partner Frontier Ecosystem.

Fireworks Forge Launches: Ultra-fast Inference Preview Hits 1,500 Tokens/s, Half-Price Background Mode, Nexus Desktop for Codex and Claude Desktop, Sovereign Private Preview

Key Takeaways

  • Ultra-fast public preview: on NVIDIA Blackwell, up to 1,500 tokens per second on DeepSeek V4.1 Flash; in Fireworks' benchmark a 30-turn agent task fell from 1 minute to 8 seconds (Fireworks blog)
  • Cost options: Background Mode runs deferrable work at half price; multi-day prompt caching cuts the cost of resuming long context; higher serverless rate limits and Elastic Burst are generally available
  • Nexus Desktop launches: personalized routing across open and closed models inside the Codex app, Claude Desktop and OpenCode; Pro from $8 per month, Teams from $10 per seat per month
  • Training: No Eval (private preview) turns production traces into task evals; serverless LoRA inference (public preview) starts with GLM 5.3 Flash at per-token pricing with no idle charge; free training on Muse Glimmer 30B through November 30
  • Enterprise: Fireworks Sovereign (private preview) runs the inference engine in a customer's own cloud or data center; Fireworks says it already manages over 25,000 GPUs in customer environments; plus a 60+ partner Frontier Ecosystem
Read full story

Claude renames its Max plans to Max and Ultra and removes the 5-hour limit for verified Ultra accounts

On Oct 30 Anthropic's official @claudeai account announced that Max 5x is now called Max (still $100/month) and Max 20x is now Ultra (still $200/month), with nothing for existing subscribers to do. Verified Ultra accounts also lose the rolling 5-hour usage limit starting that day, beginning with most existing subscribers; newer accounts keep a temporary limit until verified, and weekly limits are unchanged.

Claude renames its Max plans to Max and Ultra and removes the 5-hour limit for verified Ultra accounts

Key Takeaways

  • Prices are unchanged: Max is $100/month, Ultra is $200/month, and Pro is $20 billed monthly (per claude.com/pricing)
  • The pricing page lists Max at 5x Pro usage every 5 hours and every week, and Ultra at 10x Pro weekly usage with no 5-hour limit for verified accounts
  • Both tiers include monthly API credits, $100 on Max and $200 on Ultra, and Fable can use up to half the weekly limit
  • Newer accounts keep a temporary 5-hour limit until verified, which Anthropic says prevents fraud and abuse; users get an email when it is lifted
  • Weekly limits are unchanged; Anthropic has not published the verification criteria or timeline
Read full story
Linked Models & Agents:
⚡ Claude Fable⚡ Claude Opus⚡ Claude Sonnet🤖 Claude Code🌐 Anthropic