AI Coding Live News

First Third-Party Scores for Claude Fable 5.2: Cursor Says It Tops CursorBench at 60% on Max Effort and 56.9% at Default (Fable 5.1: 49.2%); Perplexity Reports a Record 0.851 on WANDR at $14.51 per Task

Within an hour of Anthropic releasing Claude Fable 5.2, Cursor and Perplexity both shipped the model and posted results from their in-house evals. Cursor's official account says Fable 5.2 scores 56.9% on CursorBench at default (High) effort, up from 49.2% for Fable 5.1, and 60% at max effort, the top score on the board. Cursor's chart puts the default setting at about $9.70 average cost per task. Perplexity's official account says Fable 5.2 set a record 0.851 on its WANDR benchmark at $14.51 per task, on the performance-cost Pareto frontier; Gemini 4 Argon scores 0.802 ($7.88), GPT-6 Astra 0.735 and Fable 5.1 0.684. Both are vendor-run evals, not independent public benchmarks.

First Third-Party Scores for Claude Fable 5.2: Cursor Says It Tops CursorBench at 60% on Max Effort and 56.9% at Default (Fable 5.1: 49.2%); Perplexity Reports a Record 0.851 on WANDR at $14.51 per Task

Key Takeaways

  • CursorBench (Cursor's own eval): Fable 5.2 scores 56.9% at default effort vs 49.2% for Fable 5.1, a gain of about 7.7 points; max effort reaches 60%, the top of the board
  • Cost (per Cursor's chart): default High effort averages about $9.70 per task; max effort costs far more, roughly 3x the default in the chart
  • WANDR (Perplexity's own eval): Fable 5.2 hits a record 0.851 at $14.51 per task; Gemini 4 Argon 0.802 / $7.88, GPT-6 Astra 0.735 / $13.34, Fable 5.1 0.684 / $13.16
  • Availability: selectable in Cursor now; in Perplexity Computer for Pro and Max subscribers, and in Search for Max only
  • Caveat: both are vendor-built evals whose task sets and methods are not fully public, so treat them as indicative
Read full story

Perplexity Cuts Agent API Effort-Level Costs and Adds Ultra: Medium Nearly 90% Cheaper; Ultra ~85.9% WANDR

On November 5 Perplexity Developers (@perplexitydevs) said every Agent API effort level now costs less per query with equal or better research quality, and added an ultra tier for broad long-running research. Vendor figures: medium rose from ~55% to ~77% on BrowseComp/DSQA with nearly 90% lower cost; xhigh held ~76.5% WANDR at ~25% of August 2026 cost; ultra runs three parallel researchers plus a consolidator at ~85.9% WANDR and about $21.71/task.

Perplexity Cuts Agent API Effort-Level Costs and Adds Ultra: Medium Nearly 90% Cheaper; Ultra ~85.9% WANDR

Key Takeaways

  • Official (@perplexitydevs + blog): every effort level cheaper with equal/better quality; new ultra
  • Vendor: medium BrowseComp/DSQA ~55%→~77% with nearly 90% lower cost
  • Vendor: xhigh WANDR ~76.5% at ~25% of August 2026 cost
  • ultra: 3 parallel research agents + consolidator; WANDR ~85.9% at ~$21.71/task on Claude Opus 5.5
  • Use effort="ultra" or pin [email protected]; background mode for long runs
Read full story

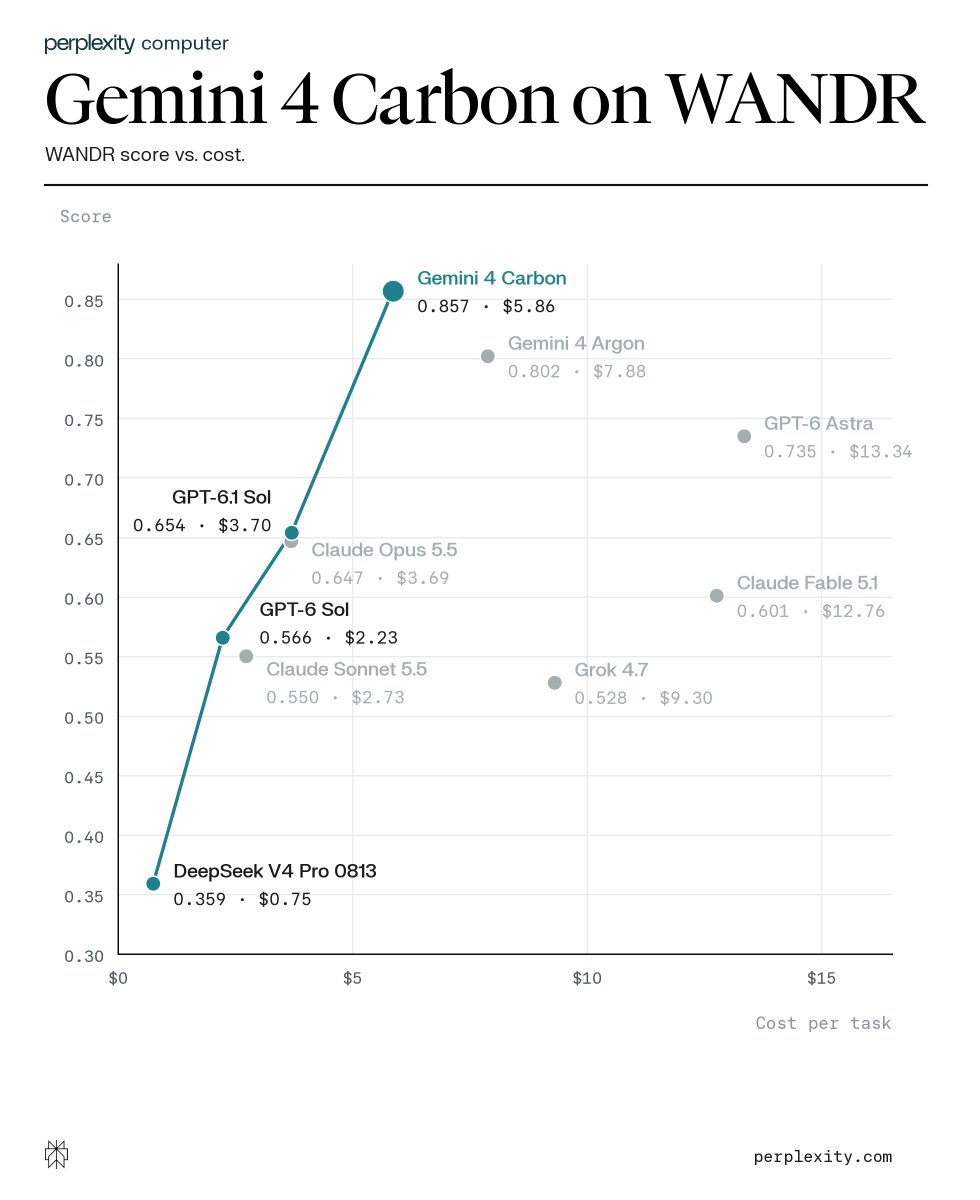
Perplexity CEO shares early Gemini 4 Carbon evals: a record 0.857 on the WANDR deep-research benchmark at $5.86 per task, ahead of Argon and GPT-6 Astra

Perplexity CEO Aravind Srinivas posted early evals of Gemini 4 Carbon on X: it scored a record 0.857 on Perplexity's Wide-And-Deep-Research (WANDR) long-form research benchmark at $5.86 per task, versus 0.802 ($7.88) for Gemini 4 Argon and 0.735 ($13.34) for GPT-6 Astra. He called Carbon the strongest model Perplexity has seen for long-form research and answer quality, and said it will come to all Pro and Max users inside Perplexity Computer once there is enough token capacity.

Perplexity CEO shares early Gemini 4 Carbon evals: a record 0.857 on the WANDR deep-research benchmark at $5.86 per task, ahead of Argon and GPT-6 Astra

Key Takeaways

  • WANDR scores (per Perplexity): Gemini 4 Carbon 0.857, Gemini 4 Argon 0.802, GPT-6 Astra 0.735, GPT-6.1 Sol 0.654, Claude Opus 5.5 0.647, Claude Fable 5.1 0.601
  • Cheaper too: Carbon costs $5.86 per task, below Argon at $7.88 and GPT-6 Astra at $13.34
  • Cost frontier in Perplexity's chart: DeepSeek V4 Pro 0813 (0.359, $0.75), GPT-6 Sol (0.566, $2.23), GPT-6.1 Sol (0.654, $3.70) and Carbon
  • Claude Sonnet 5.5 scored 0.550 ($2.73) and Grok 4.7 scored 0.528 ($9.30)
  • Not live yet: Carbon reaches Perplexity Pro and Max users only once token capacity allows, and Google still limits early access to cyber defenders in its Fairwind program
Read full story

Perplexity: GPT-6 Astra tops WANDR at 0.682, beating Fable 5.1 at lower cost

Perplexity says GPT-6 Astra scored 0.682 on WANDR at about $11.98 per task—the highest of any model they tested. Versus Claude Fable 5.1 it is ~13.5% higher score at ~6.1% lower cost; versus Opus 5 it is ~27.0% higher score at only ~3.3% higher cost.

Key Takeaways

  • WANDR: Astra at 0.682 and ~$11.98/task, highest among models Perplexity tested.
  • Vs Fable 5.1: ~13.5% higher score at ~6.1% lower cost.
  • Vs Opus 5: ~27.0% higher score at only ~3.3% higher cost.
Read full story
ADSponsored

Perplexity Computer adds Claude Fable 5.1: WANDR 0.601 lead at ~$12.76/task

Perplexity (@perplexity_ai) says Claude Fable 5.1 is now in Perplexity Computer for Pro and Max subscribers. In its August WANDR eval it ranked first at 0.601 and about $12.76 per task—roughly 21% higher score and 37% lower cost than Fable 5.

Key Takeaways

  • Fable 5.1 is live in Perplexity Computer for Pro/Max.
  • August WANDR: 0.601 score at ~$12.76/task, ranked first.
  • About +21% score and -37% cost vs Fable 5.
Read full story