
AI Coding Live News

Microsoft makes MAI-Image-2.6 and MAI-Image-2.6-Flash generally available in Foundry as MAI-Image-2.7-Preview reaches #3 in Image Edit Arena

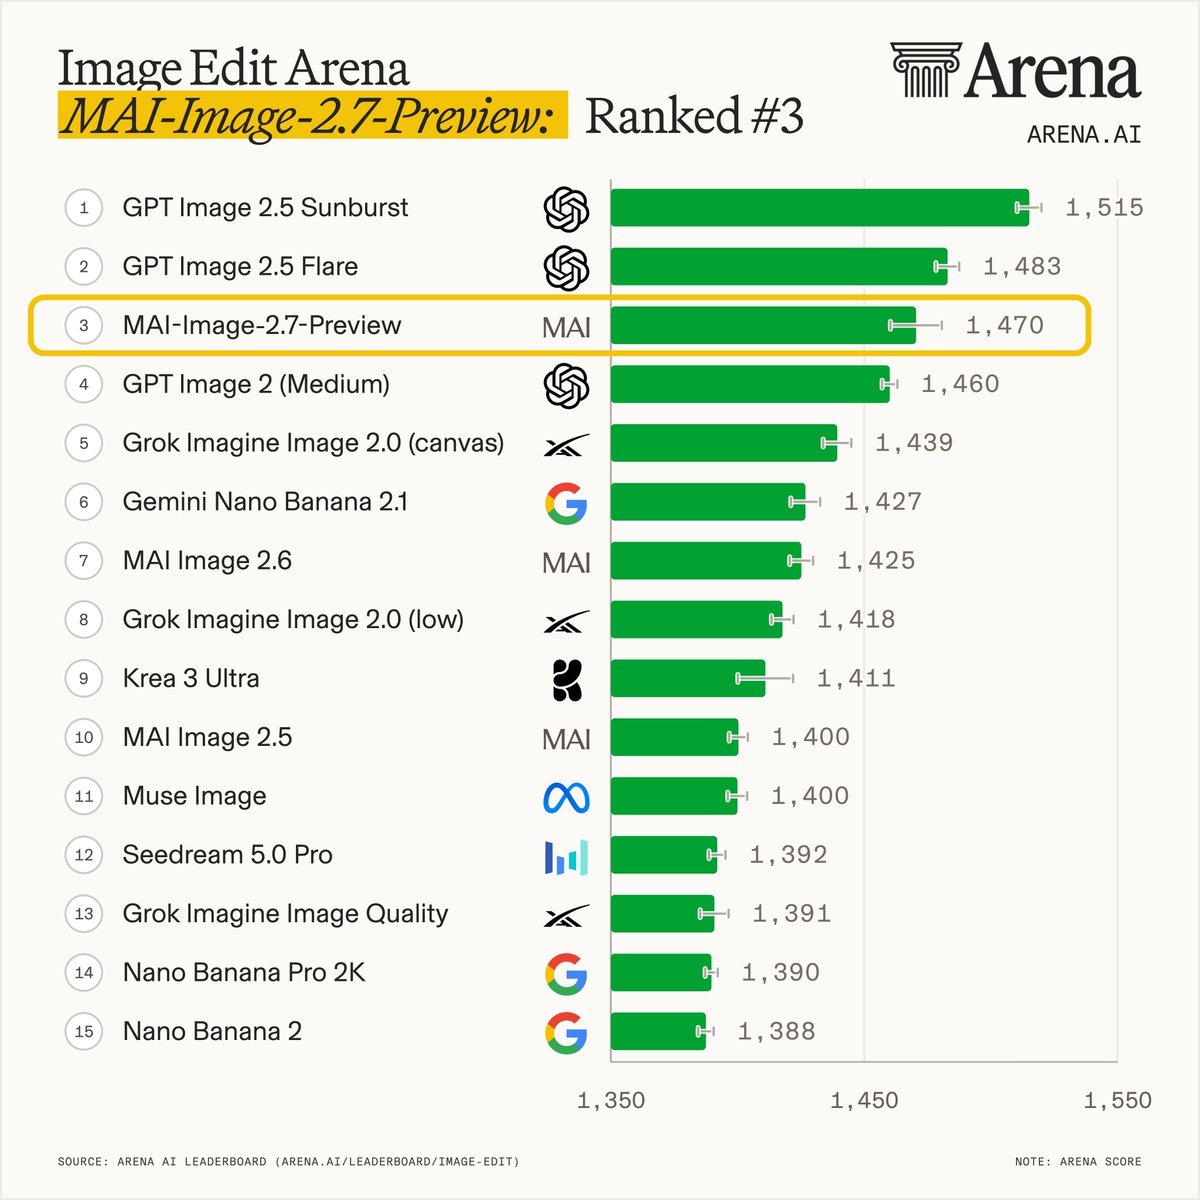
Microsoft AI announced on Oct 27 that MAI-Image-2.6 and MAI-Image-2.6-Flash are generally available in Microsoft Foundry, with multi-reference editing from up to five images, Bing web grounding, output up to 1.5K and published per-token pricing. The same day its next image editing model, MAI-Image-2.7-Preview, reached #3 overall in Arena's Image Edit leaderboard at 1470 points, 45 points above 2.6; for now it is available only for editing in MAI Playground.
Microsoft makes MAI-Image-2.6 and MAI-Image-2.6-Flash generally available in Foundry as MAI-Image-2.7-Preview reaches #3 in Image Edit Arena

Key Takeaways

  • MAI-Image-2.6 and MAI-Image-2.6-Flash are generally available in Microsoft Foundry, and Microsoft says 2.6 is coming soon to Adobe Firefly
  • Official pricing: 2.6 costs $5 text input, $8 image input and $38 image output per 1M tokens; Flash costs $1.75, $2.50 and $19
  • 2.6 supports multi-reference editing with up to five images, Bing web grounding, dynamic aspect ratios and output up to 1.5K
  • Per Arena, MAI-Image-2.7-Preview is #3 overall in Image Edit Arena at 1470 points, 45 points above 2.6 (#7), putting Microsoft AI #2 among labs
  • Per Artificial Analysis, 2.7-Preview is #2 on AA-Image-Editing v2.1 and beats 2.6 on all 7 editing actions, ranking #1 on 4 of them
Read full story
Linked Models & Agents:
⚡ MAI-Image-2.6⚡ MAI-Image-2.6-Flash⚡ MAI-Image-2.7-Preview🌐 Microsoft🌐 Microsoft AI

MiniMax Releases M3.1 Flash: 1M Context Window, $0.15/M Token Pricing, Surging +106 Points in WebDev Code Arena

MiniMax officially announced M3.1 Flash, its next-generation lightweight frontier model (previously dominating leaderboards as the secret model Space Bunny across 200T+ tokens). Featuring a native 1M context window, flat-rate API pricing of $0.15 / $0.60 per 1M input/output tokens ($0.015 cache reads), and 3x faster inference at 1/3 the cost of M3. It surged +106 points to 1588 on LMSYS Code Arena: WebDev (#12 among open models), with full weights set for open release on October 23.

MiniMax Releases M3.1 Flash: 1M Context Window, $0.15/M Token Pricing, Surging +106 Points in WebDev Code Arena

Key Takeaways

  • MiniMax officially launched M3.1 Flash, unveiling that it was the mystery model Space Bunny evaluated across 200T+ tokens
  • Features native 1M context with flat-rate API pricing of $0.15/$0.60 per 1M tokens ($0.015 cache reads), offering 3x speed at 1/3 cost of M3
  • Debuts on LMSYS Code Arena: WebDev at 1588 Elo (+106 pts over M3), ranking #12 among open models with major leaps in Gaming (+179) and Reference Design (+155)
  • Artificial Analysis benchmark confirms Intelligence Index of 42 and HLE of 48% at half the token consumption of rivals; weights release on Oct 23
Read full story
Linked Models & Agents:

Ollama Cloud fully rolls out DeepSeek-V4.1-Flash: US/EU hosting, zero retention, DeepSeek-matched pricing

Ollama said DeepSeek-V4.1-Flash is fully live on Ollama Cloud—hosted in the US and Europe, zero data retention (no logging/training on prompts or responses), per-token pricing matching the DeepSeek API including off-peak. Available via Pro/Max/Team or pay-as-you-go free accounts; Ollama claims it is more capable, faster, and more cost-effective than prior DeepSeek models including V4-Pro.

Key Takeaways

  • DeepSeek-V4.1-Flash fully available on Ollama Cloud.
  • US/EU hosting; zero retention—no logging or training on prompts/responses.
  • Per-token pricing matches DeepSeek API (incl. off-peak); Pro/Max/Team or pay-as-you-go.
Read full story
Linked Models & Agents:

Google DeepMind: Gemini agentic video understanding cuts tokens up to 88%

Google DeepMind launched agentic video understanding on Gemini 3.7 Flash, 3.6 Flash, and 3.5 Flash-Lite. Models dynamically search frames, audio, and transcripts instead of ingesting video at a fixed FPS. Official claims include up to 88% fewer tokens, about 66% lower analysis cost, and up to about 7% better accuracy. It is live via the Gemini API, Google AI Studio, and the Gemini Enterprise Agent Platform at standard token pricing with no extra feature fee.

Key Takeaways

  • Available on Gemini 3.7 Flash / 3.6 Flash / 3.5 Flash-Lite; enable with processing=agentic.
  • Long-form video: up to 88% fewer tokens, ~66% lower cost, up to ~7% accuracy gain.
  • Supports uploads and YouTube; unlocks sub-second retrieval, anomaly detection, and precise counting.
Read full story
ADSponsored

Ollama switches Pro, Max, and Team to transparent per-token pricing

Ollama’s Pro, Max, and Team plans now bill at published per-token rates against a monthly credit pool: $20/month with $60 of usage, $100 with $300, and $500 Team with $1,000 shared across unlimited users. The plans plug into Claude Code, Codex, and a first-party API, with no service fees and no 5-hour or weekly caps—when the pool runs out, traffic continues at the same token price. Inference stays on dedicated US/EU compute (Singapore for a limited Qwen set) with zero retention and no training on prompts. Existing subscribers can keep the old plan; new signups land on the token model because GPU-time billing became hard to forecast as open models scaled to sizes such as Kimi K3.

Key Takeaways

  • Pro/Max/Team are $20/$100/$500 with $60/$300/$1,000 monthly token credits; Team shares one pool with unlimited seats.
  • No service fees or 5-hour/weekly caps; unused work continues at the published token rate and works with Claude Code and Codex.
  • US/EU dedicated inference with zero retention; existing plans stay until you upgrade, new signups use token pricing.
Read full story
Linked Models & Agents: