

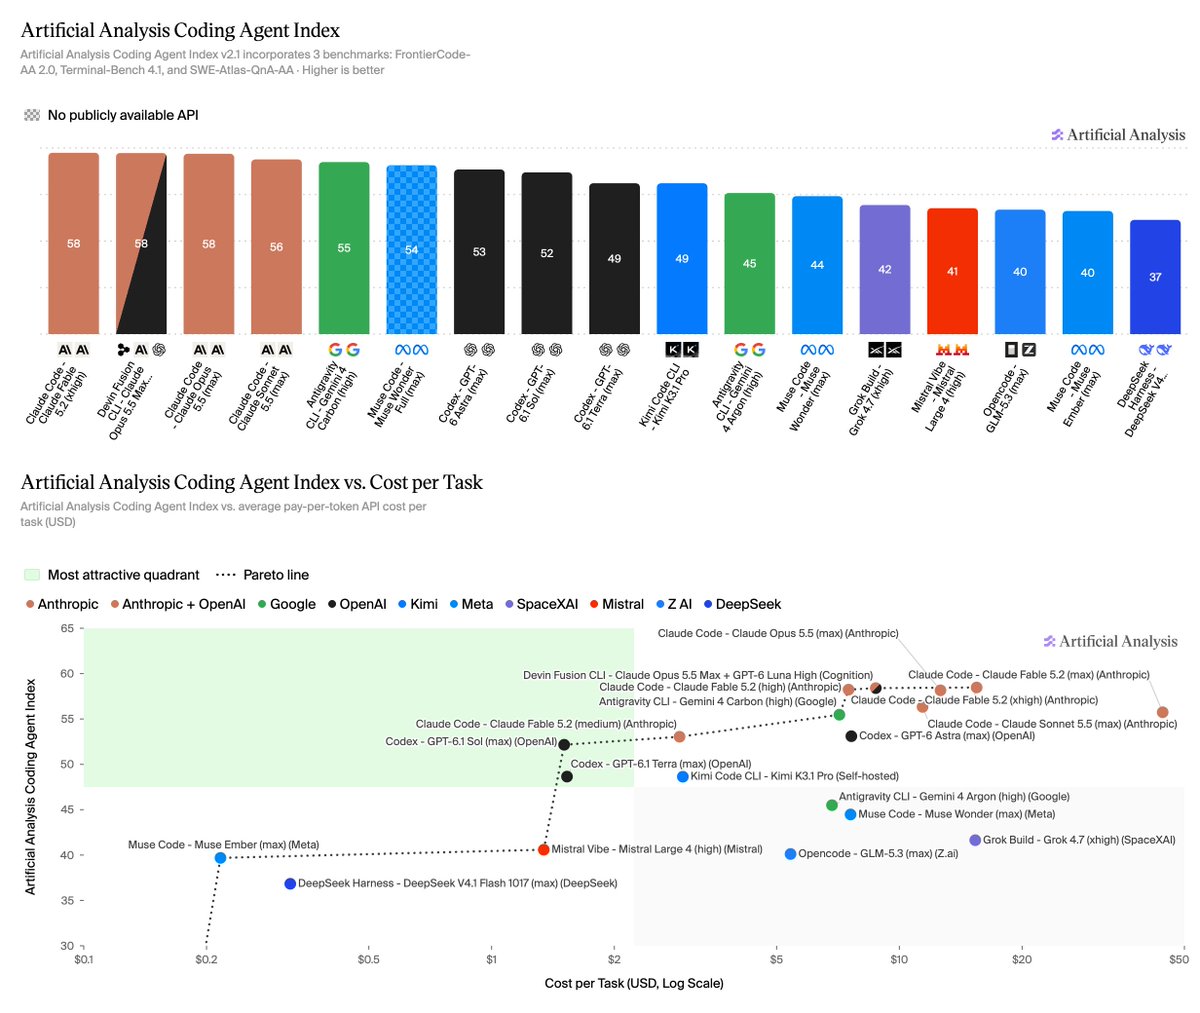
On November 14 Artificial Analysis released Coding Agent Index v2.1, swapping FrontierCode 1.1 for its implementation of Cognition's FrontierCode 2.0 (132 real-world tasks graded on whether a maintainer would merge the change), upgrading Terminal-Bench from 4.0 to 4.1 and keeping SWE-Atlas-QnA-AA. Claude Fable 5.2 (xhigh and high, in Claude Code) and Claude Opus 5.5 (max) share the lead at 58. Because FrontierCode 2.0 is harder, scores fall 5 points on average; only Codex with GPT-6.1 Terra (max) held within 1 point of its prior score.
Key Takeaways
- ✓v2.1 is made of FrontierCode-AA 2.0 (132 real-world coding tasks graded on whether a maintainer would merge the change), Terminal-Bench 4.1 (the same 66 tasks with updated verifiers for reliability and resistance to reward hacking) and SWE-Atlas-QnA-AA
- ✓Tied for first at 58: Claude Code with Claude Fable 5.2 (58 at both xhigh and high), Claude Code with Claude Opus 5.5 (max), and Devin Fusion CLI (Opus 5.5 max + GPT-6 Luna High); next come Claude Sonnet 5.5 (max) at 56 and Antigravity CLI with Gemini 4 Carbon (high) at 55
- ✓All 23 configurations tested on both versions score lower on FrontierCode-AA 2.0 than on v1.1, with the mean falling from 45% to 29%; Claude Code with Fable 5.2 leads at 49%. On Terminal-Bench 4.1 every score moves less than 3 points, and Kimi Code CLI with Kimi K3.1 Pro leads at 68%
- ✓Cost varies about 30x: among configurations scoring 48+, Codex with GPT-6.1 Sol (max, 52) costs $1.51 per task and Claude Code with Fable 5.2 (max, 56) costs $44.22; Fable 5.2 costs $2.89, $7.51 and $15.47 at medium, high and xhigh
- ✓Claude Code and Devin Fusion CLI fall back to another model after a safety refusal: a fallback model completed about 9% of attempts for Devin Fusion CLI and Opus 5.5 (max), 6% for Fable 5.2 (xhigh) and 5% for Sonnet 5.5
Key Decision Metrics at a Glance
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Background
A coding agent leaderboard is only as useful as its tasks are realistic. The Artificial Analysis Coding Agent Index measures model and harness pairs such as Claude Code, Codex and Devin Fusion CLI; v2.0 replaced DeepSWE with FrontierCode 1.1 in October. With Cognition's harder, merge-focused FrontierCode 2.0 now out, the old task set no longer separated the top configurations, which led to v2.1.
Architecture highlights
v2.1 has three parts. FrontierCode-AA 2.0 is AA's implementation of Cognition's FrontierCode 2.0, with 132 real-world tasks graded on whether a repository maintainer would merge the agent's change. Terminal-Bench 4.1 keeps the 66 tasks of 4.0 but updates their verifiers to cut false results and reward hacking. SWE-Atlas-QnA-AA stays unchanged.
Benchmarks and data
Per AA's posts, Claude Fable 5.2 and Claude Opus 5.5 tie for first at 58 with different strengths: Fable 5.2 (xhigh) is 5 points higher on FrontierCode (49% vs 44%), while Opus 5.5 (max) is 4 points higher on SWE-Atlas (66% vs 62%). The new FrontierCode drops the mean of 23 configurations from 45% to 29% and the index by 5 points on average; Codex with GPT-6.1 Terra (max) is the only configuration that did not fall. Kimi Code CLI with Kimi K3.1 Pro leads Terminal-Bench 4.1 at 68%.
Developer quick start
Look past the headline score: Fable 5.2 already hits the top score at high (58, $7.51 per task), while max scores 56 at $44.22 because more attempts hit time limits; on a budget, Codex with GPT-6.1 Sol scores 52 at $1.51. Harnesses such as Claude Code fall back to another model after a safety refusal, so up to about 9% of attempts were not completed by the named model. Full results and methodology are on the AA site.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.