
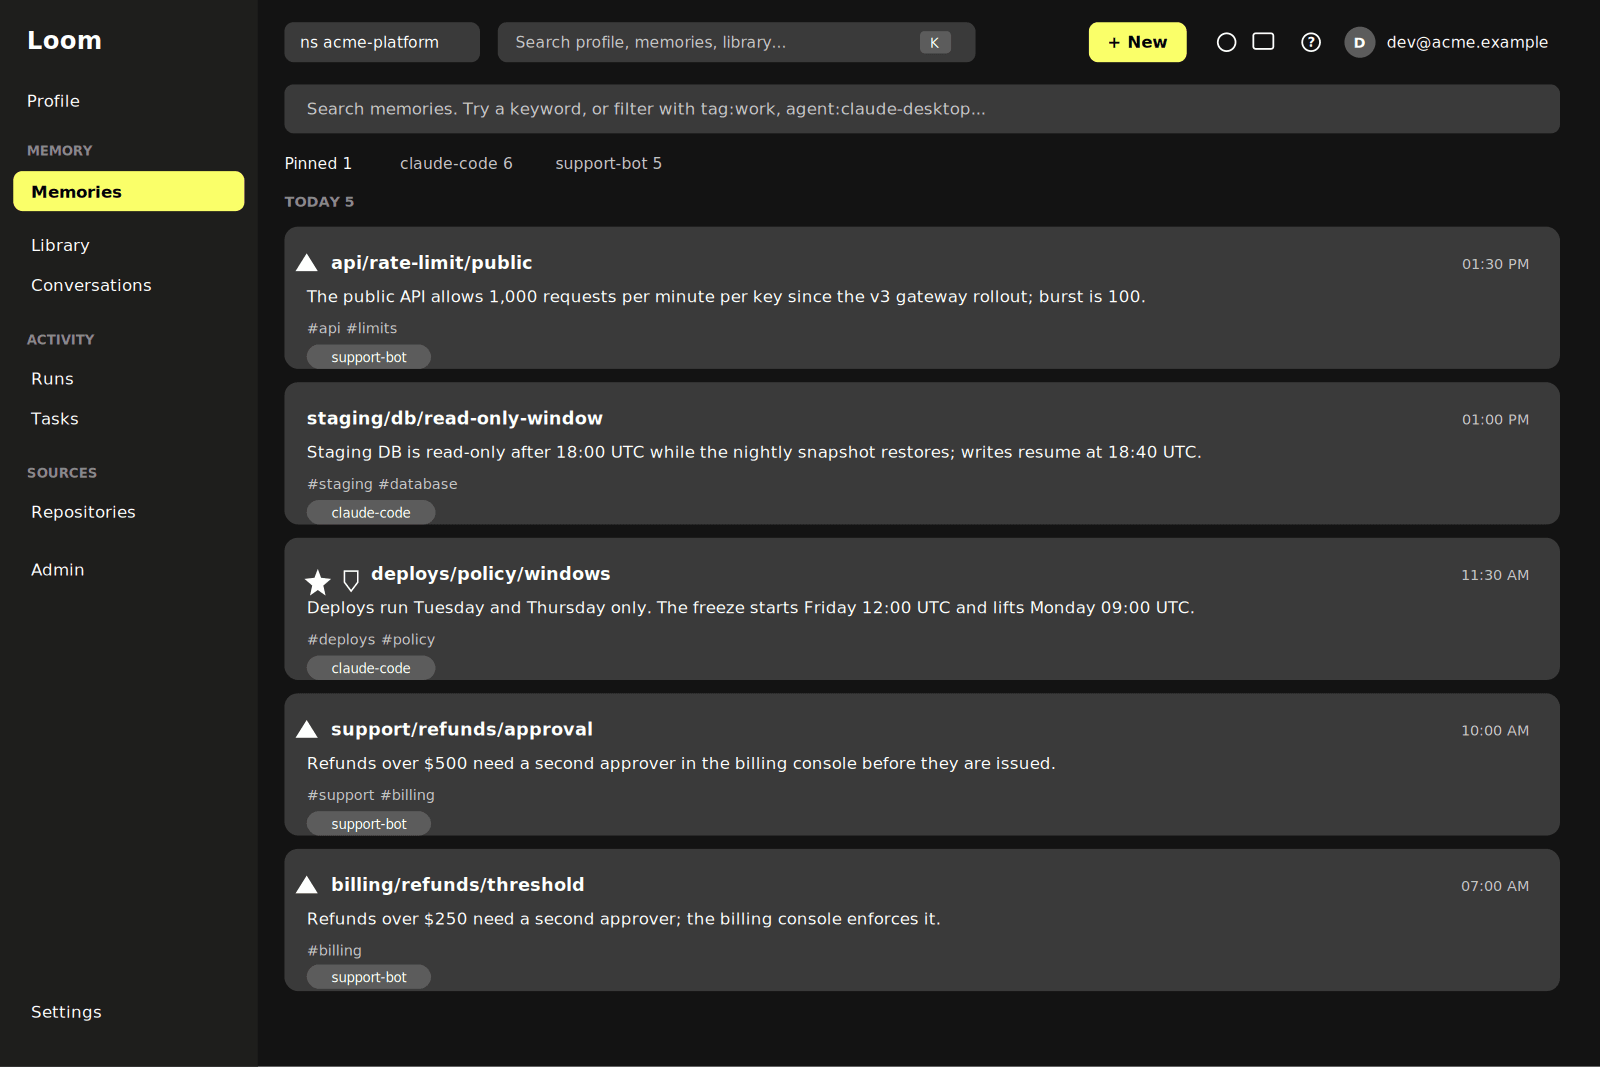
ClickHouse released Loom, an open-source (Apache-2.0) agent memory system that keeps memories, a code index and run logs in one ClickHouse database, links memories to code, and flags memories that may be stale when code changes. It supports MCP, an HTTP API and Python/TS SDKs, with Claude Code and Codex plugins. In ClickHouse tests, the mean code-QA score rose from 0.78 to 0.84.
Key Takeaways
- ✓Code QA (24 questions x 3 runs): mean score 0.78 to 0.84, average cost per question $0.212 to $0.17 (vendor figures, blog)
- ✓File finding (36 questions x 10 runs): accuracy 91.4% to 96.4%
- ✓LongMemEval-S, 100 questions: retrieved memories 94% vs full history in the prompt 90%, with about 90% fewer tokens; memory.ask scores 96.6% on the full 500 (vendor figures)
- ✓Memory and code index share one database: renames are followed, rewritten code gets the memory flagged for review, nothing is rewritten automatically
- ✓Apache-2.0, needs ClickHouse 26.5+ (26.8+ recommended), starts with a one-line Docker install script
Key Decision Metrics at a Glance
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Background
Coding agents start almost every session from zero. ClickHouse's autonomous contributor GroeneAI has worked on PRs since March and had more than 3,000 merged by October, yet it kept relearning context. The team ran two leading memory tools for three months and found they remembered the agent's notes but could not see the code itself; with 92,000+ files and 318,000 commits in the ClickHouse repo, memories went stale easily.
Architecture highlights
Per the official blog, Loom keeps facts, embeddings, a full-text index, the code call graph, task state and a cost/audit trail in one ClickHouse database. Search runs vector, BM25 keyword, long-chunk and entity-graph legs at once and fuses them, telling the agent it does not know when similarity is too weak. Facts are versioned so you can query a past date; memories are linked to functions, follow renames, and get flagged for review when code is rewritten. Teams can share one-way, N-way, or promote personal notes to shared namespaces.
Benchmarks and data
Vendor figures: code-QA mean score 0.78 to 0.84 with cost per question $0.212 to $0.17; file-finding accuracy 91.4% to 96.4%; LongMemEval-S (100 questions) 94% vs 90% with about 90% fewer tokens, a gap ClickHouse says is not statistically significant on its own.
Developer quick start
With Docker installed, run the official install.sh and open localhost:7777 to set model and embedding keys. The Claude Code and Codex plugins connect once the repo is indexed; Cursor connects over MCP. The index tracks the pushed branch, so uncommitted changes do not show up.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.