Liquid AI Releases d1.2 and d1.2-ultra Omnimodal Decision Models With Audio Input and Five New Tasks; d1.2-ultra Tops the Artificial Analysis Decision Index v2.1 at 75
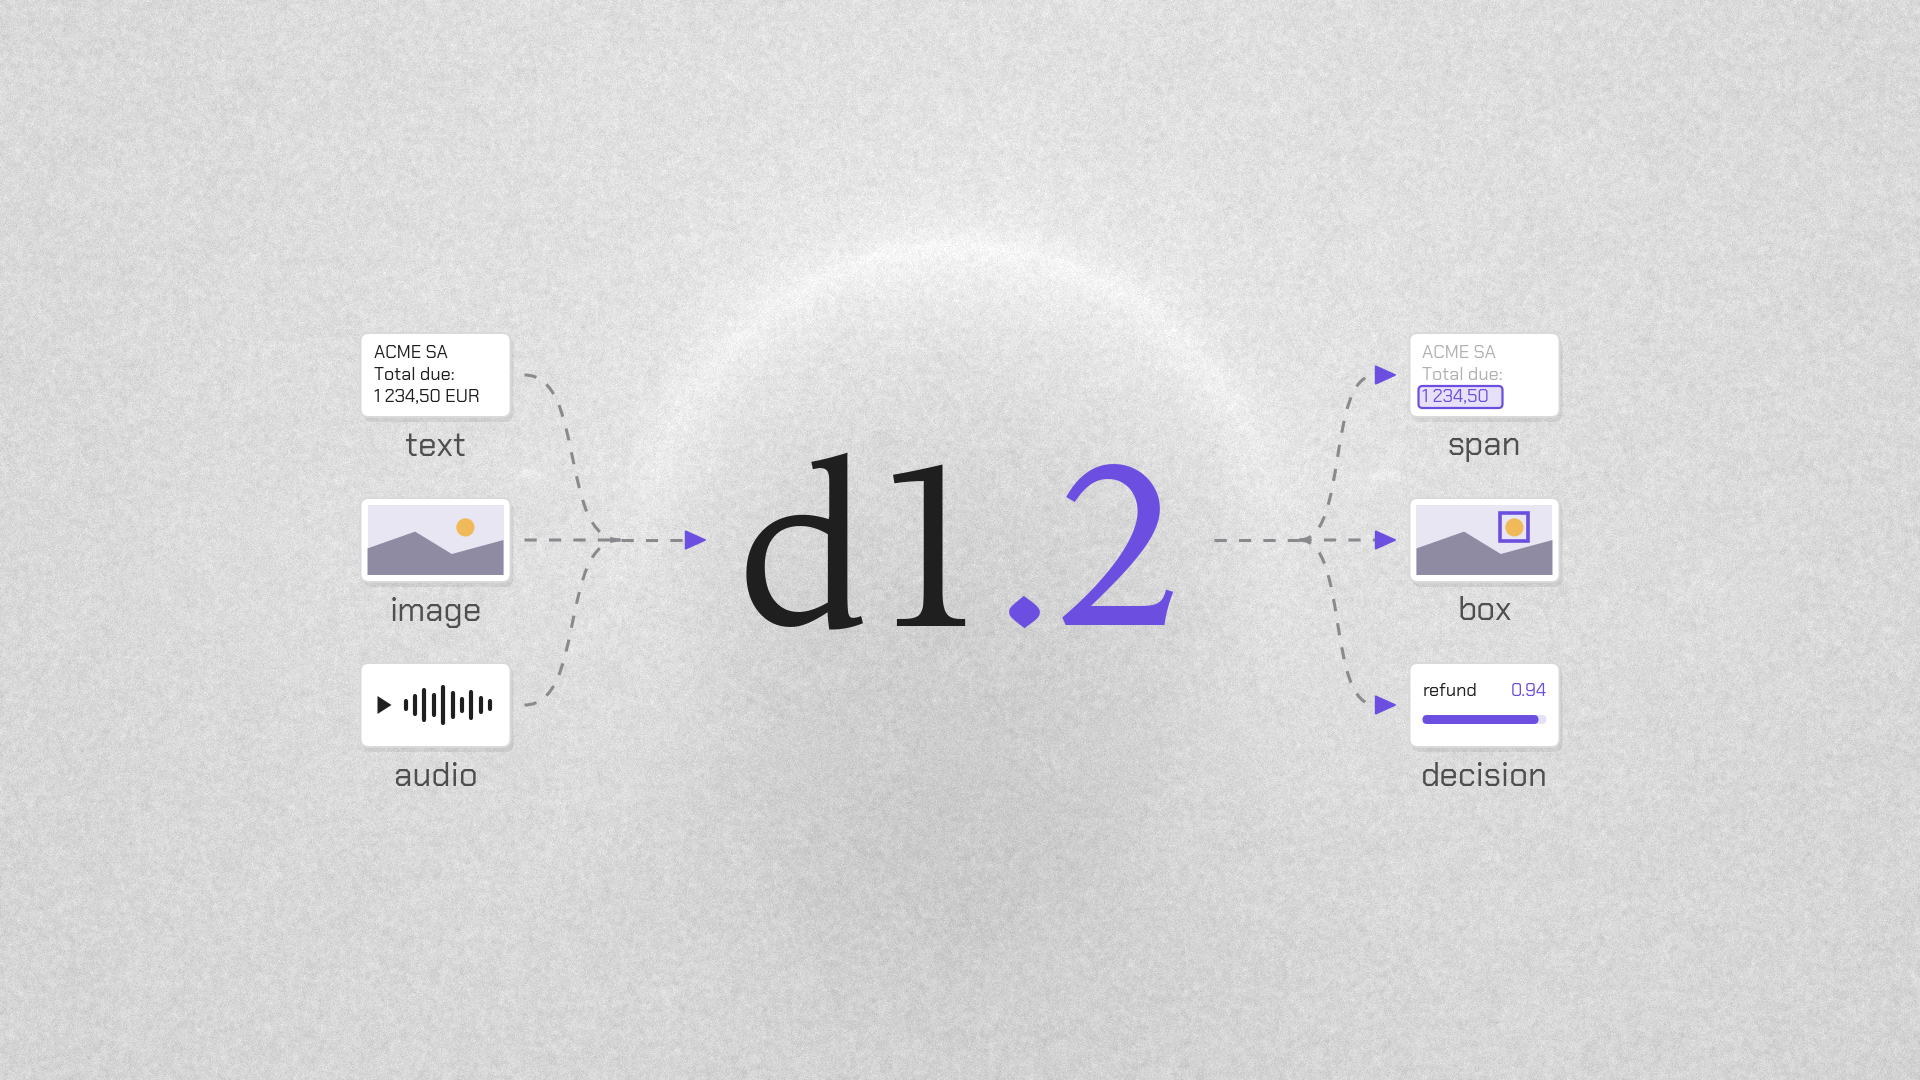
Liquid AI released d1.2 and d1.2-ultra, new versions of its decision models that take text, images and audio and add five new tasks: reading a value, extracting spans, locating objects in images, estimating counts and multi-select choices. d1.2-ultra scores 75 on the Artificial Analysis Decision Index v2.1, first place and two points ahead of the previous best decision model. Both are live on the Liquid API and bill input tokens only, at $0.02 per million for d1.2 and $0.042 for d1.2-ultra, the same price as the previous generation.
Key Takeaways
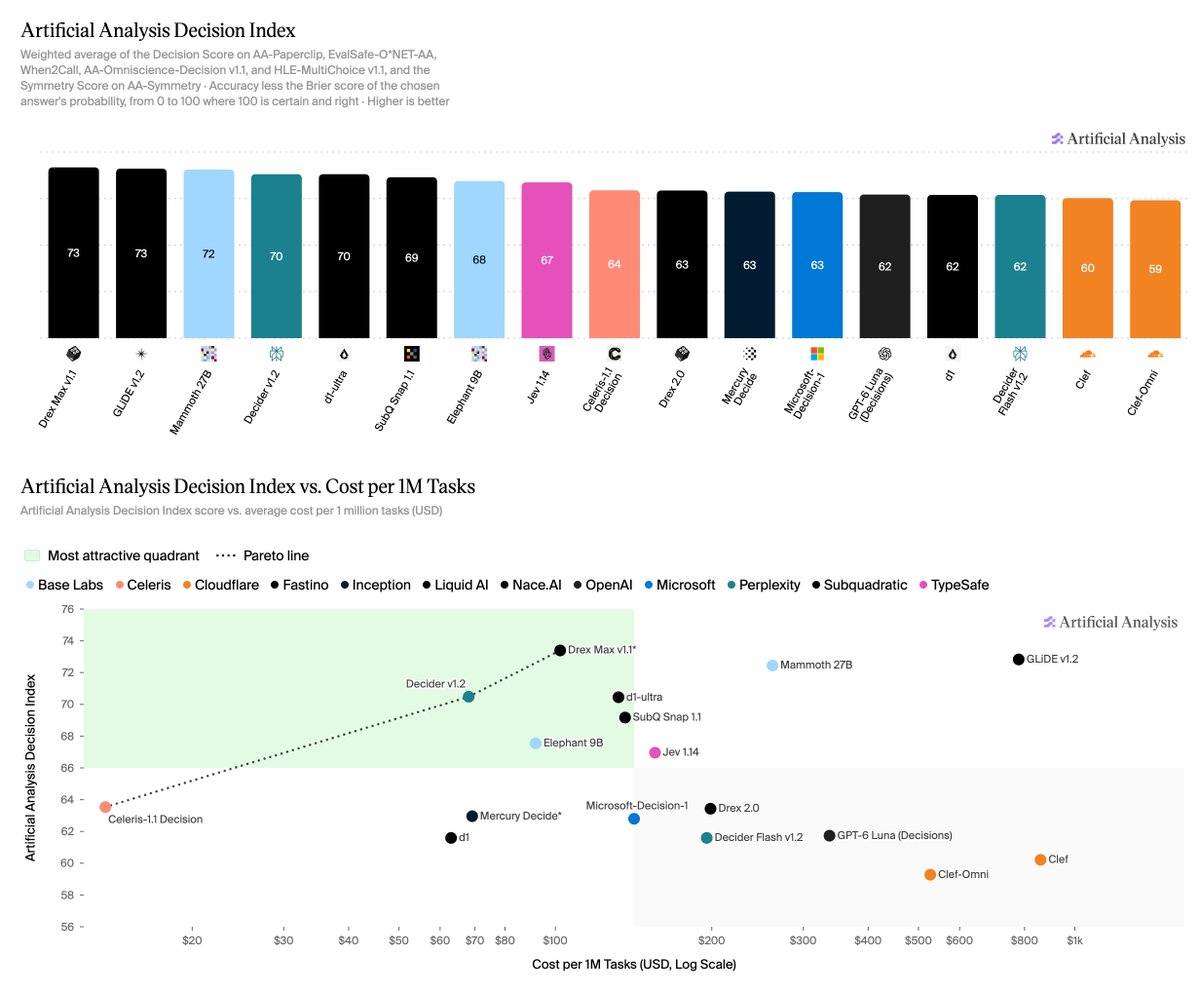
- d1.2-ultra scores 75 on the Artificial Analysis Decision Index v2.1 (six benchmarks that also score answer probabilities), first among decision models; Liquid says no model scores higher than d1.2 for less money
- Five new tasks: read a text, number or date value (answering "not found" when absent), find every span of a kind, box one or all objects in an image, estimate a count with a range, and multi-select with per-option probabilities
- Audio input is new: you can ask about a recording (which language is spoken, whether a siren is in the background), and the question itself can be spoken
- Input-only billing with no output token charges: $0.02 per million input tokens for d1.2 and $0.042 for d1.2-ultra; images cost 1.5 tokens per 32x32 patch, about 1,536 tokens for 1024x1024
- Liquid-reported calibration error is 0.8 for d1.2-ultra and 1.2 for d1.2, versus 2.7 for Jev 1.14 and 3.7 for Perplexity Decider v1.3; new-task accuracy comes from Liquid internal test sets, not public benchmarks
Linked Models & Agents: