
Liquid AI released d1.2 and d1.2-ultra, new versions of its decision models that take text, images and audio and add five new tasks: reading a value, extracting spans, locating objects in images, estimating counts and multi-select choices. d1.2-ultra scores 75 on the Artificial Analysis Decision Index v2.1, first place and two points ahead of the previous best decision model. Both are live on the Liquid API and bill input tokens only, at $0.02 per million for d1.2 and $0.042 for d1.2-ultra, the same price as the previous generation.
Key Takeaways
- ✓d1.2-ultra scores 75 on the Artificial Analysis Decision Index v2.1 (six benchmarks that also score answer probabilities), first among decision models; Liquid says no model scores higher than d1.2 for less money
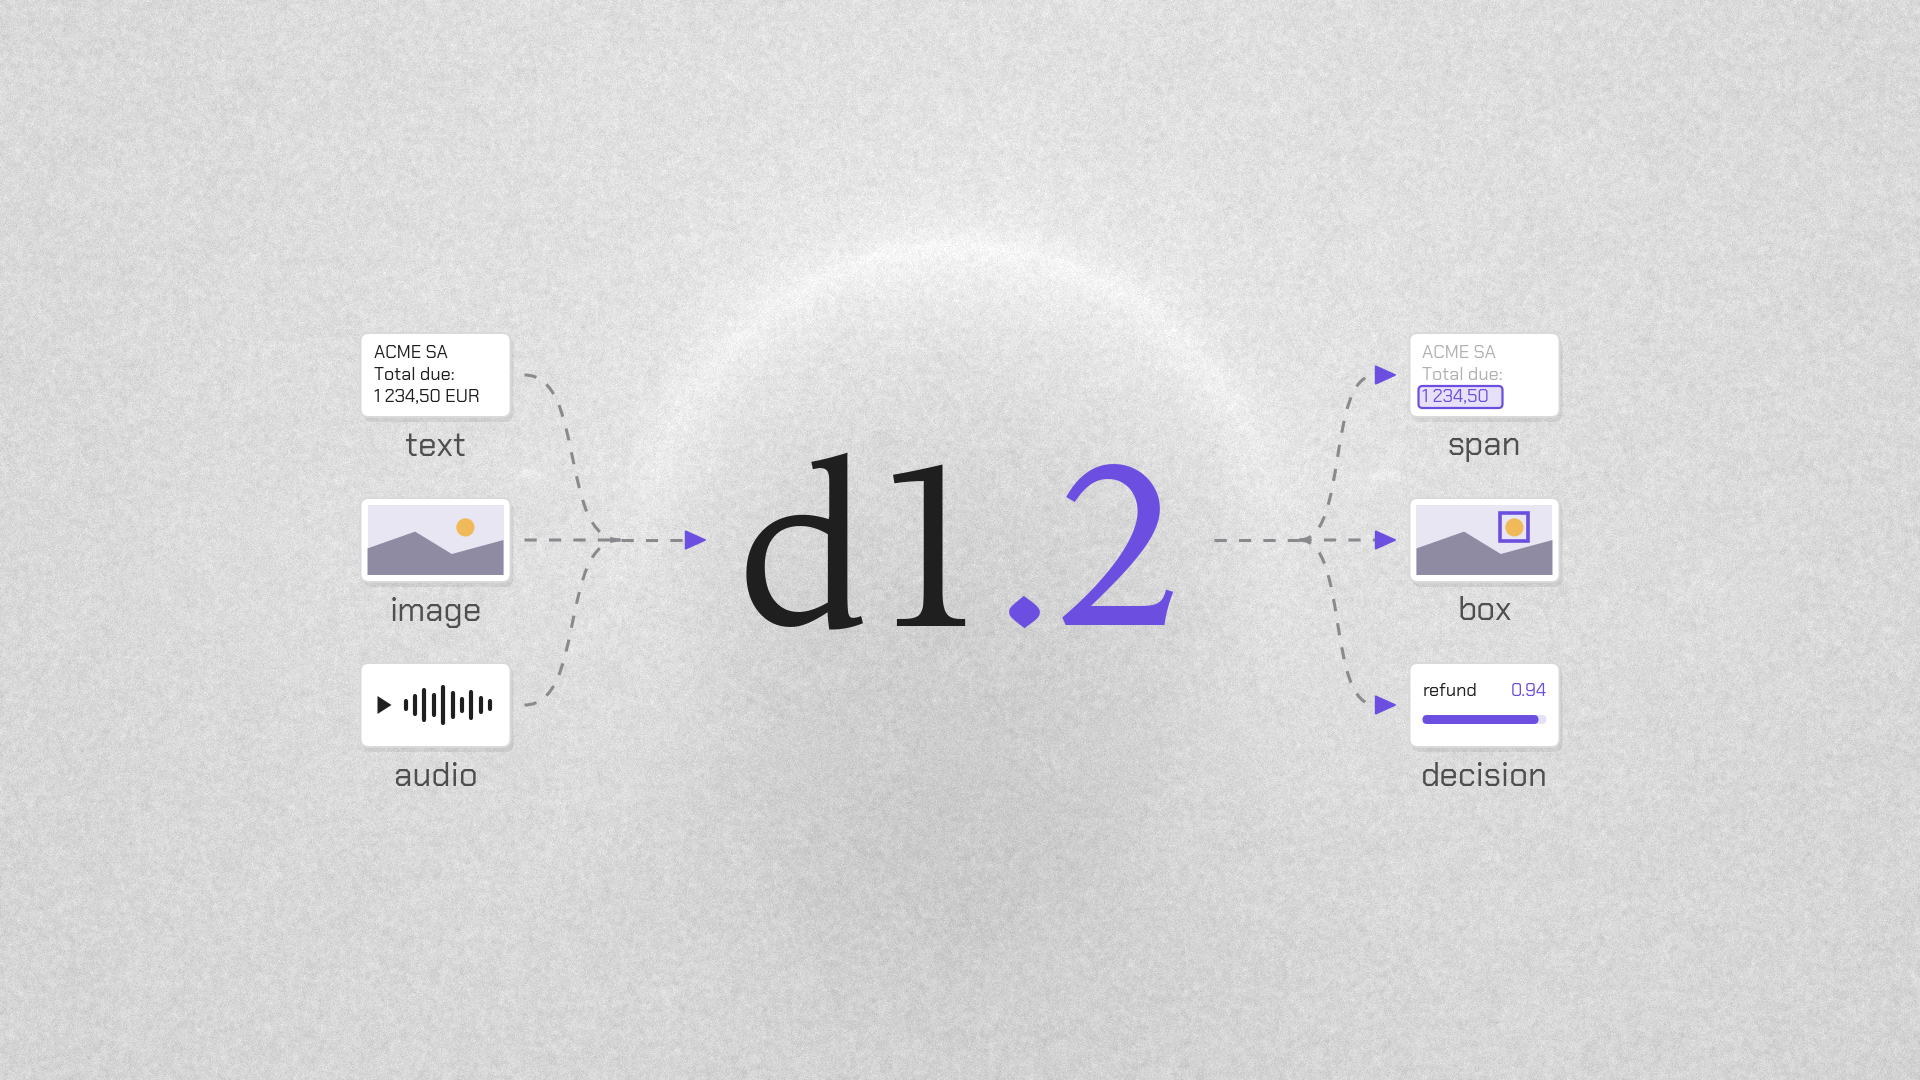
- ✓Five new tasks: read a text, number or date value (answering "not found" when absent), find every span of a kind, box one or all objects in an image, estimate a count with a range, and multi-select with per-option probabilities
- ✓Audio input is new: you can ask about a recording (which language is spoken, whether a siren is in the background), and the question itself can be spoken
- ✓Input-only billing with no output token charges: $0.02 per million input tokens for d1.2 and $0.042 for d1.2-ultra; images cost 1.5 tokens per 32x32 patch, about 1,536 tokens for 1024x1024
- ✓Liquid-reported calibration error is 0.8 for d1.2-ultra and 1.2 for d1.2, versus 2.7 for Jev 1.14 and 3.7 for Perplexity Decider v1.3; new-task accuracy comes from Liquid internal test sets, not public benchmarks
Key Decision Metrics at a Glance
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Background
Decision models do not write long text; they answer structured questions about an input and return probabilities, which suits invoice processing, moderation and ticket routing where you set a threshold and send low-confidence cases to humans. Liquid AI, Perplexity, Sarvam and others have shipped such models this year, and Artificial Analysis runs a dedicated Decision Index. Liquid AI announced d1.2 and d1.2-ultra on X and its blog, adding audio input plus extraction and localization tasks.
How it works
Both models take text, images and audio. Five new tasks: read a value (returning the value and the characters it came from, or "not found"), find every span of a kind (such as personal data with positions), box one or all objects in an image, estimate a count with a range, and multi-select with per-option probabilities. The endpoint and request format are unchanged; the model names are d1.2-ultra and d1.2.
Numbers that matter
On the third-party Artificial Analysis Decision Index v2.1, d1.2-ultra scores 75, first place and two points ahead of the previous best decision model. Liquid reports calibration error of 0.8 for d1.2-ultra and 1.2 for d1.2, versus 2.7 for Jev 1.14 and 3.7 for Perplexity Decider v1.3. New-task accuracy figures (such as 98%/96% on receipt value reading) come from Liquid internal test sets, with no public benchmark yet.
What it means for developers
Create an API key at console.liquid.ai and call the models with input-only billing: $0.02 per million input tokens for d1.2 and $0.042 for d1.2-ultra, the same as the previous generation; text and images are billed once per request, and each extra question adds only its own text. Liquid says OpenRouter and Vercel support is coming. Teams doing receipt extraction, PII detection or image checks should test "not found" behavior and probability thresholds on their own samples first.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.