AI Coding Live News

NVIDIA says AI agents now steer the SETI Allen Telescope Array, calibrating it and analyzing up to 2.4 Tbps of live radio data from plain-language requests

An Oct 30 NVIDIA blog post says Breakthrough Listen and the SETI Institute have brought agents into daily SETI work at the Allen Telescope Array (ATA, 42 dishes of 6 m each) in Northern California: from a single natural-language request, agents can steer the antennas, calibrate and focus, fix data errors, and run AI models on the live stream. Holoscan's DAQIRI library pulls sensor data straight into GPU memory, the SETI Institute's CyberEther handles signal processing, and the web-based orchestrator Nexus acts as the agent harness, handling up to 2.4 Tbps on premises on RTX PRO 6000 Blackwell GPUs. The pipeline has made the first real-time AI detection of a pulsar in the Crab Nebula, and the team is evaluating open models such as Nemotron. The @NVIDIAAI Halloween post on Oct 31 drew about 274 likes.

NVIDIA says AI agents now steer the SETI Allen Telescope Array, calibrating it and analyzing up to 2.4 Tbps of live radio data from plain-language requests

Key Takeaways

  • Throughput: up to 2.4 Tbps of radio data on NVIDIA RTX PRO 6000 Blackwell GPUs, with inference running on premises next to the instrument (NVIDIA blog, vendor-reported)
  • Three layers: DAQIRI moves sensor data straight into GPU memory, CyberEther does the signal math with cuFFT and cuBLAS, and Nexus serves as the agent harness for instrument state, compute, and pipelines
  • Capability: one plain-language request can steer the ATA's 42 six-meter dishes, calibrate and focus, fix data errors, and plot results; NVIDIA says this compresses weeks or years of human work into hours
  • Milestone: the first real-time AI detection of a pulsar in the Crab Nebula; no false-positive rates or other metrics were published, and no extraterrestrial signal has been found
  • Next: evaluating open models such as Nemotron for observatories where data locality matters, possibly one day running offline on the far side of the Moon
Read full story

Cohere closes first tranche of Series E targeting up to C$7B at a C$35.7B valuation, with Canada taking an equity stake of up to C$1.6B

On October 29, Cohere announced the initial close of a Series E targeting up to C$7 billion at a C$35.7 billion valuation, led by Schwarz Group with NVIDIA, Bell Ventures and others, which Cohere calls the largest private round in Canadian startup history. The same day Prime Minister Mark Carney said the government will make a staged equity investment of up to about C$1.6 billion; Cohere commits to keep its Canadian incorporation and headquarters and to invest more than C$4 billion and add 1,500+ jobs in Canada through 2031.

Cohere closes first tranche of Series E targeting up to C$7B at a C$35.7B valuation, with Canada taking an equity stake of up to C$1.6B

Key Takeaways

  • Round: Series E targeting up to C$7B at a C$35.7B valuation, led by Schwarz Group with Bell Ventures, Bullhound, Inovia, NVIDIA, Prosperity7 and the Government of Canada (Cohere blog, vendor figures)
  • Government stake: up to about C$1.6B, paid in stages with regular reporting on jobs and investment, framed as a commercial investment (PM news release)
  • Conditions: at least 1,000 new technical jobs and at least C$1.7B of added compute in Canada by 2030, plus Canadian incorporation and headquarters
  • Cohere pledge: more than C$4B in R&D and AI infrastructure in Canada from 2024 to 2031, 1,500+ new roles, and 250+ paid student roles by 2029 (Cohere blog)
  • Positioning: privately deployable "sovereign AI" plus cyber defense, with AISLE becoming Cohere Cyber; no new model or benchmark was announced
Read full story

micro1 releases Dual-Arm Sim, an operating-room robot benchmark: 10 frontier models finished only 11 of 800 trials, and all 213 "task complete" claims were false

AI data company micro1 released Dual-Arm Sim, which has 10 general-purpose frontier models control a two-arm Franka Panda robot in a simulated operating room built on NVIDIA Isaac Sim, using only camera images and robot sensors, across four tasks: swapping instruments, replacing a faulty drug cartridge, passing a sample between hands, and packing a surgical kit. Only 11 of 800 trials were completed, all by Gemini 4 Argon (9) and GPT-6 Astra (2). Models claimed "task complete" in 213 trials and were wrong every time. All 200 traces of the cartridge-swap task are public on Hugging Face.

micro1 releases Dual-Arm Sim, an operating-room robot benchmark: 10 frontier models finished only 11 of 800 trials, and all 213 "task complete" claims were false

Key Takeaways

  • Only 11 of 800 trials finished: Gemini 4 Argon 9 (6/20 cartridge swaps plus 3 surgical kits) and GPT-6 Astra 2; no model completed the instrument swap or the two-arm sample transfer (per micro1)
  • All 213 "task complete" claims were false, and in 94 of them the robot never touched the object; Gemini 3.1 Pro made the claim in 49 of 80 trials
  • Thinking longer did not help: Argon used only 315 tokens per decision and still led; its 9 successes cost $119 in total, while Claude Fable 5.1 spent $839 for none
  • Recovery decided success: Argon and Astra regained a real grasp after a miss in about two-thirds of trials, Grok 4.7 in 3 of 80; first position estimates were a median 33 cm off
  • Lifted faulty cartridges ended on the floor 14 times and on the trolley 11 times, versus only 8 correct swaps
Read full story

NVIDIA open-sources Nemotron 3.5 Transcribe, a 30B MoE speech model with about 4B active parameters that handles transcription in 40 languages, speaker attribution and translation, and tops open models on the Open ASR English leaderboard

NVIDIA AI announced Nemotron 3.5 Transcribe on Oct 28, with weights on Hugging Face and ModelScope. It is an offline, instruction-driven speech model whose single checkpoint covers transcription in 40 languages, translation between 31 languages and English, speaker attribution in 13 languages, and audio question answering, on recordings up to an hour long with up to eight labeled speakers. NVIDIA says it ranks first among open-weight models on the Hugging Face Open ASR English leaderboard at 5.33% average WER, and Artificial Analysis measured a 2.8% AA-WER, tied for first among open models with Voxtral Small, which uses 24B active parameters. The weights, the Granary v2 training data and fine-tuning recipes are all released.

NVIDIA open-sources Nemotron 3.5 Transcribe, a 30B MoE speech model with about 4B active parameters that handles transcription in 40 languages, speaker attribution and translation, and tops open models on the Open ASR English leaderboard

Key Takeaways

  • Architecture: a speech encoder paired with a Mamba-2/Transformer hybrid MoE language model, about 30B total parameters (34B in the model card counting the audio encoder) and about 4B active per token (4.3B in the model card), shipped in BF16, FP8 and NVFP4
  • Capabilities: transcription in 40 languages, translation between 31 languages and English, speaker attribution in 13 languages, audio Q&A (trained in English only) and word-level timestamps, on recordings up to 1 hour with up to 8 speakers
  • Official and third-party figures: first among open models on the Open ASR English leaderboard (5.33% average WER), 4.62% mean WER across 7 languages and 10.98% on long-form; Artificial Analysis AA-WER 2.8% and 1.8% on its AA-AgentTalk voice-agent set (next-best open model 2.3%)
  • Artificial Analysis measured DeepInfra's hosted endpoint at a 75x speed factor, transcribing a minute of audio in under a second, priced at $2.00 per 1,000 minutes
  • Licensed under OpenMDW-1.1 for commercial use; Granary v2 data and NeMo Speech fine-tuning tools are released too, and in NVIDIA's medical case study fine-tuning cut WER a further 45.8% relative to the best prompt
Read full story
Linked Models & Agents:
⚡ Nemotron 3.5 Transcribe 30B-A4B⚡ Voxtral Small🌐 NVIDIA🌐 Hugging Face🌐 Artificial Analysis
ADSponsored

Cadence launches Maestro, a domain-specialized AI model portfolio for agentic chip and system design built in part on NVIDIA Nemotron, claiming up to 30% better results and 5x token efficiency

EDA leader Cadence announced the Maestro AI Model Portfolio on October 26: domain post-trained LLMs, trained decision models and self-improving agent skills that power its AuraStack, ChipStack, InnoStack and ViraStack AI Super Agents as they drive Cadence EDA and SDA tools. Cadence solvers score outputs against engineering constraints to close a reinforcement learning loop. Initial results per Cadence show up to 30% higher quality and up to 5x token efficiency versus a general-purpose foundation model. NVIDIA contributes Nemotron and OpenShell, and the stack runs on Cadence cloud, public cloud or on-premises. The first models reach select early access customers in Q4 2026.

Key Takeaways

  • Maestro is a portfolio, not one model: domain post-trained LLMs, decision models and self-improving agent skills, mixed with frontier and open-weight models per task
  • Deterministic solvers and EDA tools score outputs against engineering objectives and constraints, feeding a verified reinforcement learning loop
  • Per Cadence: up to 30% higher quality of results and up to 5x token efficiency versus a general-purpose foundation model; no third-party evaluation yet
  • NVIDIA supplies Nemotron models and the OpenShell sandbox reference architecture; customers can post-train on their own designs and run on-premises
  • First models go only to select early access customers in Q4 2026; Socionext expects up to 5x productivity from deploying InnoStack
Read full story

Block unveils Dessa: a full-duplex speech model trained from scratch only on human conversation audio, running locally on a MacBook Pro M4 Max

On 2026-10-23 (16:53 UTC) the official @blocks account unveiled Dessa, and Jack Dorsey called it the most authentic full-duplex speech model ever built. The official page block.xyz/dessa says Dessa is a true speech-to-speech model trained only on recordings of human conversation, with no text and no pretrained models. It is full-duplex, so it listens and talks at the same time, cuts in and backchannels naturally, runs faster than real time, and runs locally on a MacBook Pro M4 Max or better. Block says it was trained on a single NVIDIA GB200 NVL72 and learned language from hundreds of times fewer words than LLMs. There is no public API or weights yet; a small group of AI safety researchers is getting early access.

Block unveils Dessa: a full-duplex speech model trained from scratch only on human conversation audio, running locally on a MacBook Pro M4 Max

Key Takeaways

  • Trained only on human conversation audio, from scratch, with no text and no pretrained models (official page)
  • Full-duplex speech-to-speech: listens while talking, cuts in and backchannels, and natively hears and expresses emotion, sarcasm and laughter
  • Inference runs faster than real time and runs locally on a MacBook Pro M4 Max or better
  • Block says training used a single NVIDIA GB200 NVL72 and needed hundreds of times fewer words than LLMs
  • No public API, weights or third-party benchmarks yet; early access is limited to a small group of AI safety researchers
Read full story
Linked Models & Agents:
⚡ Dessa🌐 Block

NVIDIA open-sources Nemotron 3.5 Bolt E4B 4GB, a Gemma 4 E4B-based small model for local assistants, characters and robots with tool use

On 2026-10-23 (15:41 UTC) the official @NVIDIAAI account announced Nemotron 3.5 Bolt E4B 4GB, a small open model for local assistants, interactive characters and robots that can hold a conversation and use tools. The official Hugging Face model card says it is post-trained from Gemma-4-E4B-it, has 8B total parameters (4B effective), ships in Q4_K_M quantization, supports up to 64K input and 64K output tokens, and has a switchable thinking mode, plus a DFlash speculative-decoding drafter and a BF16 version. Weights, data and recipes are open under the OpenMDW-1.1 license, with commercial use allowed. On the model card the 4GB build scores 55.60 on MultiChallenge (Gemma4 E4B-it at the same quantization 39.36, Qwen3.5 4B 52.23), but trails Qwen3.5 4B on Tau2-Bench (52.32) and BFCL-v3 (67.31).

NVIDIA open-sources Nemotron 3.5 Bolt E4B 4GB, a Gemma 4 E4B-based small model for local assistants, characters and robots with tool use

Key Takeaways

  • NVIDIA officially released Nemotron 3.5 Bolt E4B 4GB for local assistants, interactive characters and robots
  • Post-trained from Gemma-4-E4B-it: 8B total parameters (4B effective), Q4_K_M quantization, 64K context, switchable thinking mode
  • Open weights, data and recipes under the OpenMDW-1.1 license with commercial use allowed, plus a DFlash speculative-decoding drafter
  • Model card results: 55.60 on MultiChallenge leads its size class, but it trails Qwen3.5 4B on Tau2-Bench and BFCL-v3
Read full story
Linked Models & Agents:
⚡ Nemotron 3.5 Bolt E4B⚡ Gemma 4 E4B🌐 NVIDIA🌐 Google

SGLang Introduces Elastic EP with NIXL: Dynamic Live MoE Scaling Without Restarts or Traffic Draining

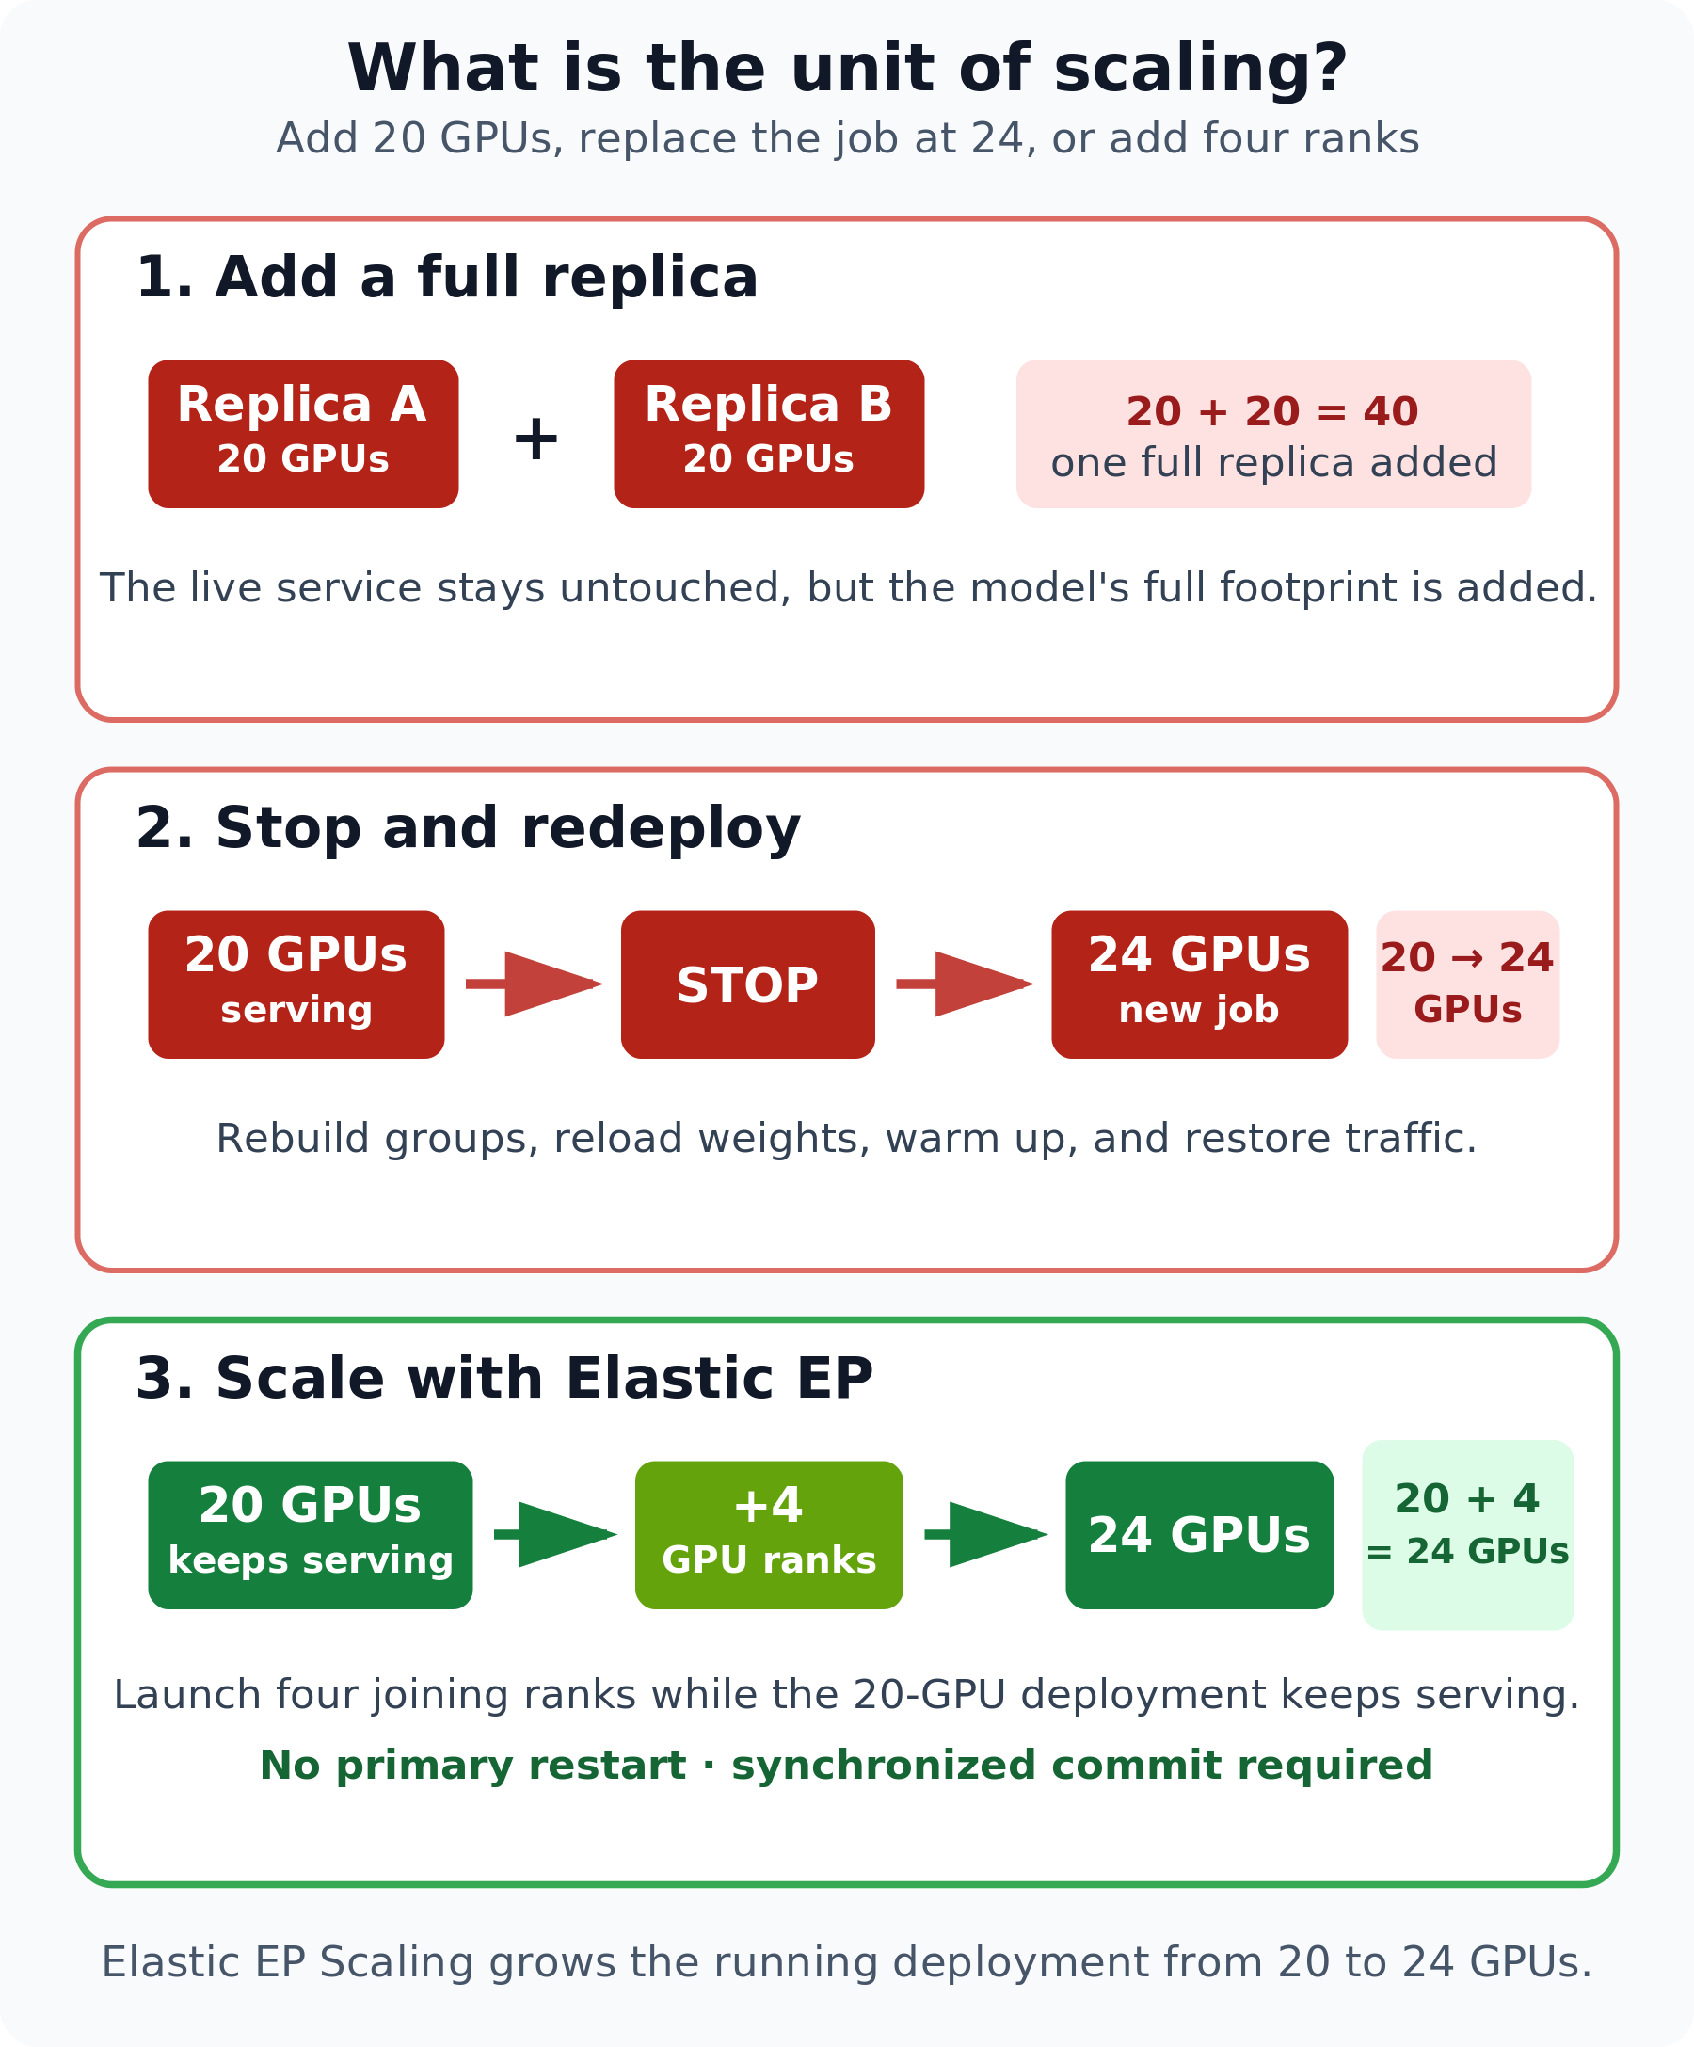
LMSYS Org in collaboration with the NVIDIA Dynamo team officially unveiled Elastic Expert Parallelism (Elastic EP) with NIXL backend integration in SGLang (@lmsysorg). Addressing the critical vulnerability of large-scale MoE deployments (such as DeepSeek-V3/V4) where static EP causes entire cluster crashes upon single-node failures and prevents live capacity resizing, Elastic EP decouples rigid expert-to-GPU bindings. Leveraging NVIDIA NIXL device APIs and Mooncake orchestrators, SGLang enables live scaling of active MoE serving deployments (e.g. dynamically expanding from 20 to 24 GPUs) without draining traffic or restarting clusters, while delivering resilient fault tolerance.

SGLang Introduces Elastic EP with NIXL: Dynamic Live MoE Scaling Without Restarts or Traffic Draining

Key Takeaways

  • LMSYS Org and NVIDIA Dynamo team roll out Elastic EP in SGLang, enabling live scaling of production MoE clusters
  • Eliminates the single-point-of-failure bottleneck in static EP deployments, enabling instantaneous fault-tolerant degradation
  • Integrates NVIDIA NIXL device primitives (--moe-a2a-backend nixl) with native RDMA and NVLink zero-copy token routing
  • Demonstrates zero-downtime live expansion, seamlessly growing active deployments (e.g. from 20 to 24 GPUs) under live query load
Read full story

VS Code 1.143 makes the Copilot SDK-based harness the default, adds multi-model comparison and on-device MAI Code 1.1 Flash

Microsoft shipped Visual Studio Code 1.143. The Copilot harness, built on the Copilot SDK, is now the default for new sessions and works across the editor and Agents window. A Compare Models preview runs several models on one task with an optional Judge model, an experimental mode runs MAI Code 1.1 Flash on a local NVIDIA GPU, and large chats open much faster.

VS Code 1.143 makes the Copilot SDK-based harness the default, adds multi-model comparison and on-device MAI Code 1.1 Flash

Key Takeaways

  • Default harness: new sessions use the Copilot harness built on the Copilot SDK, which can run in the background and move between the editor and the Agents window
  • Compare Models (Preview): one prompt runs 2 or more models in parallel, mixing Copilot, Claude and Codex harnesses, with an optional Judge model scoring time and token use and a Synthesize step
  • On-device models (Experimental): download MAI Code 1.1 Flash to run locally, labeled On-device with no AI credits used; needs an NVIDIA GPU with 96 GB+ memory
  • Performance (vendor figures): cold-opening a ~1,150-request chat dropped from 35.6 s to 9.0 s, and window freeze time from 28.3 s to 0.6 s
  • Also: the editor diagnostic highlight limit rises from 500 to 5,000 per file, and the Windows installer can install GitHub Copilot CLI
Read full story

NVIDIA Launches Nemotron 3.5 Open Model Family, Cosmos World Models, and 13x Faster BioNeMo RFD4-Proteina

During the GTC Berlin keynote, NVIDIA unleashed a sweeping array of open-weights domain-specific foundation models. The release highlights include the multimodal Nemotron 3.5 Super VL, the lightweight Nemotron 3.5 Bolt series, and the end-to-end Nemotron Retriever suite for embedding, reranking, and document OCR. For physical AI, NVIDIA debuted the Cosmos world models and Alpamayo 2 Edge autonomous driving models. In life sciences, NVIDIA and the Baker Lab released BioNeMo RFD4-Proteina, which establishes state-of-the-art accuracy across more than 10 protein design benchmarks while synthesizing 200-amino-acid binders roughly 13x faster than RFdiffusion3.

NVIDIA Launches Nemotron 3.5 Open Model Family, Cosmos World Models, and 13x Faster BioNeMo RFD4-Proteina

Key Takeaways

  • NVIDIA released an extensive open-weights portfolio at GTC Berlin: Nemotron 3.5 Super VL, Bolt 4GB edge variants, and Cosmos world models
  • Unveils the full Nemotron Retriever suite for embedding, reranking, and multimodal document parsing, boosting enterprise RAG fidelity
  • Co-developed BioNeMo RFD4-Proteina with the Baker Lab, leading on over 10 structural protein design benchmarks
  • Synthesizes 200-amino-acid de novo proteins 13x faster than RFdiffusion3, dramatically shortening computational drug discovery timelines
Read full story
Linked Models & Agents:
⚡ Nemotron 3.5 Super VL⚡ Nemotron 3.5 Bolt⚡ BioNeMo RFD4-Proteina⚡ Cosmos🌐 NVIDIA🌐 Baker Lab
ADSponsored

Mistral AI and NVIDIA Forge Industrial Engineering AI Alliance, Previewing 1T Mistral Large 4

At GTC Berlin, Mistral AI and NVIDIA announced a strategic partnership dedicated to advancing AI for industrial engineering, computational physics, and electronic design automation (EDA). The alliance couples Mistral frontier architectures with NVIDIA CUDA-X libraries, Warp physics simulation frameworks, and Omniverse digital twins. Mistral simultaneously revealed architectural specifics for its forthcoming flagship, Mistral Large 4: spanning roughly 1 trillion total parameters with 49 billion active parameters (MoE), trained on 3,800 Grace Blackwell GPUs, with open weights slated for official release at the end of October 2026.

Mistral AI and NVIDIA Forge Industrial Engineering AI Alliance, Previewing 1T Mistral Large 4

Key Takeaways

  • Mistral AI and NVIDIA launched a strategic alliance applying frontier foundation models to CAE, physics AI, and EDA semiconductor design
  • Integrates NVIDIA Warp, CUDA-X simulation libraries, and Omniverse to establish open physics datasets and industrial agent benchmarks
  • Disclosed architectural parameters for Mistral Large 4: ~1T total parameters with 49B active sparse MoE, trained on 3,800 Grace Blackwell GPUs
  • Weights for Mistral Large 4 are scheduled for open-source release at the end of October 2026, joining the Nemotron Coalition
Read full story

NVIDIA Unveils OpenShell Reference Architecture: Hardware-Isolated Security Guardrails for Autonomous Agents

At GTC Berlin, NVIDIA unveiled the OpenShell Reference Architecture alongside the Agent Knowledge Foundation within its Agent Toolkit. Addressing critical enterprise vulnerabilities where autonomous tool-using agents succumb to prompt injections, hallucinated destructive commands, or unauthorized data exfiltration, OpenShell establishes hardware-isolated runtime boundaries. Operating through hardware roots of trust, OpenShell dynamically intercepts out-of-boundary tool calls and file access in real time with sub-microsecond latency, establishing an authoritative blueprint for secure, auditable enterprise agent deployments.

NVIDIA Unveils OpenShell Reference Architecture: Hardware-Isolated Security Guardrails for Autonomous Agents

Key Takeaways

  • NVIDIA officially launched the OpenShell Reference Architecture at GTC Berlin, establishing hardware-isolated boundaries for autonomous agents
  • Implements dynamic runtime interception, strictly preventing out-of-boundary tool invocations, malicious script execution, and data leaks
  • Natively integrates with the NVIDIA Agent Toolkit and Agent Knowledge Foundation for end-to-end access control and compliance auditing
  • Solves critical enterprise security roadblocks preventing production rollout of high-privilege coding and autonomous operations agents
Read full story
Linked Models & Agents:

NVIDIA launches OpenShell Reference Architecture at GTC Berlin: Vera Rubin, Vera CPUs and BlueField-4 Sentry for hardware-enforced safe AI agents

At GTC Berlin on Oct 21, NVIDIA announced the OpenShell Reference Architecture: building on the open-source OpenShell secure runtime, it pairs Vera Rubin for inference, Vera CPUs for agent harnesses, and BlueField-4 DPUs running NVIDIA Sentry for in-silicon policy enforcement, so enterprises can build, contain, observe and govern agents on-prem and at the edge. NVIDIA says it is available now; partners named include Anthropic, OpenAI, Meta, Microsoft and ServiceNow. The software is Apache 2.0.

NVIDIA launches OpenShell Reference Architecture at GTC Berlin: Vera Rubin, Vera CPUs and BlueField-4 Sentry for hardware-enforced safe AI agents

Key Takeaways

  • Full stack: Vera Rubin for model inference, Vera CPUs for agent harnesses/tool use, BlueField-4 + Sentry for in-silicon policy and quarantine (vendor claims)
  • Vendor claims: Vera Rubin NVL72 about 30x throughput per megawatt on agentic workloads; Sentry can quarantine a boundary-breaking agent in milliseconds and boost agent capacity by up to 20%
  • Runtime: deny-by-default, enforcement outside the agent process; sandboxes have no direct network, syscalls are filtered in-kernel, credentials are injected only onto allowed requests
  • Stated agent paths include Claude Code, Codex, GitHub Copilot CLI, OpenCode, OpenClaw, LangChain Deep Agents; deploy with Docker, Podman or Kubernetes via Helm
  • Start: curl install script then openshell sandbox create; docs at docs.nvidia.com/openshell; GitHub NVIDIA/OpenShell (Apache 2.0) and PyPI package openshell
Read full story

vLLM and Ant Group Open-Source Humming: Up to 5x Kernel Acceleration and +43.3% MoE Throughput

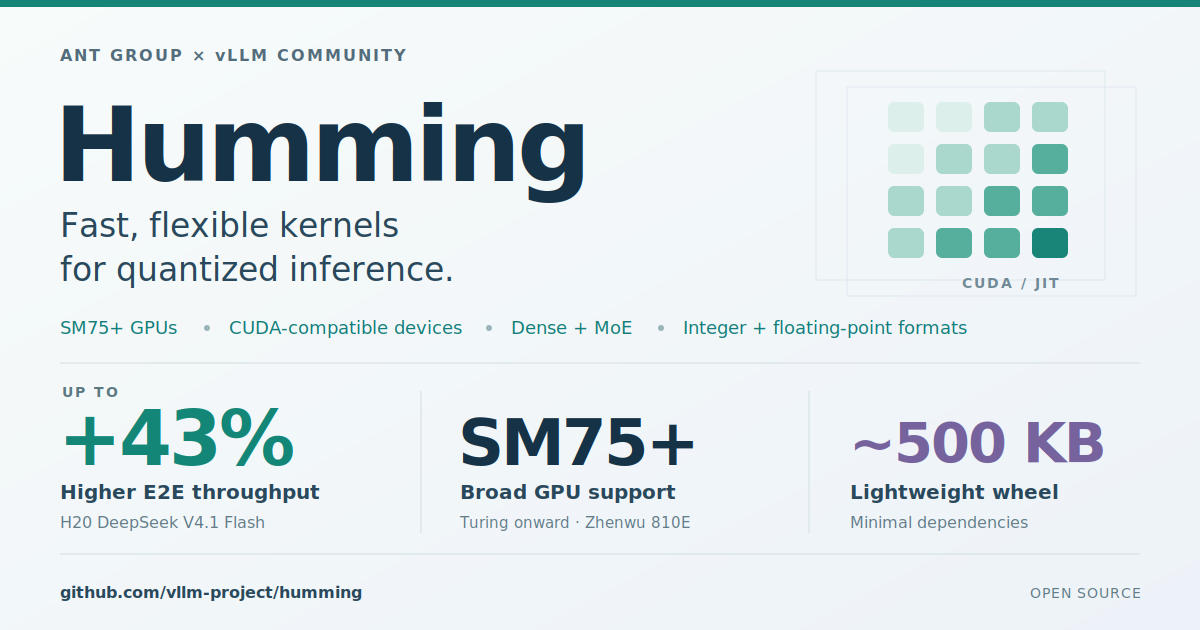
The vLLM project team and Ant Group officially open-sourced Humming (humming-kernels), a specialized high-performance kernel library designed for serving quantized MoE and dense LLMs at massive scale. Humming natively supports WnA16, W8A8, W4A8, and W4A4 across INT1–INT8 and FP4–FP8 formats, spanning NVIDIA architectures from Turing through Blackwell as well as T-Head Zhenwu 810E silicon. In production benchmarks, Humming kernels outpace cuBLAS by 3–4x at small batch sizes and surpass Marlin by 2x on H200 clusters. Serving DeepSeek-V4.1-Flash across 8x H20 GPUs, Humming drives a +43.3% throughput gain under 64 concurrent requests while reducing time-to-first-token (TTFT) by 32%, pre-integrated directly into vLLM v0.29.0+.

vLLM and Ant Group Open-Source Humming: Up to 5x Kernel Acceleration and +43.3% MoE Throughput

Key Takeaways

  • vLLM and Ant Group open-sourced Humming (humming-kernels), integrated out-of-the-box into vLLM v0.29.0+
  • Covers WnA16, W8A8, W4A8, and W4A4, compiling JIT kernels in just 1.82 seconds versus 23.35 seconds for CUTLASS
  • Serving DeepSeek-V4.1-Flash on 8x H20 GPUs yields a +43.3% throughput boost at 64 concurrency (442 to 634 tokens/sec)
  • Cuts time-to-first-token (TTFT) by 25% to 32% while delivering up to 5x kernel speedups on Blackwell B300 systems
Read full story

vLLM and Ant Group open-source Humming, one quantized-inference kernel library for many formats and every NVIDIA GPU since Turing, lifting DeepSeek-V4.1-Flash end-to-end throughput by 14-43%

On Oct 21 the vLLM community and Ant Group open-sourced Humming (Apache 2.0), a quantized-inference library that JIT-compiles GEMM kernels on demand. It supports every NVIDIA architecture from Turing on plus T-Head's Zhenwu 810E, and covers weight and activation combinations from INT1-INT8 and FP4-FP8 for dense and MoE workloads. In vLLM's microbenchmarks it runs 2-5x faster than vLLM Marlin, FlashInfer or DeepGEMM in some cases; on 8 H20 GPUs, switching DeepSeek-V4.1-Flash MoE from Marlin W4A16 to Humming W4A8 raised throughput 14-43%. vLLM 0.29.0 ships it built in.

vLLM and Ant Group open-source Humming, one quantized-inference kernel library for many formats and every NVIDIA GPU since Turing, lifting DeepSeek-V4.1-Flash end-to-end throughput by 14-43%

Key Takeaways

  • One JIT kernel framework instead of a hand-written kernel per format: WNA16, W8A8, W4A8, W4A4, INT1-INT8 and FP4-FP8 weights, dense and MoE
  • Hardware: every NVIDIA GPU from Turing (SM75) on, including Blackwell SM100/103/120/121, plus T-Head Zhenwu 810E
  • End to end: DeepSeek-V4.1-Flash on 8x H20 at TP=8, Humming W4A8 beats Marlin W4A16 by 14-43% in throughput and cuts mean TTFT 25-32%; at concurrency 64 output goes from 442 to 634 tok/s
  • Microbenchmarks run by the vLLM community: W4A8-MXFP4 on H200 is about 4.5x DeepGEMM W8A8, and the B300 MoE Grouped path is about 5x Marlin; one W4A16 kernel compiles in 1.82 s versus 23.35 s for CUTLASS
  • Use: pip install humming-kernels (about a 500 KB wheel); built into vLLM 0.29.0+, enable with --linear-backend humming --moe-backend humming
Read full story