On Oct 27 OpenBMB (ModelBest) open-sourced the MiniCPM-OCR suite with two models: MiniCPM-OCR 1.0, a 1.3B-parameter document parser that scores 93.68 on Real5-OmniDocBench and 54.7 on OCRBench v2 (vendor-reported), and MiniCPM-OCR Jev, a 2B OCR quality judge that scores any parser's output region by region from 0 to 1 and flags content that needs human review. Code and weights are Apache 2.0, with day-one support for vLLM, SGLang, llama.cpp, Ollama and multiple chip platforms.
Zoom
Key Takeaways
MiniCPM-OCR 1.0 has just 1.3B parameters and scores 93.68 on Real5-OmniDocBench and 54.7 on OCRBench v2 (vendor-reported, both claimed SOTA)
The 2B MiniCPM-OCR Jev judge reaches 93.6 AUROC on JevOCRBench, above JEV-35B-A3B at 90.1 and close to Qwen3.5-397B-A17B at 93.8 (vendor-reported)
Jev is parser-agnostic: AUROC stays between 91.9 and 93.4 on outputs from MiniCPM-OCR, GLM-OCR, PaddleOCR-VL-1.6 and Xiaomi-OCR-0
Throughput is about 1.49x PaddleOCR-VL-1.6 and 3.62x MinerU2.5 Pro, reaching up to about 128 pages per minute with SDK concurrency (vendor-reported)
Code and weights on GitHub are all Apache 2.0, with GGUF/AWQ/GPTQ quantized builds and a SKILL.md for coding agents
On Oct 28 DiffuSpace, whose members come from the HKU NLP group behind Dream 7B, released its first model, Clover-35B-A3B-Preview: a mixture-of-experts diffusion language model initialized from Qwen3.6-35B-A3B, with 35B total and about 3B active parameters, a 128K context window and block-parallel denoising. Vendor-reported results include 73.6 on SWE-bench Verified, 51.7 on Terminal-Bench 2.1 and 83.8 on GPQA Diamond, with 680 tokens/s on a single GB300 in agent workloads. Weights are Apache 2.0 on Hugging Face, ModelScope and GitHub, with SGLang and llama.cpp support.
Zoom
Key Takeaways
A 35B-total, roughly 3B-active MoE diffusion model initialized from Qwen3.6-35B-A3B, with 128K context and a thinking mode
DiffuSpace says it tops all six agent benchmarks it compared: SWE-bench Verified 73.6, Terminal-Bench 2.1 51.7 and tau3 Overall 65.3, ahead of LLaDA2.2 flash, Mercury 2.5 and Qwen3.6-35B-A3B
Speed (vendor-reported): 680 tokens/s on one GB300 at BF16 and batch size 1 in agent workloads, and 515 tokens/s on one H200 versus 365 tokens/s for Qwen with DFlash2
An INT4 build runs on a 16GB RTX 5070 Ti at 101.8 tokens/s on MATH-500
Weights on Hugging Face are Apache 2.0, about 69GB in BF16, and SGLang is the recommended serving path
In an Oct 26 incident report on its blog, Cloudflare said that between Aug 27 and Sep 9, 155 responses from GLM-5.3 on Workers AI (@cf/zai-org/glm-5.3) to prompts longer than 681,280 tokens contained data from other customers' recent requests, all returned with HTTP 200. The cause was a prefill KV cache pool smaller than the 1,048,576-token context window, combined with an SGLang bug in disaggregated prefill/decode mode. Cloudflare found no evidence of deliberate exploitation, has fixed it, and recommends operators upgrade to SGLang v0.5.22 or later.
Zoom
Key Takeaways
Scope: 155 responses between 2026-08-27 and 09-09, all to prompts over 681,280 tokens; Cloudflare confirmed no other Workers AI model was affected
Cause 1: GLM-5.3 advertised a 1,048,576-token context but the prefill KV pool held only 681,280 tokens; after the fix the pool holds about 2.04 million tokens, roughly twice the context
Cause 2: SGLang marked over-length requests as rejected and swapped in a one-token placeholder without aborting, so the decode node read stale cache pages from earlier requests
Response: report from Gadi Evron of Knostic via HackerOne on Sep 8; model taken offline within 40 minutes of declaring the incident on Sep 9 and restored at 19:40 UTC that day
Action: teams running SGLang should upgrade to v0.5.22 or later and check KV pool size against context length directly
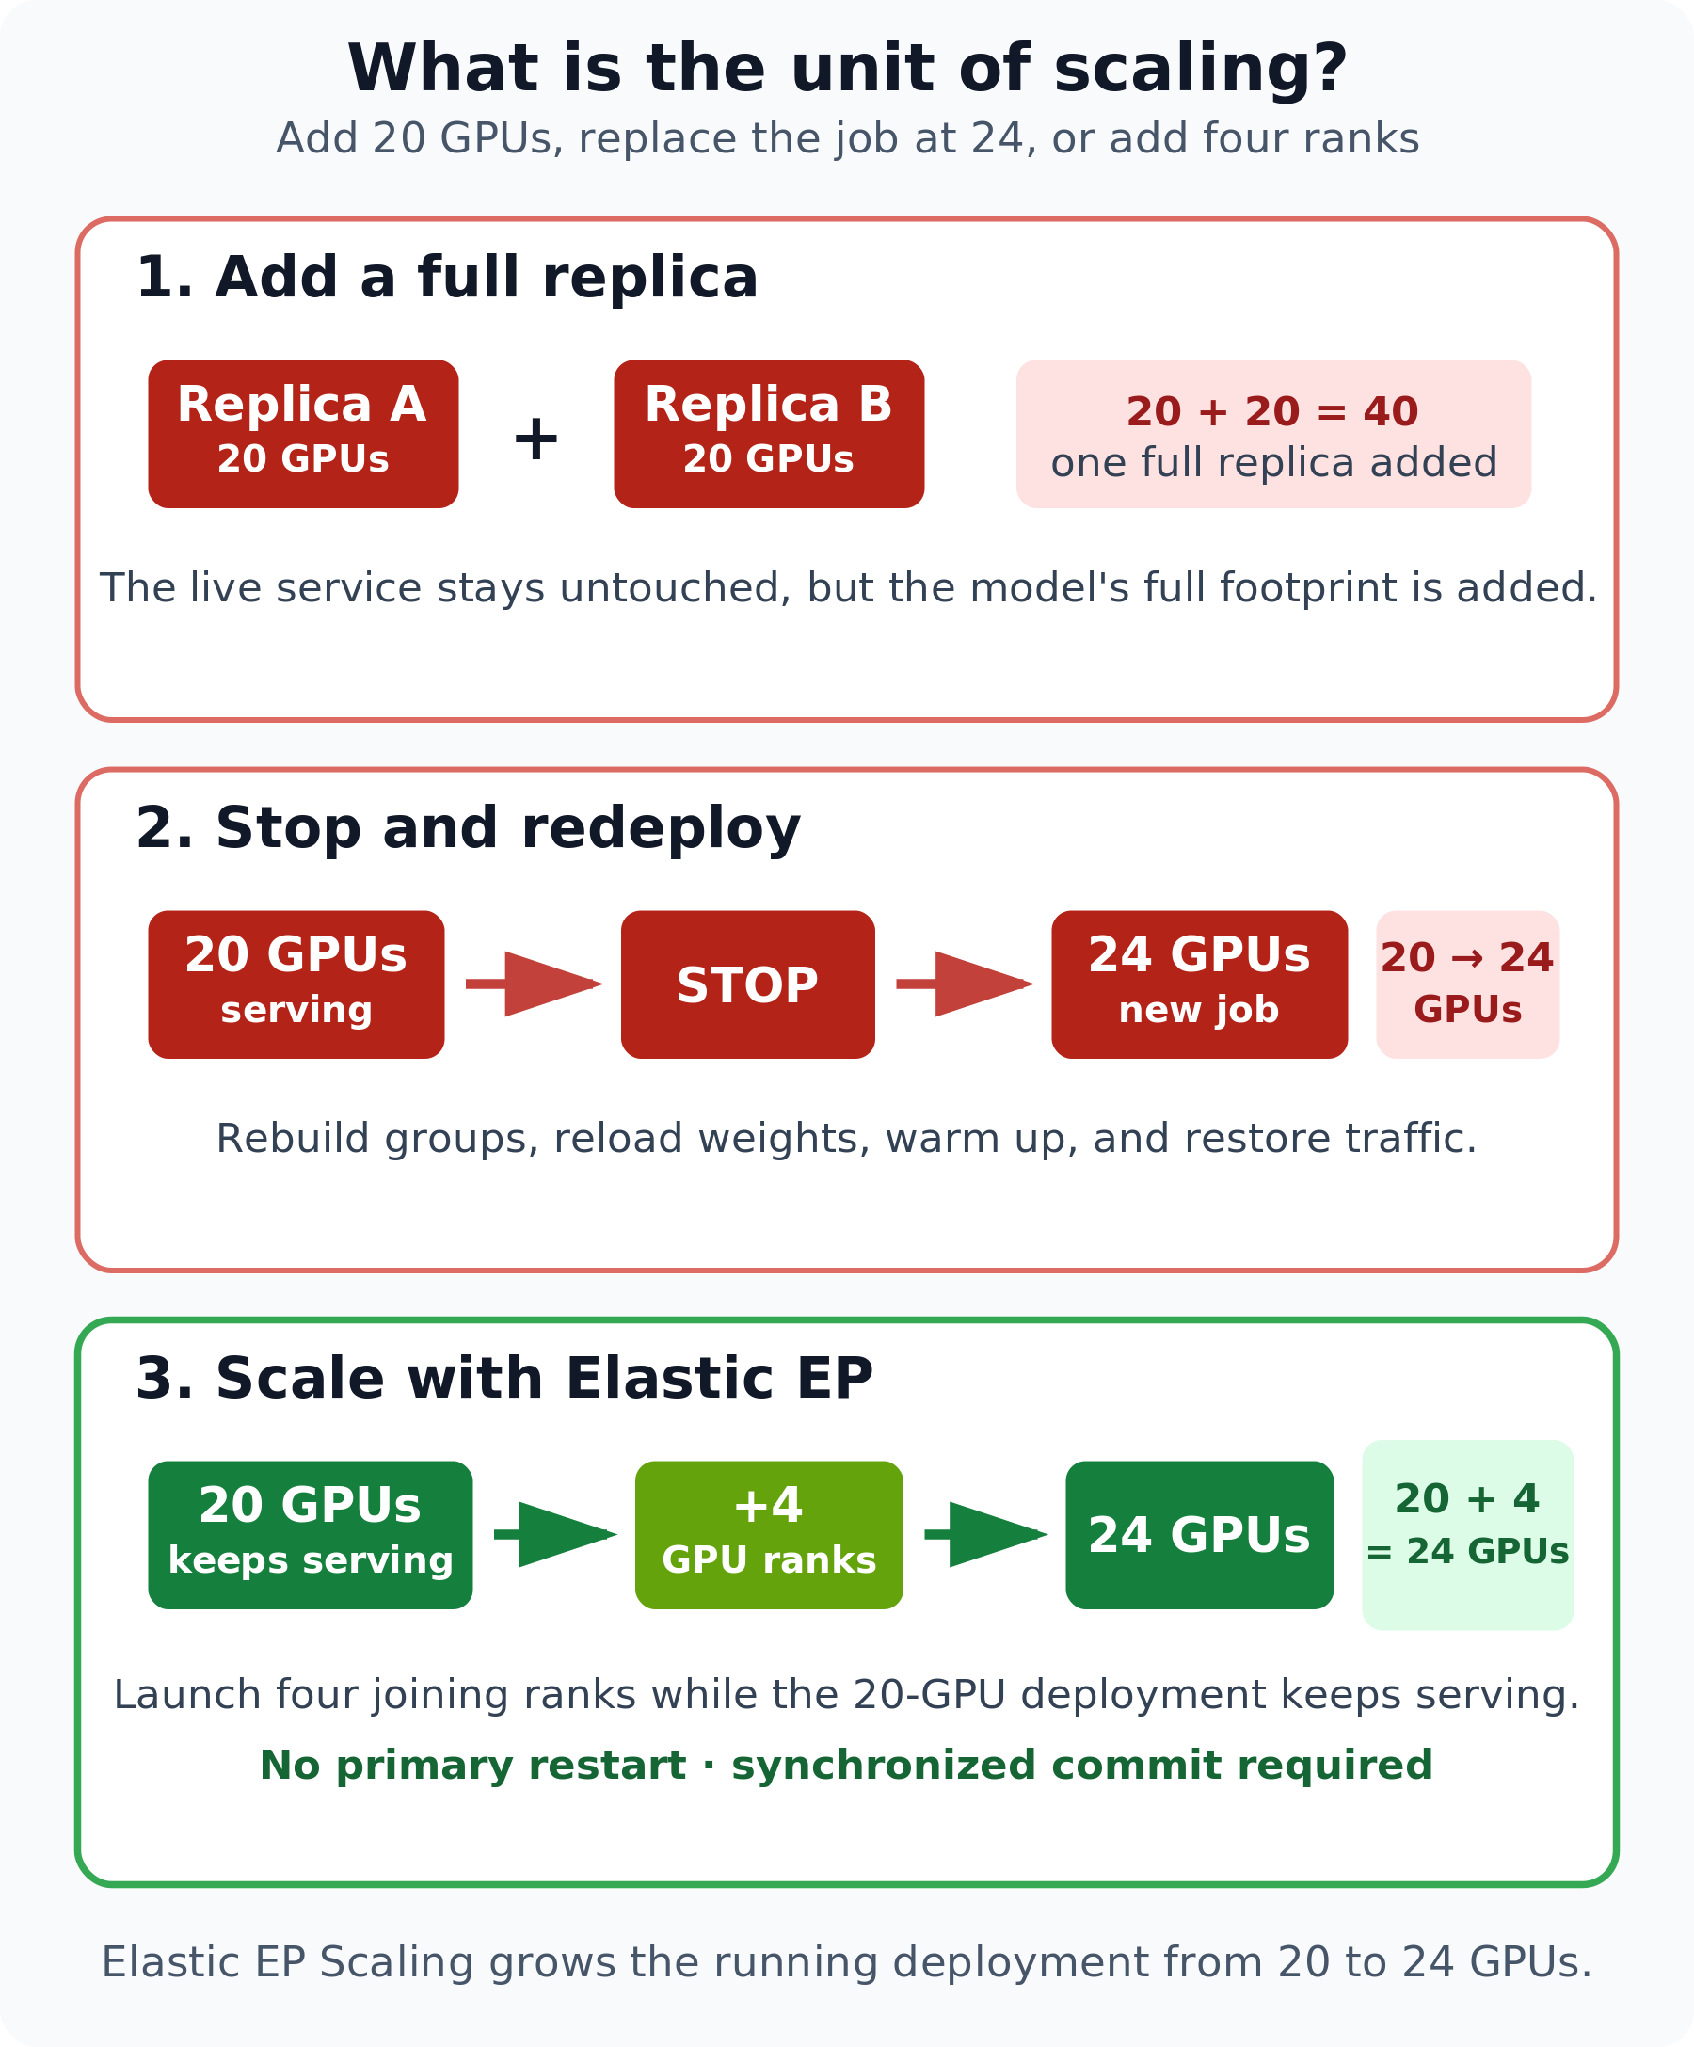
LMSYS Org in collaboration with the NVIDIA Dynamo team officially unveiled Elastic Expert Parallelism (Elastic EP) with NIXL backend integration in SGLang (@lmsysorg). Addressing the critical vulnerability of large-scale MoE deployments (such as DeepSeek-V3/V4) where static EP causes entire cluster crashes upon single-node failures and prevents live capacity resizing, Elastic EP decouples rigid expert-to-GPU bindings. Leveraging NVIDIA NIXL device APIs and Mooncake orchestrators, SGLang enables live scaling of active MoE serving deployments (e.g. dynamically expanding from 20 to 24 GPUs) without draining traffic or restarting clusters, while delivering resilient fault tolerance.
Zoom
Key Takeaways
LMSYS Org and NVIDIA Dynamo team roll out Elastic EP in SGLang, enabling live scaling of production MoE clusters
Eliminates the single-point-of-failure bottleneck in static EP deployments, enabling instantaneous fault-tolerant degradation
Integrates NVIDIA NIXL device primitives (--moe-a2a-backend nixl) with native RDMA and NVLink zero-copy token routing
Demonstrates zero-downtime live expansion, seamlessly growing active deployments (e.g. from 20 to 24 GPUs) under live query load
Google Cloud officially open-sourced TorchTPU, enabling native, zero-compilation-barrier PyTorch execution directly on Google Cloud TPU hardware (TPU v5p and TPU v6e). Overcoming the legacy friction of PyTorch/XLA's rigid graph compilation and dynamic-shape stalls, TorchTPU supports native PyTorch eager execution and custom Triton/C++ kernels. Leading high-throughput serving engines vLLM and SGLang announced immediate Day-0 support. Concurrently, Google Cloud introduced OpenAI models and Codex into its Vertex Model Garden, becoming the first hyperscaler to offer all three top frontier closed models.
Zoom
Key Takeaways
Google Cloud open-sources TorchTPU, delivering native, compilation-free PyTorch execution on TPU v5p and TPU v6e hardware
On Oct 20, inference company Eagle released EAGLE-4, the fourth generation of the EAGLE speculative-decoding family. One drafter resizes its speculative tree for the batch size, hardware and workload while keeping the target model's output distribution. Eagle reports 961.6 tokens/s for one request on Qwen3.8-27B with 4x B300. The code ships as eagle-harness v0.1.0 with plugins for SGLang, vLLM and an experimental TokenSpeed backend. Many reposts call it open source, but the official license is source-available, not OSI open source.
Zoom
Key Takeaways
Vendor figure: 961.6 tokens/s on Qwen3.8-27B with TokenSpeed, BF16, 4x B300, TP4, one request, T=0 (paper Figure 1(a))
Repo measurements: vLLM on 4x B300 goes from 241.6 to 722.8 tok/s at concurrency 1 (2.99x) and 1.70x at concurrency 8; SGLang gets 1.91x at concurrency 8 and 1.35x at 64
AMD numbers too: SGLang on one MI355X gets 2.07x at concurrency 8 and 1.56x at 32 (ROCm 7.2)
Design: sliding-window draft layer, low-rank candidate head and append-only draft cache; the harness calibrates verify latency offline and grows the tree while gain per cost stays high
License: Eagle 4 Source-Available; free for noncommercial use, commercial use only under $20M trailing 12-month revenue and outside competing offerings
At PyTorch Conference 2026 on Oct 20, Google open-sourced TorchTPU on GitHub, co-developed with Meta's PyTorch team, making TPUs a native PyTorch device alongside GPUs and CPUs: eager mode and torch.compile, about 450 ATen ops, and torch.distributed collectives. Google also released vLLM-TorchTPU and SGLang-TorchTPU engines, integrations with TorchTitan, Ray, VeRL and Hugging Face Transformers v5 (device_map="tpu"), and a preview TPU agent suite for coding assistants such as Claude Code and Antigravity. AWS shipped the comparable TorchNeuron a day earlier.
Zoom
Key Takeaways
Porting (official PyTorch blog): existing code runs by changing model.to("cuda") to model.to("tpu") and the distributed backend to tpu_dist; the team notes peak TPU performance still needs TPU-aware shapes and sharding
Coverage (vendor-reported): 98% of about 4,917 popular Hugging Face models (4,821) run without crashing, and 97% of 657 architecture representatives (638) match GPU numerics
Training scale (vendor-reported): Qwen3 MoE 235B on TorchTitan scales from 1,024 to 8,192 TPU v7 chips with MFU roughly flat at 27-29%; on 64 TPU v7 chips it reaches 1,828 TPS versus 1,937 TPS for JAX/MaxText
Inference cost (Google citing SemiAnalysis InferenceX): TPU v7 with vLLM-TorchTPU hits 2.01 cents per million tokens on 8K/1K, down from 3.6 cents at its September debut
Four repos open-sourced: torch_tpu, vllm-torchtpu, sglang-torchtpu and a TPU TorchTitan; the TPU agent suite is in preview for TPU v6e and TPU7x
The Ornith AI team officially released Ornith-1.5-122B under the permissive MIT license, a 122-billion parameter mixture-of-experts (MoE) reasoning model optimized to execute on a single GPU node (such as a single DGX). The model is immediately available across vLLM (0.19.1+), SGLang (0.5.9+), Hugging Face, and Ollama (ornith-1.5:122b) with native FP8, GGUF, and MLX quantization. Across independent agentic evaluations in the OpenHands harness, Ornith-1.5-122B registered 84.5 on SWE-bench Verified, 76.9 on SWE-bench Pro (surpassing Qwen3.8-Flash-Next's 43.9 by 33 points), 81.2 on TerminalBench 2.1, and 74.6 on MCP-Atlas.
Zoom
Key Takeaways
Ornith-1.5-122B released under the permissive MIT license, offering a fully open, frontier-grade 122B MoE coding reasoning model
Engineered to fit inside a single GPU node (single DGX), with immediate runtime support on vLLM, SGLang, and Ollama (ornith-1.5:122b)
Achieves 76.9 on SWE-bench Pro, drastically outperforming the comparable open-weight baseline Qwen3.8-Flash-Next (43.9)
Delivers balanced agentic performance with 81.2 on TerminalBench 2.1, 80.0 on CyberGym, and 74.6 on MCP-Atlas
DeepSeek officially open-sourced DeepInfer under Apache 2.0, its production-grade inference engine serving DeepSeek-V4.1-Flash at scale. Originating from vLLM with architectural refinements from SGLang and TensorRT-LLM, DeepInfer natively targets NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. It integrates specialized kernels including FlashMLA, DeepGEMM, DeepEP, and TileKernels. The engine features DSpark confidence-scheduled speculative decoding with 5-token drafts, SWA bounded replay over a 140-token sliding window, and balanced MoE expert parallelism. DeepSeek simultaneously open-sourced deepseek-recipe, delivering an end-to-end open ecosystem across models, kernels, and inference runtimes.
Zoom
Key Takeaways
DeepSeek officially open-sourced DeepInfer under Apache 2.0, releasing the production codebase powering DeepSeek-V4.1-Flash at massive scale
Natively optimized for both NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs with deterministic, batch-independent output guarantees
Integrates custom FlashMLA, DeepGEMM, DeepEP, and TileKernels, alongside DSpark 5-token speculative decoding and 140-token SWA replay
Simultaneously released deepseek-recipe, aligning open-source local deployments perfectly with DeepSeek's official production API tokenization
At PyTorch Conference North America on Oct 20, the CNCF Sandbox project llm-d released version 1.0. It turns inference engines such as vLLM and SGLang into one coordinated serving pool, and 1.0 adds multi-tenant priority and fairness scheduling (flow control), router high availability with zero-downtime rolling upgrades (DisaggregatedSet), a v1 configuration API, and agent-aware session routing with Responses API state. Founded in 2025 by Red Hat, IBM, Google Cloud, CoreWeave and NVIDIA, the project has 500+ contributors, and JetBrains, DigitalOcean and Mistral already run it in production.
Zoom
Key Takeaways
Scale (Red Hat press release, vendor-reported): GLM 5.2, roughly 753B parameters, on NVIDIA GPUs peaked at 6.6M output tokens per minute and served up to 3,000 concurrent coding agents with zero preemptions, 5-10x cheaper per token than equivalent commercial API pricing at cloud rental rates
Cache reuse: IBM says the prefix-aware router captured 97% of available cache reuse on an agentic coding workload; an IBM Research quantum error correction project saw ~98% prefix hits, ~$0.11 per million tokens, and 11.5x lower cost than an all-proprietary setup
Google Cloud figures: on Ironwood TPU, prefix-aware routing plus host memory offload cut median time-to-first-token by more than 85% and raised throughput 2.4x on an agentic coding workload; the Gemini platform doubled its prefix cache hit rate from 35% to 70%
New in 1.0: flow-control multi-tenant QoS, router hot-standby HA, DisaggregatedSet for coordinated prefill/decode rollouts, a v1 config API, and previous_response_id support in the Responses API
Ecosystem: 500+ contributors from 25+ organizations; JetBrains' free Junie Lite, DigitalOcean Serverless Inference and Mistral's tiered commercial traffic run on it; the GitHub v1.0.0 notes admit not every tracked goal shipped
On October 19 Ant Ling (inclusionAI) open-sourced five Ming-3.0 models under MIT, spanning speech synthesis (tts-0.5B; tts-tiny, 7.9B total/1.3B active), audio understanding (audio-flash, 126B/6.5B active; audio-tiny, 9.3B/2.7B active) and speech recognition (asr-tiny, 8.6B/2B active). Per the vendor, tts-0.5B ranks #1 among open-weight models on Artificial Analysis Controlled Voice at 1069 Elo and ties #1 overall on pronunciation robustness at 93.2%; asr-tiny averages 4.41% error across four ASR categories. Weights are on Hugging Face and ModelScope, with day-0 SGLang and vLLM support.
Zoom
Key Takeaways
Lineup: five models in three families, two TTS, two audio-understanding and one ASR, all MIT-licensed.
TTS results: tts-0.5B scores 1069 Elo on AA Controlled Voice, #1 among open weights; 1188 Elo and #3 on Provider Voice; ties #1 overall on pronunciation robustness at 93.2% (vendor figures).
TTS features: 7 languages plus Sichuanese and Cantonese, 14 inline paralinguistic tags (laughter, sighs, coughs and more), 44.1 kHz output, built on Qwen2.5-0.5B.
Audio understanding: audio-flash has 126B total and 6.5B active parameters, and handles long-recording summaries, spoken Q&A, audio reasoning and tool-call generation.
ASR: asr-tiny accepts hotwords and dialogue context, is evaluated on 15 dialect test sets, and averages 4.41% error across four categories (vendor figures).
The SGLang team released v0.5.22 featuring 950 PRs from 245 contributors: DeepSeek-V4.1 delivers up to 2.3x more throughput per GPU on NVIDIA H200 and 1.9x on AMD MI350X/MI355X via DSpark. The new InstantTensor loader cuts model loading time by 10x. B200 decodes Qwen3.8-Flash-Next 12% faster, while B300 speeds up GLM-5.3-Flash by 10% and yields 1.85x decode throughput for MiMo-V2.6-Pro. SGLang also adds native Apple Silicon PyTorch support and ComfyUI integration.
Zoom
Key Takeaways
SGLang v0.5.22 released with 950 PRs from 245 contributors across heterogeneous platforms
DeepSeek-V4.1 achieves up to 2.3x throughput per GPU on NVIDIA H200 and 1.9x on AMD MI350X/MI355X via DSpark
New InstantTensor loader speeds up large model checkpoint ingestion by 10x
Qwen3.8-Flash-Next decodes 12% faster on B200; MiMo-V2.6-Pro reaches 1.85x decode throughput on B300
PD disaggregation cuts p95 TTFT in half (-50%) on long prompts, alongside native Apple Silicon and ComfyUI diffusion support
On 2026-10-12 OpenBMB released MiniCPM-V 4.7, an Apache-2.0 open multimodal family with a 35B-A3B variant (the series' first MoE) and a 1B variant. Its Lookahead Expert Scheduling (LES) prefetches experts across layers and, combined with layer-wise mixed-precision quantization and DSpark speculative sampling, lifts SSD-offloaded decoding on an iPad Pro M4 (16GB) from 2.97 to 17.39 tokens/s (5.86x), per OpenBMB. Weights are on Hugging Face, ModelScope and Ollama, with vLLM, SGLang, llama.cpp and iOS/Android/HarmonyOS support.
Zoom
Key Takeaways
Two Apache-2.0 open-weight models: 35B-A3B (first MoE in the series, Qwen3.6 language backbone) and 1B, plus FP8 / AWQ / GPTQ / int4 / GGUF builds and DSpark draft models (Hugging Face)
LES on-device decode (OpenBMB, iPad Pro M4 16GB): baseline 2.97 → LES 9.81 → +layer-wise quant 14.92 → +DSpark 17.39 tokens/s, 5.86x overall (LES doc)
35B-A3B reaches 13+ tokens/s on iPhone 17 Pro Max; mixed 4x/16x visual-token compression trades detail for cost per task
Vendor-reported (Instruct, 4x): MMBench 91.72, OCRBench 91.20, OmniDocBench v1.6 94.24, MMMU 80.22 vs Qwen3.6-35B-A3B at 86.76 / 86.00 / 80.17 / 77.44; still behind on SimpleVQA and ScreenSpot
Day-0 chip support for Rockchip, Houmo, Intel, AMD and Arm; runs on vLLM, SGLang, llama.cpp and Ollama; fine-tune via SWIFT / LLaMA-Factory
On 2026-10-16 Hugging Face and Reflection confirmed Beam weights are downloadable: ~501B-total / ~23B-active sparse MoE, 1M context, Apache 2.0. BF16/FP8/NVFP4 checkpoints ship with day-0 transformers≥5.20.1, vLLM and SGLang. Model-card figures (vendor): SWE-bench Verified 81.6% (BF16), Terminal-Bench 2.1 80.1%, MCP Atlas 80.8%. This closes the Oct 5 promise to release weights later that month.