
GitHub updated Copilot Fusion, its runtime router that picks and orchestrates models for each task, on November 17. Fusion is now listed on the public Terminal-Bench 4.1 leaderboard hosted by Stanford, Harbor and the Laude Institute, where Fusion Max resolves 71.2% of tasks, 5.4 points ahead of Claude Opus 5.5 and Fable 5.2 in Claude Code, which tie for second, at 57% and 88% lower cost. Fusion can now also be selected on github.com, in Visual Studio and in the GitHub Mobile beta apps. The model pool changed too: Claude Sonnet 5.5 joins Fusion Max, GPT-6.1 Terra joins Fusion High, and Microsoft's new MAI-Code-2 joins Fusion Standard.
Key Takeaways
- ✓Public Terminal-Bench 4.1 leaderboard: Copilot Fusion (max) is first at 71.2% plus or minus 2.9%, Opus 5.5 (max) and Fable 5.2 (max) tie for second at 65.8%, and Gemini 4 Carbon (high) is fourth at 64.5%
- ✓Cost: the leaderboard shows Fusion Max used 3.3B tokens and about $2.0k for the full run, versus about $4.7k for Opus 5.5 and about $16.5k for Fable 5.2
- ✓How it works: Fusion is not a single model but a runtime router that picks one of three execution patterns per prompt: Single, Cascade (a cheaper model drafts and a judge decides whether to escalate) or Critique (several models critique in parallel before a revision)
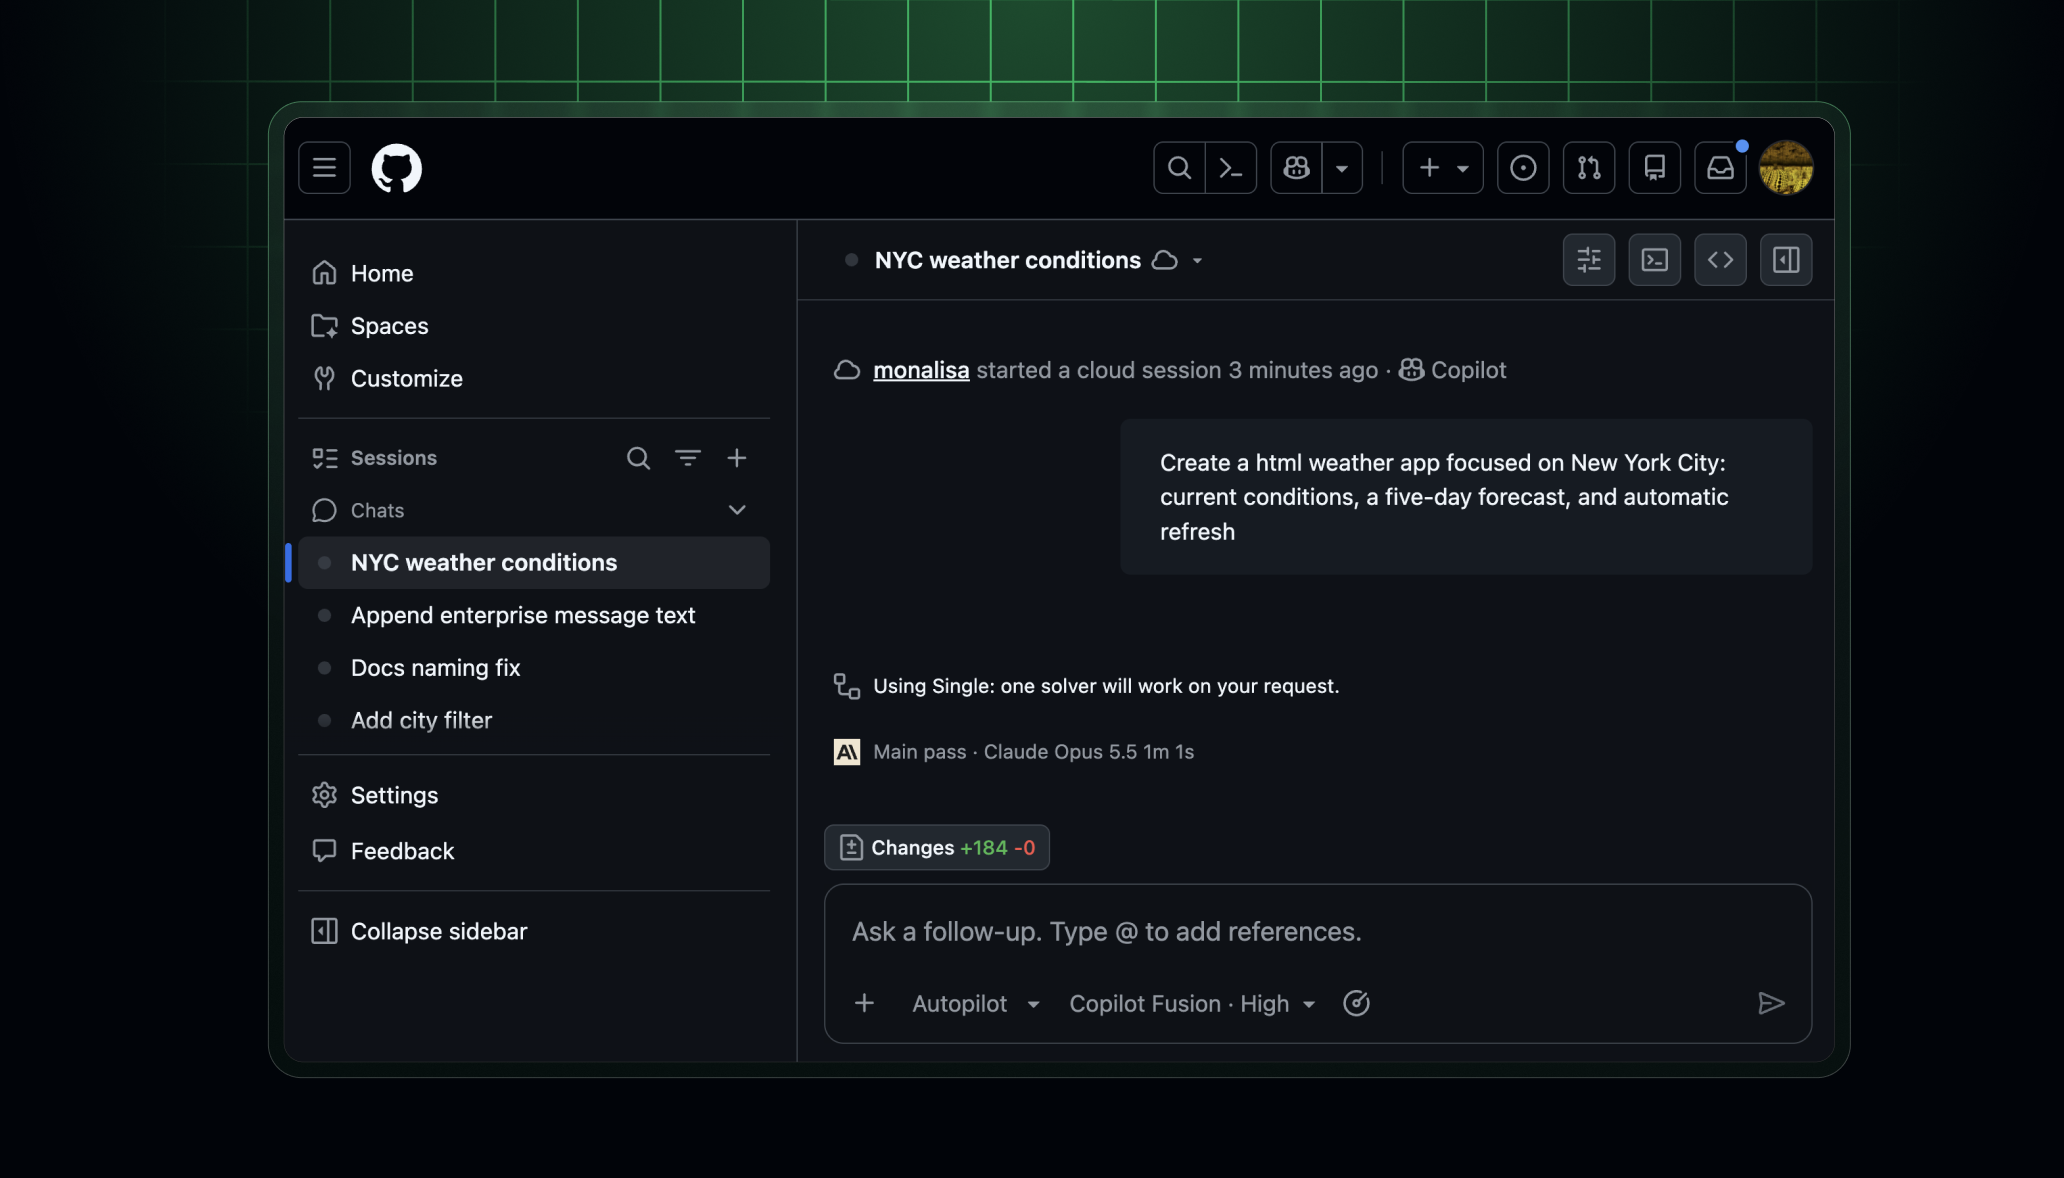
- ✓New surfaces: Fusion can be selected on github.com, in Visual Studio and in the GitHub Mobile beta apps for iOS and Android, with production mobile apps coming shortly
- ✓Model pool: Claude Sonnet 5.5 joins Fusion Max, GPT-6.1 Terra joins Fusion High and MAI-Code-2 joins Fusion Standard; usage is billed at each model's standard rate, with a 30% model cost discount for paid plans through November 30
Key Decision Metrics at a Glance
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Background
Within one session, some steps are fine on a cheap model while others need the strongest one, and switching by hand is tedious and easy to overspend on. GitHub made Copilot Fusion, a runtime router built for this, generally available in late October, and updated it on November 17.
How it works
Fusion is not a single model. For each prompt it picks one of three execution patterns: Single (one model does the task), Cascade (an efficient model drafts and a judge decides whether to escalate to a stronger one) or Critique (several models critique in parallel and the original model revises). Users only pick an effort level such as Standard, High or Max, and pay each model's standard rate.
Numbers that matter
Fusion is now on the public Terminal-Bench 4.1 leaderboard. Fusion Max resolves 71.2% of tasks and ranks first, while Opus 5.5 and Fable 5.2 in Claude Code tie for second at 65.8%. GitHub says Fusion Max costs 57% and 88% less than those two, and the leaderboard lists its full run at about $2.0k.
What it means for developers
Beyond VS Code, Copilot CLI and JetBrains, Fusion now appears in the model picker on github.com, in Visual Studio and in the GitHub Mobile beta apps. New in the pool: Sonnet 5.5 in Max, GPT-6.1 Terra in High and MAI-Code-2 in Standard. Paid plans get 30% off model costs through November 30.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.